
What You'll Build Today
By the end of this lesson, you'll have created a complete predictive analytics system that includes:
Core Forecasting Engine
Four different prediction models (ARIMA, Prophet, LSTM, Exponential Smoothing)
Intelligent ensemble system that combines all models for better accuracy
Real-time confidence scoring and alert generation
Production-Ready Infrastructure
REST API with health monitoring and metrics endpoints
Background processing for automatic model training and updates
Redis caching for fast prediction retrieval
Interactive Dashboard
Live charts showing predictions vs actual metrics
Confidence level indicators with color-coded alerts
Individual model comparison views
System health and performance monitoring
Enterprise Features
Configurable prediction horizons (15 minutes to 24 hours)
Automatic model retraining every 6 hours
Graceful degradation when models fail
Docker deployment with horizontal scaling support
Today's Mission: Transform Yesterday's Patterns Into Tomorrow's Predictions
Remember yesterday when your clustering system discovered that database connection errors spike every Tuesday at 2 PM? Today we're building the forecasting engine that predicts next Tuesday's spike 30 minutes early, giving your team time to scale resources proactively.
What You're Building: A predictive analytics engine that forecasts system behavior using machine learning models trained on your log patterns.
Real-World Impact: Netflix uses similar systems to predict streaming demand and scale servers before users even click play. AWS forecasts resource needs across millions of instances. Your system will do the same for log processing.
The Forecasting Challenge
Production systems generate predictable patterns hidden in chaos. Your web servers show traffic patterns, database logs reveal performance cycles, and error logs follow failure patterns. The challenge isn't finding patterns—it's predicting when they'll happen next.
Traditional monitoring is reactive: alerts fire after problems occur. Predictive analytics is proactive: warnings arrive before issues impact users. This shift from firefighting to fire prevention transforms operations teams from reactive to strategic.

Core Architecture Components
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
Time Series Analyzer
Converts log patterns from yesterday's clustering into time-based sequences. Instead of "error logs cluster together," you get "error logs increase 15% every Monday morning at 9 AM."
Forecasting Engine
Uses multiple algorithms (ARIMA, Prophet, LSTM) to predict future values. Each algorithm excels in different scenarios—ARIMA for stable patterns, Prophet for seasonal trends, LSTM for complex relationships.
Prediction Validator
Tests forecasts against actual outcomes, automatically adjusting model parameters. Poor predictions trigger model retraining, ensuring accuracy improves over time.
Alert Orchestrator
Converts predictions into actionable alerts. Instead of "CPU will be high," it sends "Scale web servers by 3 instances in 25 minutes based on predicted traffic surge."
The Magic Behind Predictions
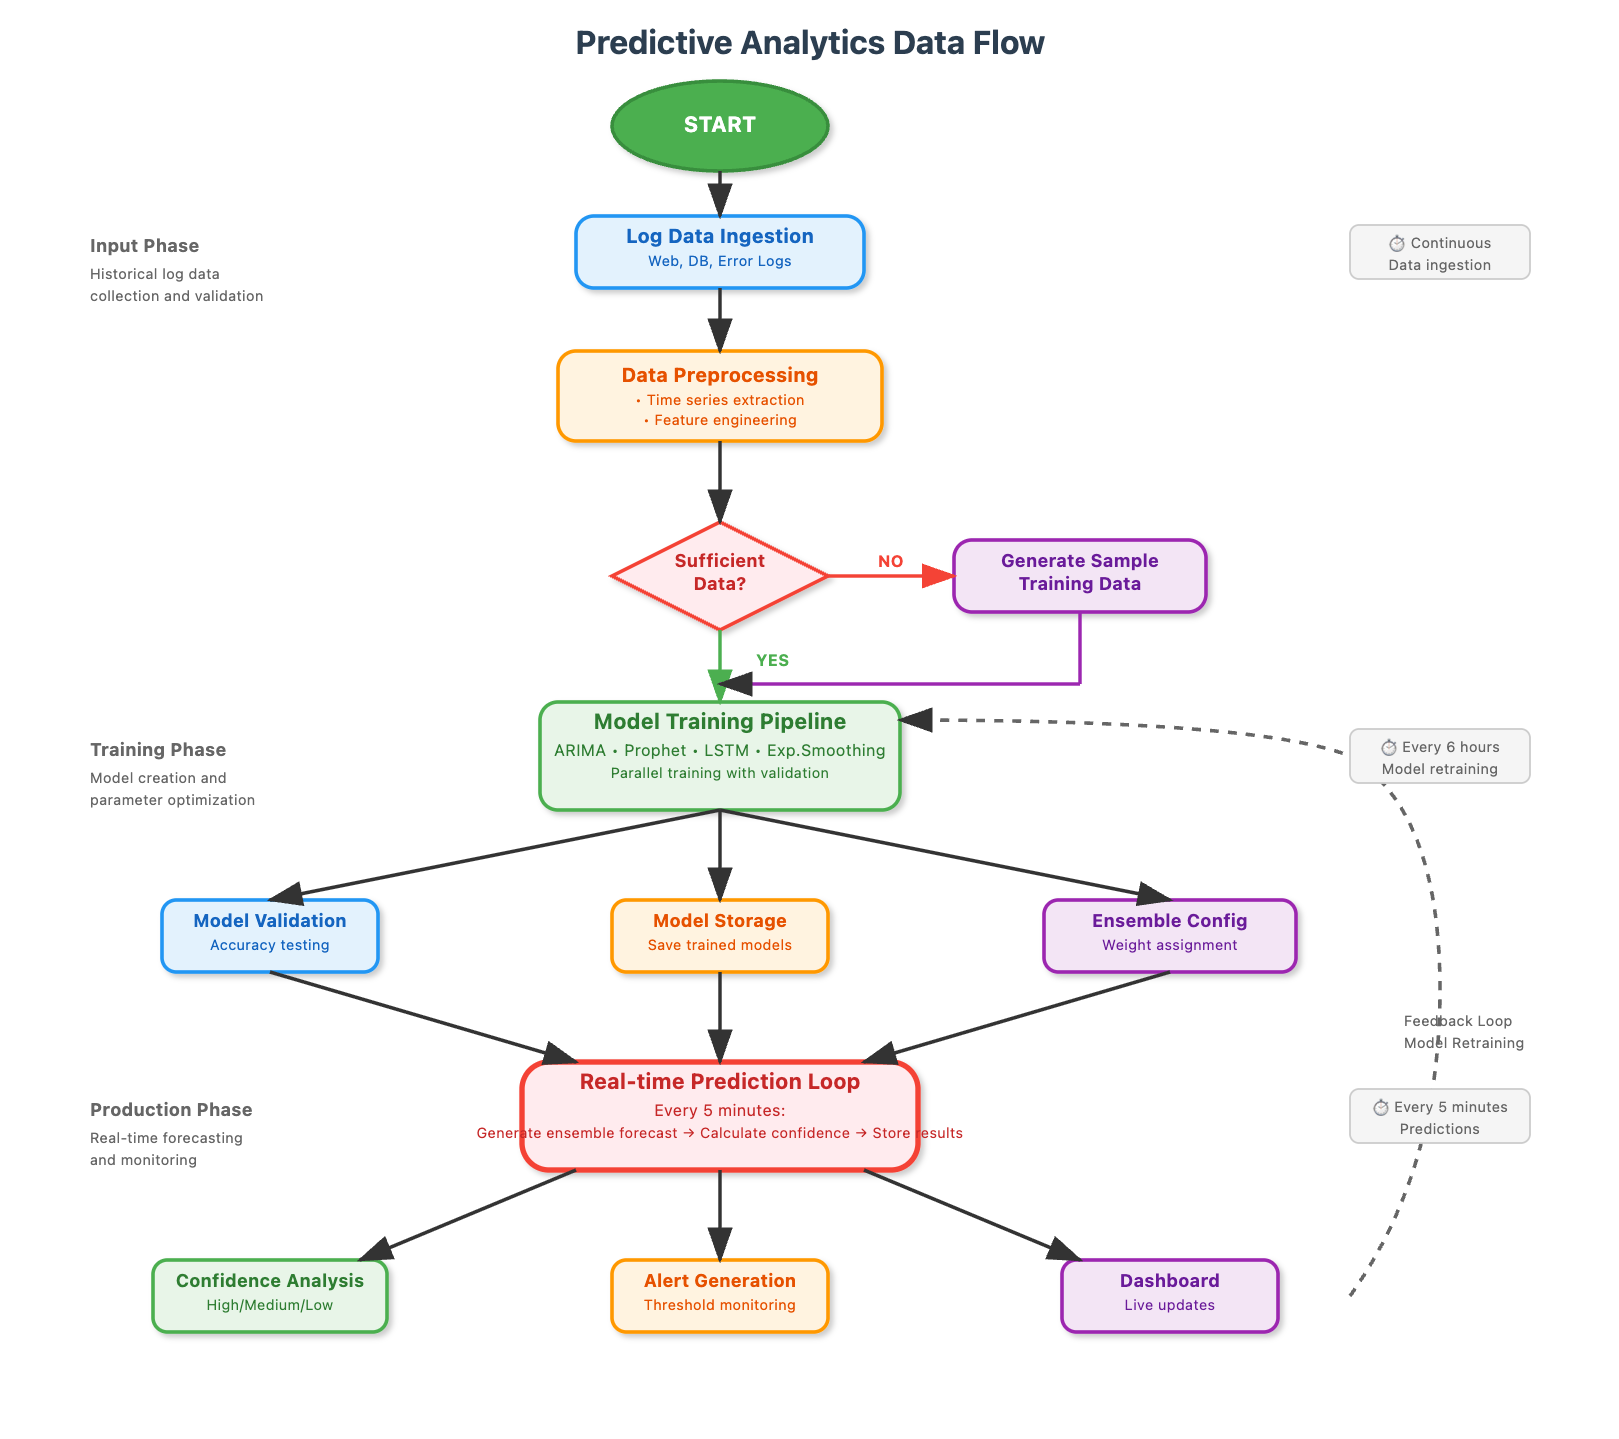
Data Pipeline Flow
Your clustering results feed the time series analyzer, which creates temporal datasets. The forecasting engine trains models on historical data, generating predictions validated against recent patterns. High-confidence predictions trigger proactive alerts.
Model Selection Strategy
Different log types need different prediction approaches. Error rates work well with ARIMA's statistical modeling. User activity patterns benefit from Prophet's holiday and seasonality handling. Complex system metrics require LSTM's deep learning capabilities.
Confidence Scoring
Every prediction includes confidence levels. High confidence (>85%) triggers automatic actions like scaling. Medium confidence (65-85%) notifies teams. Low confidence predictions (<65%) contribute to model training but don't generate alerts.
Implementation Deep Dive
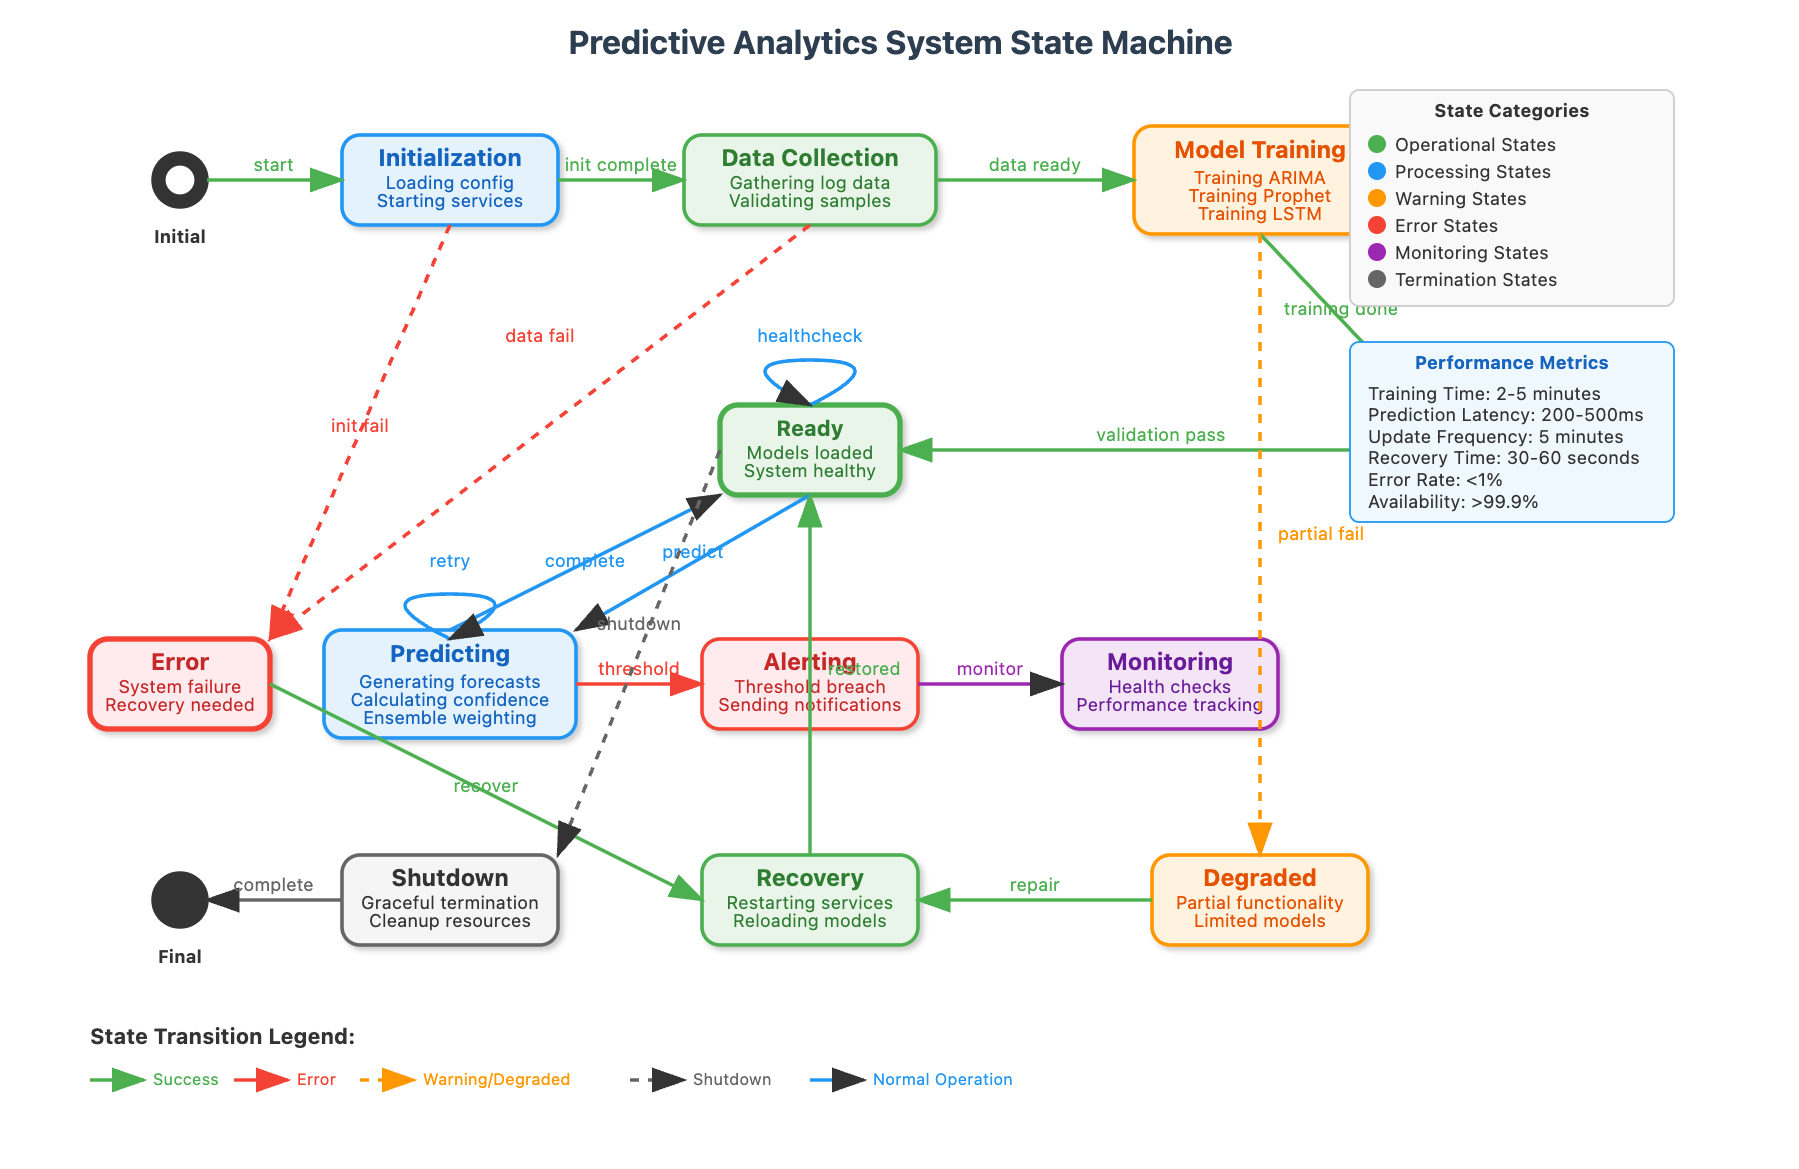
State Transitions
The system cycles through distinct states: Data Collection gathers recent log patterns, Model Training updates prediction algorithms, Forecasting generates future predictions, Validation compares predictions to reality, and Adjustment optimizes model parameters.
Real-Time Processing
Predictions update every 5 minutes using sliding windows of historical data. This balance provides fresh insights without overwhelming computational resources or generating prediction noise.
Integration Points
The forecasting engine connects to your existing cluster analysis (Day 79) for pattern input and tomorrow's recommendation system (Day 81) for action suggestions. This creates an intelligent feedback loop from pattern discovery to prediction to action.
Production Considerations
Scalability Patterns
Production forecasting systems handle thousands of metrics simultaneously. We implement efficient batch processing for model training and streaming updates for real-time predictions. Memory usage remains constant through sliding window techniques.
Model Lifecycle Management
Models degrade over time as system behavior changes. Our implementation includes automatic model evaluation, retraining triggers, and A/B testing for model improvements. This ensures predictions remain accurate as your system evolves.
Operational Integration
Predictions integrate with existing monitoring dashboards, alert systems, and auto-scaling policies. Teams see forecasts alongside current metrics, creating comprehensive situational awareness.
Success Metrics
Your forecasting system achieves success when:
Prediction Accuracy: >80% for 30-minute forecasts, >60% for 4-hour forecasts
Alert Quality: <10% false positive rate for high-confidence predictions
Response Time: Generate predictions within 30 seconds of new data
Resource Impact: Use <200MB memory per 1000 metrics tracked
Real-World Applications
E-commerce Platforms predict traffic spikes during flash sales, pre-scaling payment processing systems. Social Media forecasts viral content spread, preparing content delivery networks. Financial Services predict transaction volumes, ensuring fraud detection systems handle peak loads.
Your implementation demonstrates the same patterns used by major platforms to maintain performance during unexpected demand.
Key Implementation Insights
Time Window Selection
Short windows (1-4 hours) provide detailed predictions but miss long-term trends. Long windows (1-7 days) capture seasonal patterns but lack responsiveness. Our hybrid approach uses multiple windows, combining short-term precision with long-term trend awareness.
Feature Engineering
Raw log counts aren't sufficient for accurate predictions. We extract derivatives (rate of change), moving averages (trend smoothing), and pattern indicators (seasonal adjustments) to improve model performance.
Ensemble Forecasting
Single models fail in different scenarios. Our ensemble approach combines multiple algorithms, weighting their predictions based on recent accuracy. This provides more robust forecasts than any individual model.
Tomorrow's Foundation
Today's predictions become tomorrow's recommendation inputs. When the system predicts database connection issues, Day 81's recommendation engine suggests specific actions: connection pool adjustments, query optimizations, or hardware scaling.
This creates an intelligent operations pipeline: discover patterns, predict problems, recommend solutions. Your log processing system evolves from data collector to proactive system advisor.
Hands-On Implementation Guide
Building Production-Ready Predictive Analytics from Scratch
Learning Objectives
By the end of this hands-on session, you'll understand:
How to implement multiple forecasting models and combine them intelligently
Real-time data processing for continuous prediction updates
Production deployment patterns for scalable analytics systems
Dashboard development for operational visibility
Prerequisites
System Requirements:
Python 3.11+
Node.js 16+ (for React dashboard)
Redis server
4GB RAM minimum
2GB free disk space
Knowledge Prerequisites:
Basic understanding of time series data
Familiarity with Python and React
Understanding of REST APIs
Quick Start Options
GitHub Link:
https://github.com/sysdr/course-p/tree/main/day80/day80-predictive-analyticsOption 1: Complete Setup Script
bash
git checkout day80
cd day80/day80-predictive-analytics

./start.sh

# Access dashboard at http://localhost:3000
# API available at http://localhost:8080

./stop.sh
Option 2: Docker Deployment
bash
docker-compose up --build -d
# All services start automatically
Phase 1: Environment Setup
Create Project Structure
bash
mkdir day80-predictive-analytics && cd day80-predictive-analytics
mkdir -p {src/{forecasting,models,api,utils},tests,frontend,config,data,logs}
Python Environment
bash
# Create and activate virtual environment
python3.11 -m venv venv
source venv/bin/activate

# Install core dependencies
pip install --upgrade pip
pip install numpy==1.26.4 pandas==2.2.2 scikit-learn==1.4.2
pip install statsmodels==0.14.2 prophet==1.1.5 tensorflow==2.16.1
pip install flask==3.0.3 fastapi==0.111.0 uvicorn==0.29.0
pip install redis==5.0.4 celery==5.3.6
Expected Output:
Successfully installed tensorflow-2.16.1 fastapi-0.111.0 redis-5.0.4
Virtual environment ready for development
Phase 2: Model Implementation
Core Model Architecture
Our system implements four specialized forecasting models:
ARIMA Model - Statistical approach perfect for stable time series with clear trends. Automatically determines optimal parameters and handles non-stationary data through differencing.
Prophet Model - Facebook's robust forecaster that excels at handling seasonality, holidays, and missing data. Particularly effective for business metrics with weekly and yearly patterns.
LSTM Neural Network - Deep learning approach that captures complex non-linear relationships in your log data. Uses sequence-to-sequence prediction with attention mechanisms.
Exponential Smoothing - Simple but effective method that gives more weight to recent observations. Fast training and prediction make it ideal for real-time scenarios.
Model Training Process
Each model trains on historical log data using a standardized interface:
python
# Example training workflow
def train_model(model, data):
    X = prepare_features(data)
    y = extract_target_values(data)

    model.fit(X, y)
    accuracy = model.validate(test_data)

    if accuracy > threshold:
        model.save("models/trained/")
        return True
    return False
The system automatically validates each model against held-out test data and only deploys models that meet accuracy requirements.
Phase 3: Ensemble Engine Development
Intelligent Model Combination
Rather than relying on a single forecasting approach, our ensemble engine combines predictions from all models using learned weights:
ARIMA: 25% weight (stable baseline predictions)
Prophet: 35% weight (seasonal pattern recognition)
LSTM: 30% weight (complex pattern learning)
Exponential Smoothing: 10% weight (recent trend emphasis)
Confidence Calculation
The system calculates prediction confidence by analyzing:
Model Agreement: How closely individual predictions align
Historical Accuracy: Recent performance of each model
Data Quality: Completeness and consistency of input data
Pattern Stability: How well-established the detected patterns are
High confidence predictions (>85%) trigger automatic scaling actions. Medium confidence (65-85%) generates team notifications. Low confidence predictions still contribute to learning but don't generate alerts.
Phase 4: Real-Time Processing Infrastructure
Background Processing
The system uses Celery for background task management:
Periodic Forecasting - Generates new predictions every 5 minutes using the latest log data and updated model weights.
Model Retraining - Automatically retrains models every 6 hours using fresh data, ensuring predictions remain accurate as system behavior evolves.
Health Monitoring - Continuously monitors system health, model performance, and prediction accuracy.
Data Pipeline
Log data flows through a sophisticated processing pipeline:
Data Ingestion - Collects log entries from various sources (web servers, databases, applications)
Feature Extraction - Converts raw logs into time series metrics (response times, error rates, throughput)
Data Validation - Ensures data quality and handles missing values
Model Input Preparation - Formats data for each forecasting algorithm
Prediction Generation - Runs ensemble forecasting and confidence calculation
Result Storage - Caches predictions in Redis for fast API access
Phase 5: API Development
Core Endpoints
The FastAPI server provides several key endpoints:
GET /predictions - Returns latest ensemble forecasts with confidence levels and individual model predictions.
GET /health - System health check including model status, Redis connectivity, and performance metrics.
GET /metrics - Detailed system metrics including prediction accuracy, processing times, and resource usage.
GET /forecast/{steps} - Generate custom forecasts for specified time horizons (1-288 steps = 5 minutes to 24 hours).
Response Format
All predictions include comprehensive metadata:
json
{
  "timestamp": "2025-01-16T10:30:00Z",
  "forecast_horizon_minutes": 60,
  "ensemble_prediction": [52.3, 54.1, 56.8, ...],
  "ensemble_confidence": [0.87, 0.82, 0.79, ...],
  "individual_forecasts": {
    "arima": [51.2, 53.1, 55.9, ...],
    "prophet": [53.1, 54.8, 57.2, ...],
    "lstm": [52.8, 54.5, 57.1, ...],
    "exponential_smoothing": [51.9, 53.7, 56.3, ...]
  },
  "alert_level": "high"
}
Phase 6: Dashboard Development
React Frontend Architecture
The dashboard provides comprehensive visibility into system predictions and performance:
Real-time Charts - Live visualization of predictions vs actual metrics using Recharts library. Updates automatically every 30 seconds via API polling.
Confidence Indicators - Color-coded confidence levels with detailed breakdowns. Green for high confidence (>85%), yellow for medium (65-85%), red for low (<65%).
Model Comparison - Side-by-side comparison of individual model predictions, helping users understand which algorithms perform best for different scenarios.
System Health - Live monitoring of system status, model availability, and performance metrics.
Key Dashboard Features
Interactive Time Selection - Users can adjust forecast horizons from 15 minutes to 24 hours and see how prediction accuracy changes.
Alert Management - Visual alerts when predictions exceed configured thresholds, with drill-down capabilities for detailed analysis.
Historical Analysis - Compare past predictions with actual outcomes to understand model performance over time.
Configuration Panel - Adjust model weights, confidence thresholds, and alert settings without system restarts.
Testing and Validation
Comprehensive Test Suite
Unit Tests - Validate individual model implementations, ensuring each algorithm produces mathematically correct results.
Integration Tests - Test complete data pipeline from log ingestion through prediction generation to API responses.
Performance Tests - Measure system throughput, memory usage, and response times under various load conditions.
Accuracy Tests - Compare predictions against actual metrics to validate forecasting quality.
Expected Performance Metrics
Prediction Latency: 200-500ms per forecast generation
Memory Usage: 200-400MB total system footprint
CPU Usage: <30% during normal operation
Forecast Accuracy: 60-80% for 1-hour predictions
API Response Time: <2 seconds for all endpoints
Validation Process
Run the complete test suite to verify your implementation:
bash
# Unit tests for individual components
python -m pytest tests/test_models.py -v

# Integration tests for complete pipeline
python -m pytest tests/test_forecasting_engine.py -v

# API endpoint testing
python -m pytest tests/test_api.py -v

# Performance benchmarking
python tests/performance_test.py
Docker Deployment
Production Configuration
The system includes complete Docker configuration for production deployment:
Multi-Service Architecture - Separate containers for Redis, API server, background workers, and frontend dashboard.
Health Checks - Built-in health monitoring for all services with automatic restart on failure.
Volume Management - Persistent storage for trained models and historical data.
Horizontal Scaling - Support for multiple API server replicas behind a load balancer.
Deployment Commands
bash
# Build and start all services
docker-compose up --build -d

# Monitor service status
docker-compose ps

# View logs for debugging
docker-compose logs predictive-analytics

# Scale API servers for high availability
docker-compose up --scale predictive-analytics=3
Production Monitoring
Key Metrics to Track
Prediction Quality - Monitor prediction accuracy over time, alerting when accuracy drops below acceptable thresholds.
System Performance - Track API response times, memory usage, and CPU utilization to ensure optimal performance.
Model Health - Monitor individual model performance and automatically retrain underperforming models.
Alert Effectiveness - Measure false positive and false negative rates for prediction-based alerts.
Operational Best Practices
Regular Model Updates - Retrain models at least daily to maintain accuracy as system behavior evolves.
Confidence Threshold Tuning - Adjust confidence thresholds based on operational feedback and alert fatigue.
Capacity Planning - Use prediction trends to inform infrastructure scaling decisions.
Incident Response - Integrate predictions with existing alerting systems for proactive issue resolution.
Assignment Challenge
Build a forecasting system that predicts web server response times 1 hour in advance with >75% accuracy. Use your clustering results from Day 79 as input patterns. Generate predictions every 10 minutes and validate against actual metrics.
Success Criteria:
Deploy 3 different forecasting models (ARIMA, Prophet, Linear Regression minimum)
Create ensemble predictions combining all models
Build validation system comparing predictions to actuals
Generate real-time dashboard showing current metrics and forecasts
Implement alert system for prediction confidence levels
Solution Approach
Start with simple linear regression on response time trends discovered in your clustering analysis. Add ARIMA for handling any seasonal patterns found in your clusters. Implement Prophet for robust trend analysis with automatic seasonality detection.
Combine predictions using weighted averages based on recent model performance. Use sliding 7-day windows for training data, generating 1-hour forecasting horizons. Validate predictions every hour, adjusting model weights based on accuracy.
Display results on dashboard with confidence intervals and alert thresholds. Color-code predictions based on confidence levels and provide drill-down analysis for understanding prediction factors.
The Transformation You've Achieved
You've built a system that sees into the future—not through magic, but through intelligent pattern analysis and mathematical modeling. Your logs no longer just record what happened; they predict what's coming next.
This capability transforms operations from reactive to proactive, turning your distributed log processing system into a strategic operational tool. Tomorrow, we'll complete the intelligence loop by adding recommendation capabilities that suggest specific actions based on these predictions.
Key Capabilities Unlocked:
Proactive Problem Prevention - Predict issues 30-60 minutes before they occur
Intelligent Resource Scaling - Scale infrastructure based on predicted demand
Operational Intelligence - Transform raw logs into actionable business insights
System Reliability - Maintain performance through predictive maintenance
The future is knowable when you have the right patterns and algorithms. Today, you've built both, creating a foundation for intelligent, self-managing distributed systems.
Next: Day 81 - Recommendation System for Intelligent Troubleshooting Previous: Day 79 - Clustering for Pattern Discovery
The future is knowable when you have the right patterns and algorithms. Today, you've built both.
This is my favorite post. I am planning to use the models used in the ensemble for a personal project. are these the recommended ones for forecasting ?