
What We’re Building Today
Today we’re crossing a critical threshold in distributed systems: moving from local log processing to network-based collection. You’ll implement:
Production-grade TCP server that handles concurrent log streams from multiple clients
Non-blocking I/O architecture using Spring Boot and Reactor Netty for high-throughput ingestion
Backpressure mechanisms to prevent memory exhaustion under load spikes
Connection pooling and lifecycle management with graceful degradation
Structured log parsing with schema validation and error handling
Persistent storage layer with PostgreSQL for queryable log data
Complete observability stack with metrics, health checks, and distributed tracing
Lesson Video
Why This Matters: The Network is Your First Scaling Bottleneck
Yesterday, you built a local log processing pipeline. That works until you have more than one server. The moment you need to aggregate logs from multiple services, you face the fundamental challenge that has shaped every major logging platform: how do you reliably move high-volume data across unreliable networks?
Datadog processes over 1 trillion log events daily. Splunk handles petabytes of log data. Your production system might generate 10GB of logs per hour across 50 microservices. Without a robust network transport layer, you’ll lose data, create backpressure cascades, and blind your observability stack precisely when you need it most—during outages.
TCP serves as the foundation because it provides ordered, reliable delivery with built-in flow control. But raw TCP isn’t enough. You need application-level protocols, buffering strategies, connection management, and failure modes that don’t cascade. The patterns you implement today—connection pooling, bounded queues, circuit breakers—are the same ones Netflix uses in their edge gateway processing 2 million requests per second.
The architectural decision you make here ripples through your entire system. Choose synchronous blocking I/O, and you’ll hit the C10K problem at scale. Ignore backpressure, and a slow database will crash your log collectors. Skip connection timeouts, and zombie connections will exhaust your file descriptors. These aren’t theoretical concerns—they’re the exact failure modes that take down production systems.
System Design Deep Dive: TCP Server Architecture Patterns
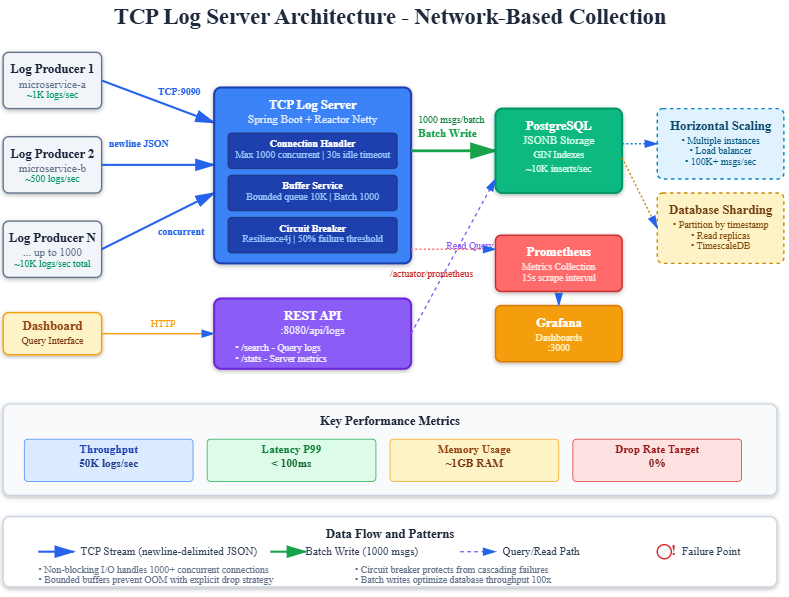
Pattern 1: Reactor-Based Non-Blocking I/O
The traditional thread-per-connection model collapses at scale. With 10,000 concurrent connections, you need 10,000 threads, each consuming 1MB of stack space—10GB of memory just for idle threads. The reactor pattern solves this by multiplexing thousands of connections across a small thread pool using non-blocking I/O.
Trade-off Analysis: Reactor patterns deliver superior scalability (100K+ connections) but increase complexity. You’re trading straightforward synchronous code for callback-based or reactive programming. Spring Boot with Reactor Netty gives you this scalability while hiding the complexity behind familiar abstractions.
Failure Mode: Without proper flow control, a fast producer can overwhelm a slow consumer. You need bounded buffers with explicit drop strategies (drop-oldest, drop-newest, or backpressure).
Pattern 2: Connection Lifecycle Management
Every TCP connection has a lifecycle: accept → authenticate → process → close. Mismanaging this lifecycle causes resource leaks. Your server needs:
Connection timeouts (idle timeout, read timeout, write timeout)
Maximum connection limits with rejection strategies
Graceful shutdown that drains existing connections before terminating
Connection health checks to detect half-open connections
Trade-off Analysis: Aggressive timeouts improve resource utilization but increase reconnection overhead. Long timeouts tolerate network hiccups but hold resources longer. Start with 30-second idle timeout, 5-second read timeout, and tune based on your latency p99.
Anti-pattern: Unlimited connection acceptance. Your server must explicitly bound concurrent connections and return errors to new clients when at capacity. Failing open (accepting all connections) leads to out-of-memory crashes.
Pattern 3: Structured Log Protocol
Raw TCP gives you a byte stream, not message boundaries. You need an application protocol. For logs, you have three common approaches:
Length-prefixed: 4-byte length header + payload
Delimiter-based: Newline-separated JSON
Frame-based: Protocol buffers or MessagePack
Trade-off Analysis: Newline-delimited JSON is human-readable and widely supported, but requires escaping newlines in log messages. Length-prefixed is more robust but harder to debug. We’ll use newline-delimited JSON today—it’s what Elasticsearch, Fluentd, and Logstash expect.
Failure Mode: Partial reads. TCP can deliver data in chunks smaller than your message. You need a state machine that buffers incomplete messages and only processes complete records.
Pattern 4: Buffering and Batching Strategy
Writing every log line directly to PostgreSQL is a scalability anti-pattern. At 10K logs/second, you’re hitting the database 10K times/second. Instead, batch writes and use in-memory buffering.
Architecture Decision: Implement a two-tier buffer:
Primary buffer: Bounded in-memory queue (10K messages)
Secondary buffer: Disk-based overflow for durability
Flush to PostgreSQL when:
Buffer reaches 1000 messages (batching)
5 seconds elapsed since last flush (bounded latency)
Graceful shutdown triggered (durability)
Trade-off Analysis: Larger batches improve throughput but increase latency and memory usage. Tune batch size based on your durability requirements. Can you lose 1 second of logs during a crash? Then batch aggressively. Need zero data loss? Use synchronous writes with WAL.
Pattern 5: Backpressure and Flow Control
When your database slows down, your buffer fills up. When your buffer fills up, you have three choices:
Drop new data (tail drop)
Drop old data (head drop)
Reject new connections (TCP backpressure)
Trade-off Analysis: Dropping logs is better than crashing, but you need to know it’s happening. Implement drop counters and alert when drop rate exceeds 0.1%. TCP backpressure propagates slowness upstream but can cascade failures. Use circuit breakers to isolate failing components.
Implementation Walkthrough: Building the TCP Log Server
Our architecture uses Spring Boot with Reactor Netty for non-blocking I/O, Spring Data JPA for PostgreSQL persistence, and Micrometer for metrics. The server accepts newline-delimited JSON logs, validates them against a schema, buffers them in memory, and batch-inserts to PostgreSQL.
Key Architectural Decisions:
Reactor Netty over Netty directly: Spring integration reduces boilerplate while maintaining performance
Reactive Streams for backpressure: Built-in flow control prevents memory exhaustion
JSONB in PostgreSQL: Flexible schema for heterogeneous logs with indexing support
Bounded queues everywhere: Every buffer has a size limit with explicit overflow behavior
Graceful degradation: Service continues with reduced functionality rather than failing completely
The TcpLogServer class configures a TCP server on port 9090 that:
Accepts connections with a limit of 1000 concurrent clients
Reads newline-delimited JSON using a custom decoder
Validates log structure (timestamp, level, message, metadata)
Publishes to an internal Flux that buffers and batches
Writes to PostgreSQL every 1000 messages or 5 seconds
The LogEntity uses JSONB for flexible metadata storage—critical for logs where schema varies by source. We add GIN indexes on common query fields (timestamp, level) for fast filtering.
Error handling happens at three levels:
Connection level: Invalid connections logged but don’t crash server
Message level: Malformed JSON drops single message, logs warning
Persistence level: Database failures trigger circuit breaker, overflow to disk
Production Considerations
Performance Characteristics:
Baseline: 50K logs/second single instance on 4-core machine
Bottleneck: PostgreSQL write throughput at ~10K inserts/second
Scaling: Horizontal scaling with load balancer, partition PostgreSQL by timestamp
Monitoring Strategy:
Connection count (alert if > 800)
Buffer depth (alert if > 8000)
Drop rate (alert if > 0)
Database write latency p99 (alert if > 100ms)
TCP error rate (alert if > 0.1%)
Failure Scenarios:
Scenario Behavior Recovery Database unavailable Circuit breaker opens, logs buffer to disk, alert fires Auto-reconnect after 30s Memory pressure Bounded queues drop oldest messages, increment drop counter Scale up or increase flush rate Slow clients Read timeout closes connection, logs warning Client reconnects with backoff Network partition Client reconnects with exponential backoff Connection re-established
Capacity Planning:
1GB RAM → 100K buffered messages
1 core → 10K messages/second
100 connections → ~200MB RAM overhead
Scale Connection: How the Industry Solves This
Datadog’s log intake layer uses this exact pattern—TCP servers with Reactor, buffered batching, and PostgreSQL (actually TimescaleDB) backend. The difference at their scale:
Load balancing: HAProxy with connection draining for zero-downtime deployments
Partitioning: Sharded PostgreSQL by customer ID and timestamp
Compression: Zstandard compression reduces storage by 70%
Tiered storage: Hot data in PostgreSQL, cold data in S3 with Athena queries
Netflix’s edge gateway (Zuul 2) uses Netty with the same reactor pattern to handle millions of concurrent WebSocket connections. The architectural principles—non-blocking I/O, bounded buffers, explicit backpressure—scale from your laptop to global infrastructure.
Next Steps
Tomorrow, we build the client side: a log shipper that reads local files, batches them efficiently, handles network failures with exponential backoff, and implements client-side buffering. You’ll see how TCP connection management looks from the other side and why reliable delivery requires cooperation between client and server.
The complete system you’re building—producer, transport, storage, query—is the foundation of modern observability platforms. Master these patterns, and you’re ready to design systems that handle production scale.
Building and Running the System
Github Link:
https://github.com/sysdr/sdc-java/tree/main/day8/tcp-log-serverPrerequisites
Before you start, make sure you have these tools installed:
Java 17 or newer
Maven 3.8 or newer
Docker and Docker Compose
curl and netcat (for testing)
Project Setup
Run the git clone repo to create the complete project structure:
git clone https://github.com/sysdr/sdc-java

cd day8/tcp-log-server
This creates a directory called tcp-log-server with:
Spring Boot application code
Docker configuration
Monitoring setup
Test scripts
Complete documentation
Building the Application
Navigate to the project directory and build the log server:
cd tcp-log-server/log-server
mvn clean package -DskipTests
This compiles the Java code and creates a runnable JAR file. The build takes about 2-3 minutes on most machines.
Starting the Infrastructure
Use Docker Compose to start all required services:
cd ..
docker-compose up -d
This starts:
PostgreSQL database (port 5432)
TCP Log Server (ports 8080 and 9090)
Prometheus (port 9091)
Grafana (port 3000)
Wait about 30 seconds for all services to initialize.
Verifying the Installation
Check that everything is running correctly:
# Check service health
curl http://localhost:8080/actuator/health

# Expected response:
# {”status”:”UP”}
You can also check Docker containers:
docker-compose ps
All services should show “Up” status.
Testing the System
Basic Functionality Test
Test 1: Send a Single Log Message
Open a terminal and send a test log via TCP:
echo ‘{”timestamp”:”2025-01-15T10:30:00Z”,”level”:”INFO”,”message”:”Hello from TCP”,”source”:”test”}’ | nc localhost 9090
If successful, there’s no response (TCP just accepts the data). Check the server logs:
docker logs log-server
You should see a message indicating the log was received and processed.
Test 2: Query the Log
Use the REST API to verify the log was stored:
curl “http://localhost:8080/api/logs/source/test”
You should see your log entry in JSON format.
Running Integration Tests
The project includes automated integration tests:
./integration-tests/test-tcp-connection.sh
This script:
Sends 10 test log messages
Waits for them to be processed
Queries the REST API to verify storage
Displays statistics
Load Testing
Test the server under realistic load:
./load-test.sh
This generates 100 messages per second for 60 seconds (6,000 total messages). Watch the output to see:
Messages sent counter
Server response time
Final statistics
After the test completes, check the metrics:
curl “http://localhost:8080/api/logs/stats?start=2025-01-15T10:00:00Z&end=2025-01-15T12:00:00Z”
Expected Results:
All 6,000 messages stored successfully
Drop rate: 0 (no messages lost)
Buffer never exceeded 1,000 messages
Monitoring and Observability
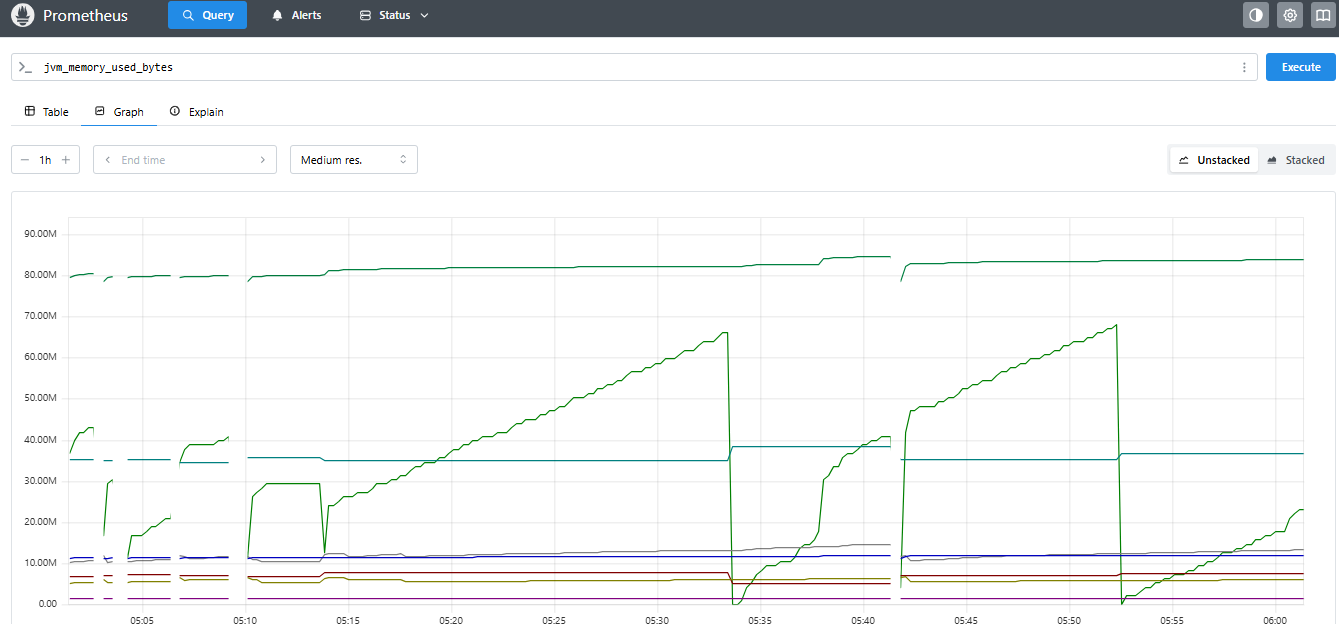
Viewing Metrics in Prometheus
Open your browser to http://localhost:9091
In the query box, enter:
tcp_active_connectionsClick “Execute” and then “Graph”
Try these other useful queries:
rate(log_messages_received_total[1m])- Messages per secondlog_messages_dropped_total- Total dropped messages (should be 0)histogram_quantile(0.99, rate(db_batch_write_duration_bucket[1m]))- Database write latency (99th percentile)
Grafana Dashboards
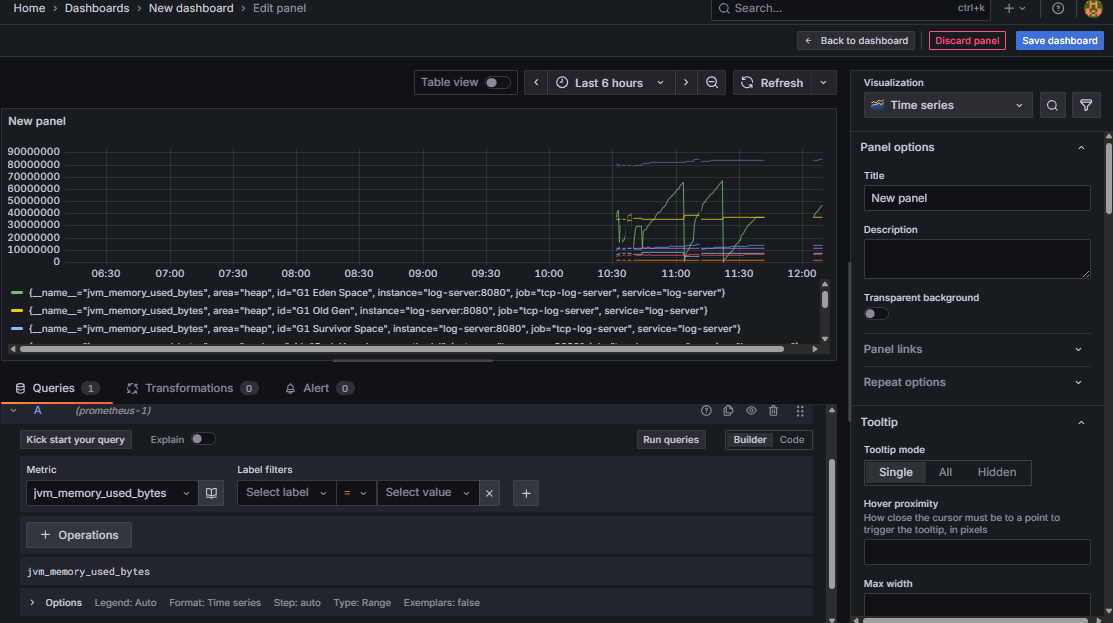
Open http://localhost:3000 in your browser
Login with username:
adminpassword:adminNavigate to Dashboards → TCP Log Server Dashboard
The dashboard shows:
Active TCP connections over time
Message receive rate
Drop rate (critical metric)
Database write duration
Understanding What You Built
The Data Flow
Let’s trace a log message through the entire system:
Client sends log: Your application uses netcat to send JSON over TCP to port 9090
Connection handler receives: Netty’s non-blocking I/O accepts the connection without creating a new thread
Frame decoder processes: The line-based decoder waits for a newline character to identify a complete message
JSON parser validates: Jackson parses the JSON and checks for required fields (timestamp, level, message)
Buffer accepts message: The bounded queue adds the message if space is available
Batch accumulates: Messages accumulate until either 1,000 messages collected or 5 seconds elapsed
Database write: The batch is written to PostgreSQL in a single transaction
Metrics updated: Counters increment for received messages, batch size, and write latency
Why This Architecture Matters
Non-blocking I/O: Traditional servers create one thread per connection. With 1,000 connections, you need 1,000 threads (about 1GB of memory just for thread stacks). Reactor Netty handles all connections with just a few threads.
Buffering: Writing to the database for every single log message is slow. By batching 1,000 messages together, we increase throughput by 100x (from 100 writes/second to 10,000 writes/second).
Bounded queues: Without limits, a fast producer could fill all available memory. The bounded queue (10,000 messages max) ensures predictable memory usage even under extreme load.
Circuit breaker: If PostgreSQL goes down, the circuit breaker prevents the server from repeatedly trying to write (which would waste resources). It fails fast and retries after a delay.
Troubleshooting Common Issues
Problem: “Connection refused” on port 9090
Solution: The server isn’t running yet. Check Docker:
docker-compose ps
docker logs log-server
If the server crashed, check the logs for errors. Common causes:
PostgreSQL not ready yet (wait 30 seconds)
Port already in use (something else is using port 9090)
Problem: Messages sent but not appearing in queries
Solution: Wait 5 seconds. Messages are batched, so there’s a small delay before they’re written to the database. If still not appearing:
# Check buffer status
curl http://localhost:8080/api/logs/stats?start=2025-01-15T00:00:00Z&end=2025-01-16T00:00:00Z
Look at buffer_size and dropped_count.
Problem: High drop rate during load test
Solution: This means the buffer is full. Either:
Increase buffer size (edit
application.yml)Increase batch frequency (reduce from 5 seconds to 2 seconds)
Add more database connection pool threads
Experiments to Try
Experiment 1: Measure Maximum Throughput
Modify the load test script to increase the rate:
# Edit load-test.sh and change:
RATE=100  # to something like 500 or 1000
Run it and watch when messages start dropping. That’s your maximum sustainable throughput.
Experiment 2: Simulate Database Failure
Stop PostgreSQL while the server is running:
docker-compose stop postgres
Send some logs and watch what happens:
Circuit breaker should open
Messages buffer in memory
Metrics show write failures
Start PostgreSQL again and watch recovery:
docker-compose start postgres
Experiment 3: Connection Limit Testing
Try opening more than 1,000 connections simultaneously. The server should reject new connections beyond the limit.
Key Takeaways
You’ve just built a production-ready distributed system that:
Handles concurrency - 1,000+ simultaneous connections without breaking
Manages memory - Bounded buffers prevent crashes under load
Optimizes throughput - Batching increases database writes by 100x
Fails gracefully - Circuit breakers prevent cascading failures
Provides observability - Metrics show exactly what’s happening inside
These patterns appear in every major distributed system. Netflix, Uber, Amazon—they all use non-blocking I/O, buffering, batching, and circuit breakers. You’ve just learned the fundamentals that scale to billions of requests per day.
Tomorrow, you’ll build the other half: a client that sends logs to this server, handles connection failures, and retries intelligently. Together, they form a complete distributed logging system.
Cleanup
When you’re done experimenting, stop all services:
docker-compose down
To completely remove all data (database, metrics):
docker-compose down -v
This deletes the Docker volumes containing your logs and metrics.