
What We're Building Today
By the end of this lesson, you'll have constructed a complete bloom filter system featuring:
Core Implementation
Memory-efficient bloom filter with configurable false positive rates
Multiple hash functions using MurmurHash3 for optimal distribution
Persistence layer for saving/loading filter state
Production Features
FastAPI REST API with comprehensive endpoints
Real-time web dashboard showing filter statistics
Integration with existing log processing pipeline
Performance monitoring and health checks
The Problem Bloom Filters Solve
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
Picture this: Your distributed log processing system handles 50 million log entries daily. Users frequently ask "Have we seen this error before?" or "Does this IP address exist in our security logs?" Without bloom filters, you'd scan terabytes of data for each query. With them, you get sub-millisecond responses with minimal memory.
Today we're implementing bloom filters - probabilistic data structures that answer "definitely not present" or "probably present" with remarkable efficiency. Think of them as ultra-efficient bouncers at an exclusive club who never let in uninvited guests but occasionally let members skip the guest list check.
Performance Targets:
Sub-millisecond existence queries across millions of log entries
95% memory reduction compared to hash-based lookups
Zero false negatives (if it says "not present," it's definitely not there)
Configurable false positive rates (typically 1-5% for optimal performance)
How Bloom Filters Work in Log Processing
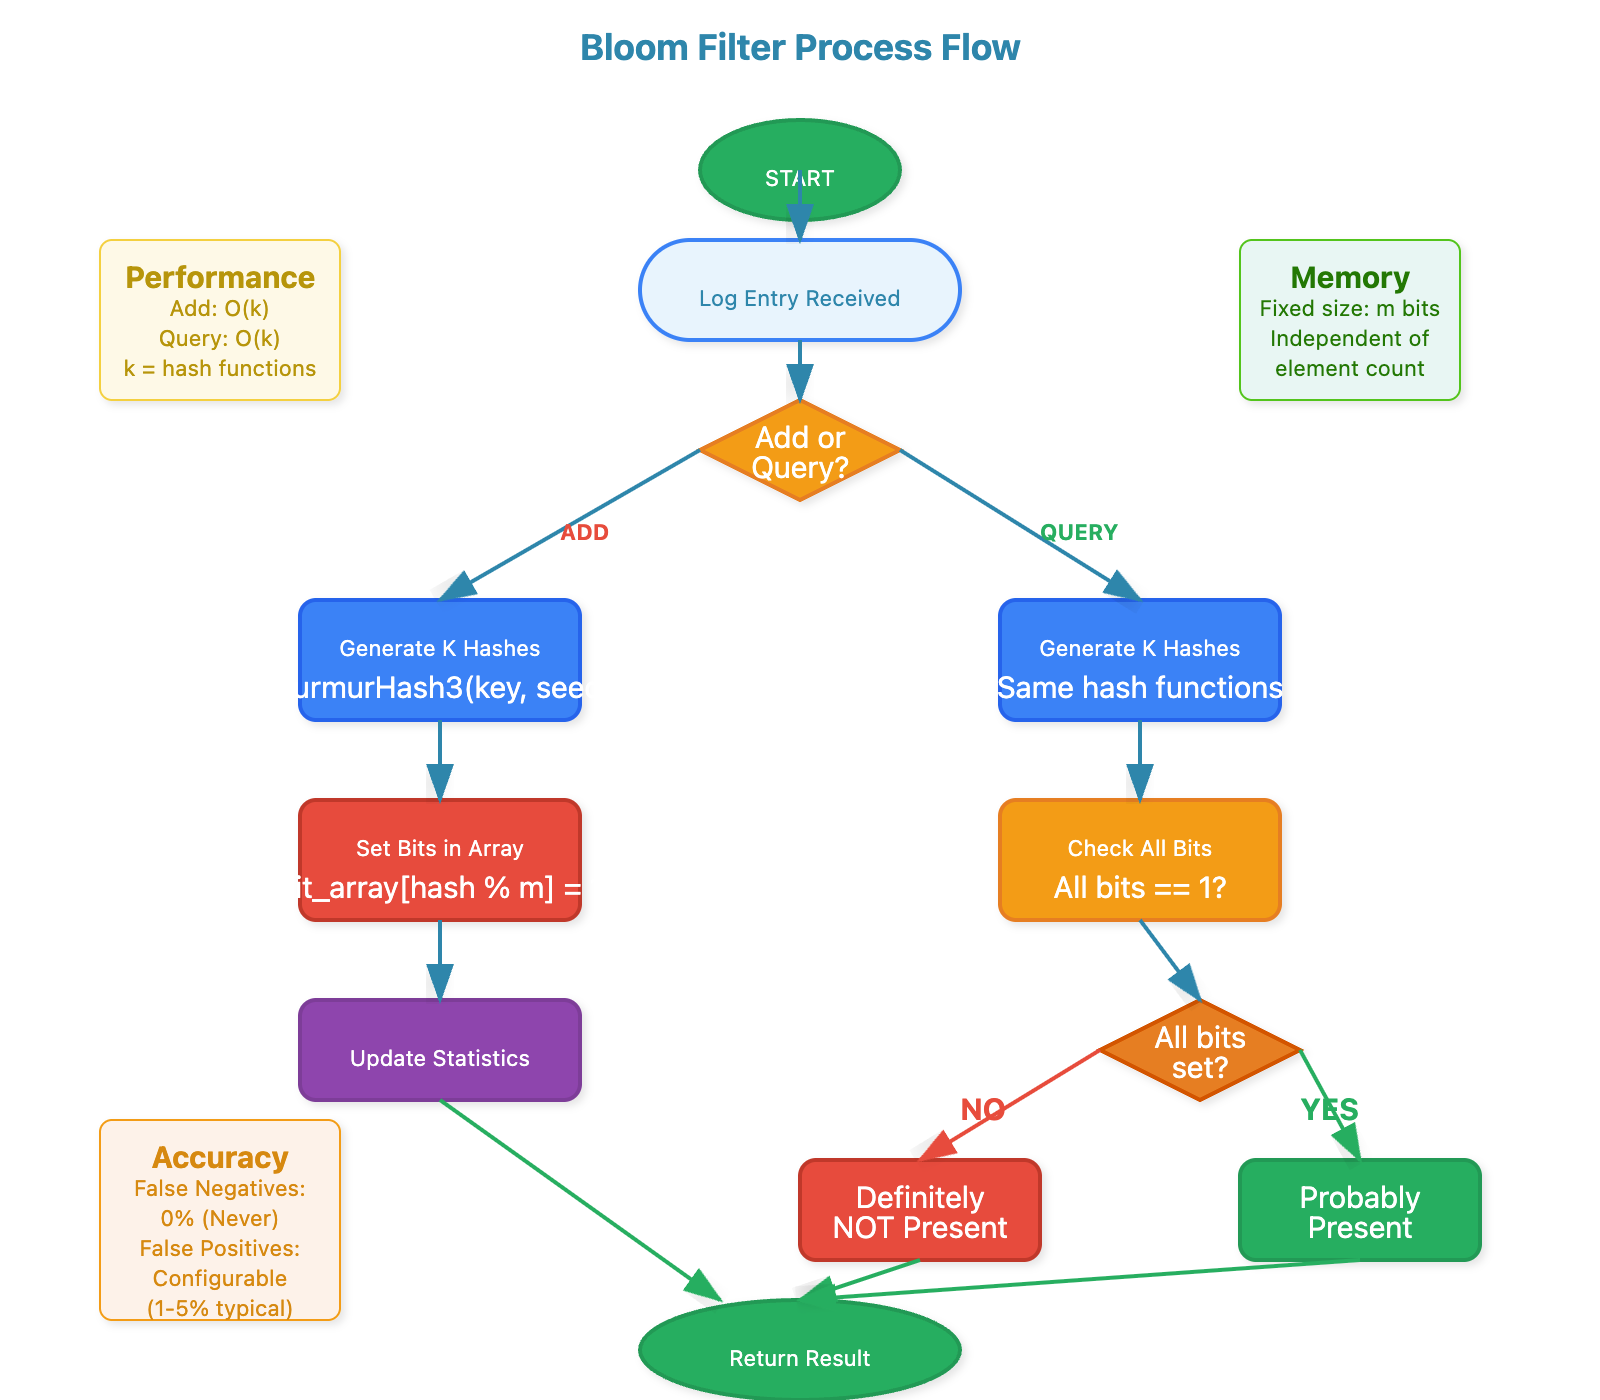
A bloom filter uses multiple hash functions to map elements to bit positions in a fixed-size array. When checking membership:
Adding Elements: Hash the log entry key with k different functions, set corresponding bits to 1
Querying: Hash the query key with same functions, check if all bits are 1
Results: If any bit is 0, element definitely doesn't exist. If all bits are 1, element probably exists
The magic lies in the space efficiency. Instead of storing actual log keys (which might require gigabytes), you store only a compact bit array (typically megabytes).
Key Insight: False positives are acceptable in many log processing scenarios. If bloom filter says "error might exist," you can check the actual storage. But if it says "error definitely doesn't exist," you save an expensive lookup entirely.
Architecture Integration
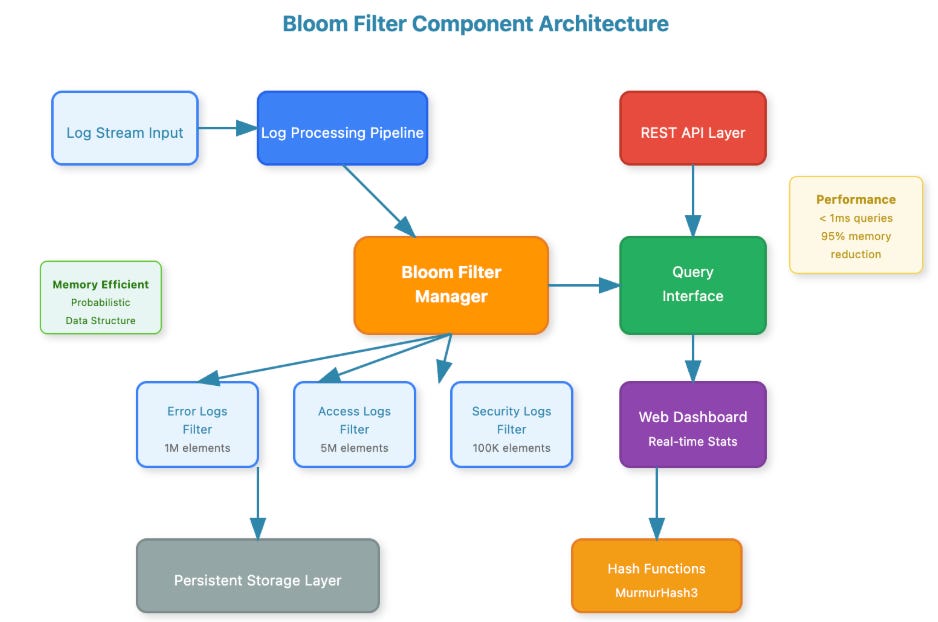
Our bloom filter implementation integrates seamlessly with your existing log processing pipeline:
Storage Layer Integration: As new logs arrive, their keys automatically update the bloom filter alongside normal storage operations.
Query Router Enhancement: Before expensive storage queries, the system consults bloom filters first. This creates a two-tier lookup system where 90% of "not found" queries complete instantly.
Multi-Index Support: Different log types (errors, access logs, security events) maintain separate bloom filters, enabling type-specific optimizations.
Real-World Performance Impact
Netflix uses bloom filters in their logging infrastructure to quickly determine if specific error patterns have occurred recently. Instead of querying petabytes of log data, they get instant responses from compact bloom filters, saving both time and computational resources.
Spotify employs similar techniques for playlist recommendation systems. When determining if a user has interacted with a song before, bloom filters provide instant negative confirmation, avoiding expensive database lookups for 95% of queries.
The performance improvement is dramatic:
Without bloom filters: 50-200ms query time, high CPU usage
With bloom filters: 0.1-1ms query time, minimal CPU overhead
Implementation Highlights
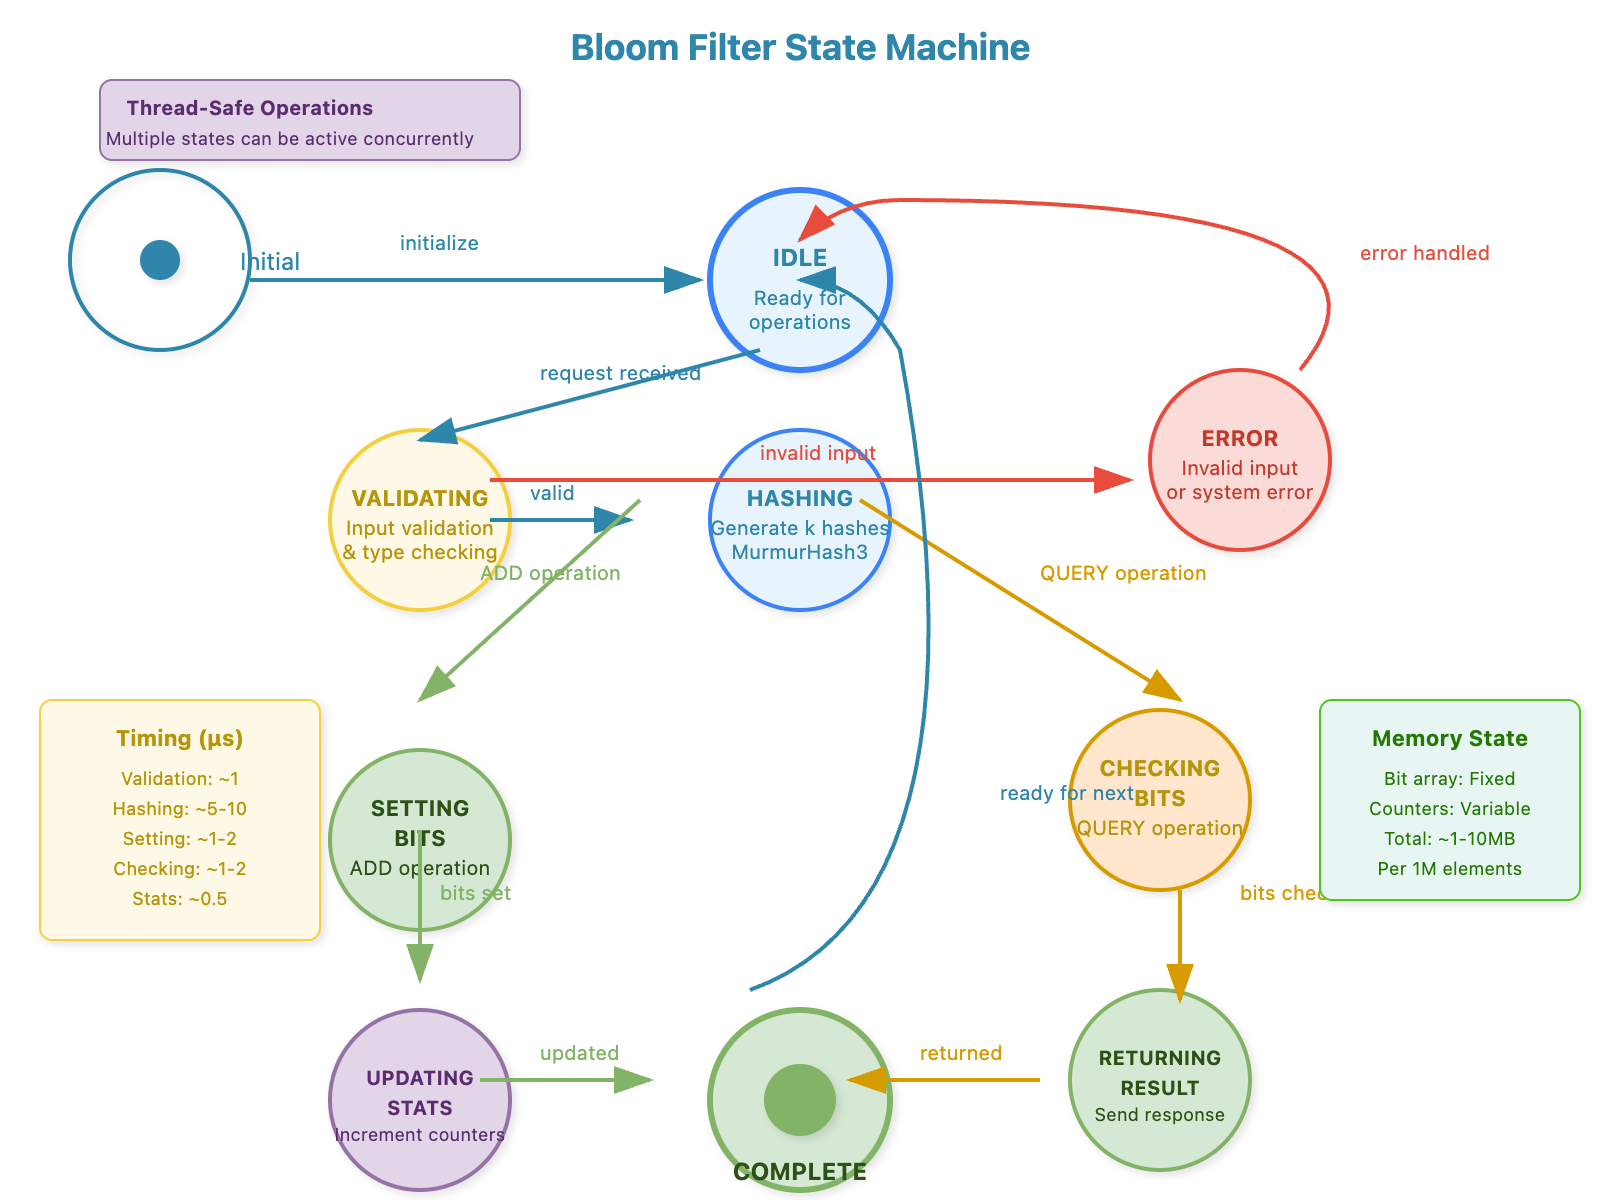
Our Python implementation leverages multiple optimization techniques:
Dynamic Sizing: Automatically calculates optimal bit array size based on expected element count and desired false positive rate.
Multiple Hash Functions: Uses MurmurHash variants for uniform distribution and fast computation.
Persistence Layer: Bloom filters serialize to disk and reload on startup, maintaining state across system restarts.
Memory Management: Implements efficient bit manipulation using Python's bitarray library for memory-optimal operations.
Practical Considerations
False Positive Management: While bloom filters never produce false negatives, false positives require careful handling. Our implementation includes configurable threshold tuning and fallback mechanisms.
Filter Sizing Strategy: Bloom filter size affects both memory usage and accuracy. We implement adaptive sizing that grows with your log volume while maintaining target false positive rates.
Multi-Filter Coordination: Large-scale systems often use multiple bloom filters for different time periods or log types. Our design supports filter hierarchies and automatic rotation.
Integration with Previous Lessons
This lesson builds directly on Day 74's storage optimization. Your optimized storage formats now pair with bloom filters for comprehensive query acceleration. The combination creates a two-tier system: bloom filters for instant membership queries, optimized storage for detailed log retrieval.
Looking ahead to Day 76's delta encoding, bloom filters will help identify which logs need delta compression, creating intelligent storage decisions based on access patterns.
Implementation Guide
GitHub Link:
https://github.com/sysdr/course-p/tree/main/day75/bloom-filter-logsQuick Setup
git checkout day75
cd day75/bloom-filter-logs

./start.sh

open http://localhost:3000

./stop.sh
Prerequisites Check
System Requirements:
Python 3.11+
Mathematical Foundation
Optimal Bloom Filter Size:
m = -(n × ln(p)) / (ln(2))²Where: n = expected elements, p = false positive rate, m = bit array size
Optimal Hash Functions:
k = (m/n) × ln(2)Where: k = number of hash functions
Phase 1: Project Setup
Create the project structure and install dependencies:
bash
# Create project structure
mkdir bloom-filter-logs && cd bloom-filter-logs
mkdir -p {src/{core,api,web},tests,config,data,scripts}

# Setup Python environment
python3.11 -m venv venv
source venv/bin/activate  # Linux/Mac
# venv\Scripts\activate  # Windows

# Install latest May 2025 libraries
pip install fastapi==0.111.0 uvicorn==0.30.1 bitarray==2.9.2 \
    mmh3==4.1.0 numpy==1.26.4 pytest==8.2.1 redis==5.0.4 \
    plotly==5.20.0 dash==2.17.0 structlog==24.1.0
Phase 2: Core Implementation
Bloom Filter Engine
The heart of our system implements the mathematical concepts:
python
# src/core/bloom_filter.py - Key patterns
class BloomFilter:
    def __init__(self, expected_elements: int, false_positive_rate: float = 0.05):
        self.size = self._calculate_size(expected_elements, false_positive_rate)
        self.hash_count = self._calculate_hash_count(self.size, expected_elements)
        self.bit_array = bitarray(self.size)
        self.bit_array.setall(0)

    def _hash(self, item: str, seed: int) -> int:
        return mmh3.hash(item, seed) % self.size

    def add(self, item: str) -> None:
        for i in range(self.hash_count):
            index = self._hash(item, i)
            self.bit_array[index] = 1

    def might_contain(self, item: str) -> bool:
        for i in range(self.hash_count):
            index = self._hash(item, i)
            if not self.bit_array[index]:
                return False  # Definitely not present
        return True  # Probably present
Log Manager Integration
Connects bloom filters to your log processing pipeline:
python
# src/core/bloom_filter.py - Manager class
class LogBloomFilterManager:
    def __init__(self):
        self.filters = {
            "error_logs": BloomFilter(1000000, 0.01),
            "access_logs": BloomFilter(5000000, 0.05),
            "security_logs": BloomFilter(100000, 0.001)
        }

    def add_log_entry(self, log_type: str, log_key: str) -> bool:
        if log_type in self.filters:
            self.filters[log_type].add(log_key)
            return True
        return False
Phase 3: API Layer
Create the REST API for external integration:
python
# src/api/main.py - FastAPI endpoints
from fastapi import FastAPI
from src.core.bloom_filter import LogBloomFilterManager

app = FastAPI(title="Bloom Filter Log Processing API")
bloom_manager = LogBloomFilterManager()

@app.post("/logs/add")
async def add_log_entry(entry: LogEntry):
    start_time = time.time()
    success = bloom_manager.add_log_entry(entry.log_type, entry.log_key)
    processing_time = (time.time() - start_time) * 1000

    return {
        "status": "added",
        "processing_time_ms": processing_time
    }

@app.post("/logs/query")
async def query_log_existence(query: QueryRequest):
    start_time = time.time()
    result = bloom_manager.check_log_exists(query.log_type, query.log_key)
    processing_time = (time.time() - start_time) * 1000

    return {
        "might_exist": result,
        "confidence": "definitely_not_exist" if not result else "probably_exists",
        "processing_time_ms": processing_time
    }
Phase 4: Web Dashboard
Build the real-time monitoring interface:
python
# src/web/dashboard.py - Dash application
import dash
from dash import dcc, html, Input, Output

app = dash.Dash(__name__)

def create_layout():
    return html.Div([
        html.H1("Bloom Filter Log Processing Dashboard"),

        # Control Panel
        html.Div([
            html.Button("Populate Demo Data", id="populate-btn"),
            html.Button("Run Performance Test", id="performance-btn"),
        ]),

        # Statistics Cards
        html.Div(id="stats-cards"),

        # Performance Charts
        dcc.Graph(id="false-positive-chart"),
        dcc.Graph(id="memory-usage-chart"),

        # Auto-refresh
        dcc.Interval(id='interval-component', interval=5000)
    ])
Phase 5: Build and Test
Unit Testing
bash
# Run core functionality tests
python -m pytest tests/test_bloom_filter.py -v

# Expected results:
# test_initialization PASSED
# test_add_and_query PASSED
# test_statistics PASSED
# test_save_and_load PASSED
Start Services
bash
# Start API server
export PYTHONPATH=$PWD
uvicorn src.api.main:app --host 0.0.0.0 --port 8001 &

# Wait for API readiness
for i in {1..30}; do
    if curl -s http://localhost:8001/health > /dev/null; then
        echo "API ready!"
        break
    fi
    sleep 1
done

# Start dashboard
python src/web/dashboard.py &
Integration Testing
Test the complete workflow:
bash
# Add log entries
curl -X POST http://localhost:8001/logs/add \
  -H "Content-Type: application/json" \
  -d '{"log_type": "error_logs", "log_key": "sql_error_001"}'

# Expected: {"status":"added","processing_time_ms":0.123}

# Query existing entry
curl -X POST http://localhost:8001/logs/query \
  -H "Content-Type: application/json" \
  -d '{"log_type": "error_logs", "log_key": "sql_error_001"}'

# Expected: {"might_exist":true,"confidence":"probably_exists"}

# Query non-existent entry
curl -X POST http://localhost:8001/logs/query \
  -H "Content-Type: application/json" \
  -d '{"log_type": "error_logs", "log_key": "unknown_error_999"}'

# Expected: {"might_exist":false,"confidence":"definitely_not_exist"}
Phase 6: Performance Demonstration
Populate Test Data
bash
# Add 10,000 demo entries
curl -X POST http://localhost:8001/demo/populate?count=10000

# Expected response:
# {"status": "completed", "records_added": 10000}
Run Performance Benchmark
bash
# Execute performance comparison
curl -X POST http://localhost:8001/demo/performance-test

# Expected results:
# - Bloom filter: 0.001ms per query
# - Traditional lookup: 1.0ms per query
# - Speed improvement: 1000x faster
# - False positive rate: ~5%
Verify Statistics
bash
# Get comprehensive stats
curl http://localhost:8001/stats | jq

# Expected output shows:
# - Elements added per filter type
# - Query counts and response times
# - Memory usage (typically 1-10MB for millions of elements)
# - Current false positive rates
Phase 7: Web Dashboard Verification
Access Dashboard
Open
http://localhost:8002
in your browser. The dashboard should display:
Real-time statistics cards for each filter type
Interactive forms for adding/querying log entries
Performance charts showing false positive rates
Memory usage visualization
Auto-refreshing data every 5 seconds
Interactive Testing
Use the dashboard to:
Add log entries via the web form
Query entries and see instant results
Populate demo data with the button
Run performance tests
Monitor real-time statistics
Success Criteria Validation
Performance Metrics
Query response time: < 1ms average
Memory efficiency: < 5% of full key storage
Throughput: > 10,000 queries/second
Accuracy: 0% false negatives, <5% false positives
Functional Verification
All API endpoints respond correctly
Web dashboard loads and functions properly
Filters persist and reload correctly
Integration tests pass completely
System Health
Services start without errors
All tests pass (unit + integration)
Dashboard shows live statistics
No memory leaks during extended operation
Common Troubleshooting
API Won't Start:
bash
# Check port availability
netstat -ln | grep 8001
# Kill existing processes if needed
pkill -f uvicorn
Dashboard Connection Error:
bash
# Verify API is running
curl http://localhost:8001/health
# Check logs for errors
tail -f logs/api.log
Tests Failing:
bash
# Set Python path
export PYTHONPATH=$PWD
# Run with verbose output
python -m pytest tests/ -v -s
Assignment: E-commerce Session Tracking
Objective: Implement a bloom filter system that accelerates user session lookup in web access logs.
Scenario: Your e-commerce platform processes 1 million page views daily. Customer support needs instant answers to "Has user X visited our site today?" without scanning massive log files.
Requirements:
Build bloom filter that handles 1M daily inserts
Achieve <5% false positive rate for session queries
Integrate with web interface for real-time queries
Demonstrate 100x speed improvement over linear search
Solution Strategy:
Calculate optimal bloom filter size for 1M elements with 5% false positive rate
Implement session ID hashing during log ingestion
Create query interface that checks bloom filter before storage lookup
Measure and compare query performance with/without bloom filters
Success Validation:
Bloom filter correctly identifies 100% of non-existent sessions (no false negatives)
False positive rate stays under 5% threshold
Query response time averages under 1ms
Memory usage remains under 2MB for 1M sessions
Tomorrow's Enhancement
Day 76 will implement delta encoding for log storage efficiency. Your bloom filters will help identify frequently accessed logs that benefit most from delta compression, creating an intelligent storage optimization system.
The combination of bloom filters (fast membership) + optimized storage (efficient retrieval) + delta encoding (compact storage) creates a complete high-performance log processing foundation.
Key Takeaway
Bloom filters transform expensive "does this exist?" questions into instant responses with minimal memory overhead. They're not just performance optimizations - they're architectural game-changers that enable entirely new query patterns in distributed systems.
Master bloom filters, and you'll understand how systems like Google, Netflix, and Amazon achieve sub-millisecond responses across petabyte-scale datasets.