
What We're Building Today
Transform your log processing system from good to exceptional with intelligent caching layers that reduce query response times from seconds to milliseconds. Today's lesson builds a production-ready multi-tier caching architecture with machine learning-driven optimization.
Key Components:
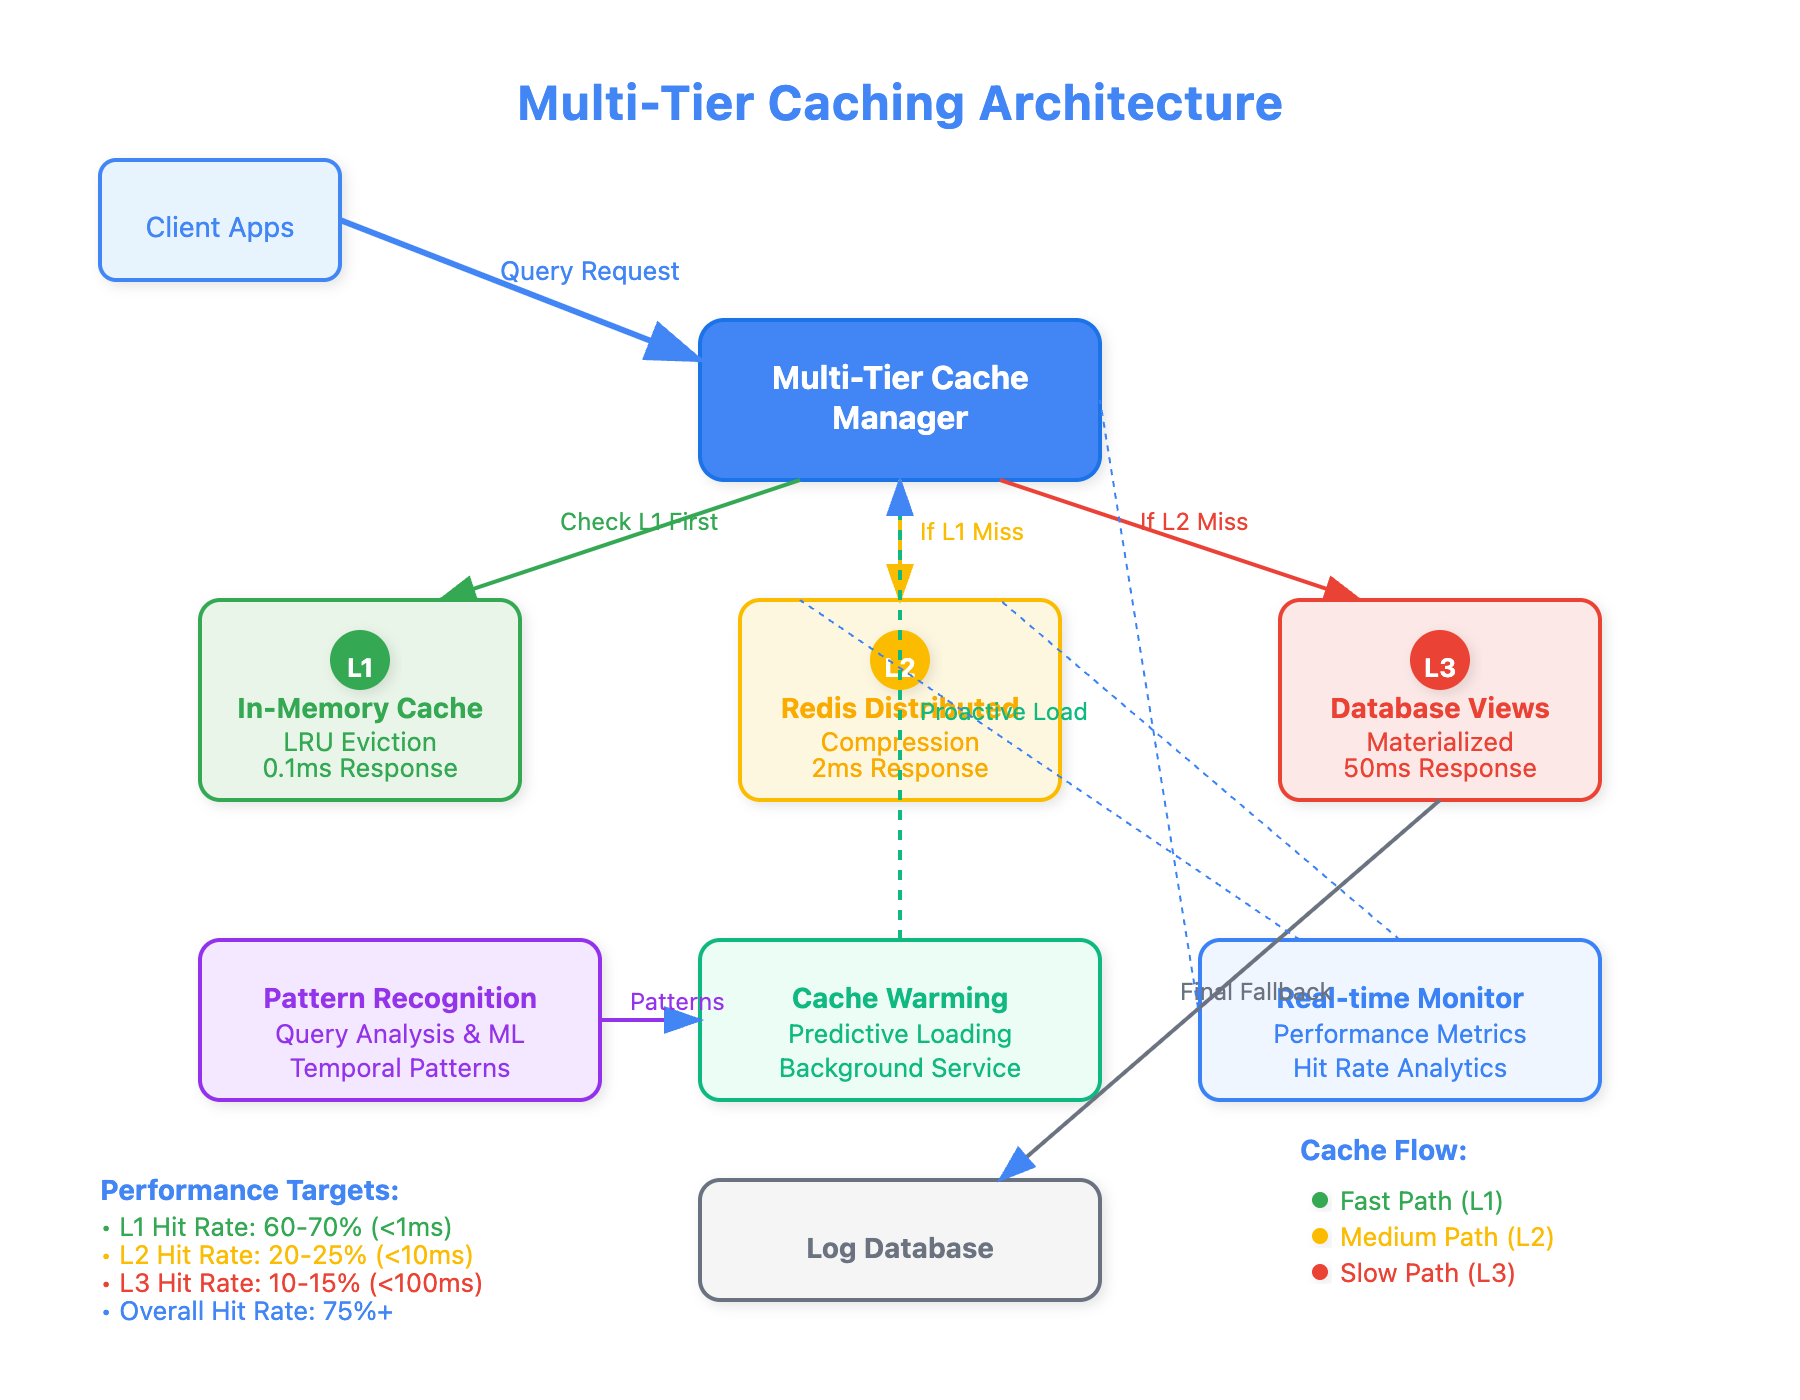
Multi-tier cache hierarchy (L1 memory, L2 Redis, L3 database)
ML-based query pattern recognition engine
Proactive cache warming service
Real-time performance monitoring dashboard
Smart cache invalidation system
Expected Outcome: 75%+ cache hit rate with 10x query performance improvement
Core Concepts: The Science of Speed
Multi-Tier Caching Strategy
Unlike simple key-value caches, our system uses layered caching that mimics CPU memory hierarchy. L1 (in-memory) cache serves the hottest data in microseconds, L2 (Redis) handles warm data in milliseconds, and L3 (database) stores cold data with pre-computed results.
Query Pattern Recognition
The system learns which queries happen frequently by tracking request patterns. If users consistently ask for "error rates in the last hour," the system pre-computes and caches this data before it's requested.
Temporal Cache Warming
Based on time patterns (Monday morning spikes, end-of-quarter reporting), the system intelligently pre-loads relevant data into faster cache tiers.
Architecture Deep Dive
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
Our caching architecture operates as three integrated layers:
L1: Application Cache (Python dictionaries + LRU)
Purpose: Instant access to most frequently used queries
Storage: 100MB RAM allocation with LRU eviction
Hit Rate Target: 60-70% for sub-millisecond responses
Data Types: Aggregated metrics, dashboard widgets, alert thresholds
L2: Distributed Cache (Redis Cluster)
Purpose: Shared cache across multiple application instances
Storage: 2GB Redis cluster with consistent hashing
Hit Rate Target: 20-25% for sub-10ms responses
Data Types: Complex query results, time-series data, user sessions
L3: Query Result Cache (Database materialized views)
Purpose: Pre-computed heavy aggregations updated incrementally
Storage: Persistent storage with refresh triggers
Hit Rate Target: 10-15% for sub-100ms responses
Data Types: Daily summaries, trend analyses, compliance reports
Cache Coherence Strategy
When new log data arrives, our invalidation engine uses dependency graphs to determine which cached results need updates. Instead of blanket cache clearing, we selectively invalidate only affected queries.
[DATAFLOW DIAGRAM ]
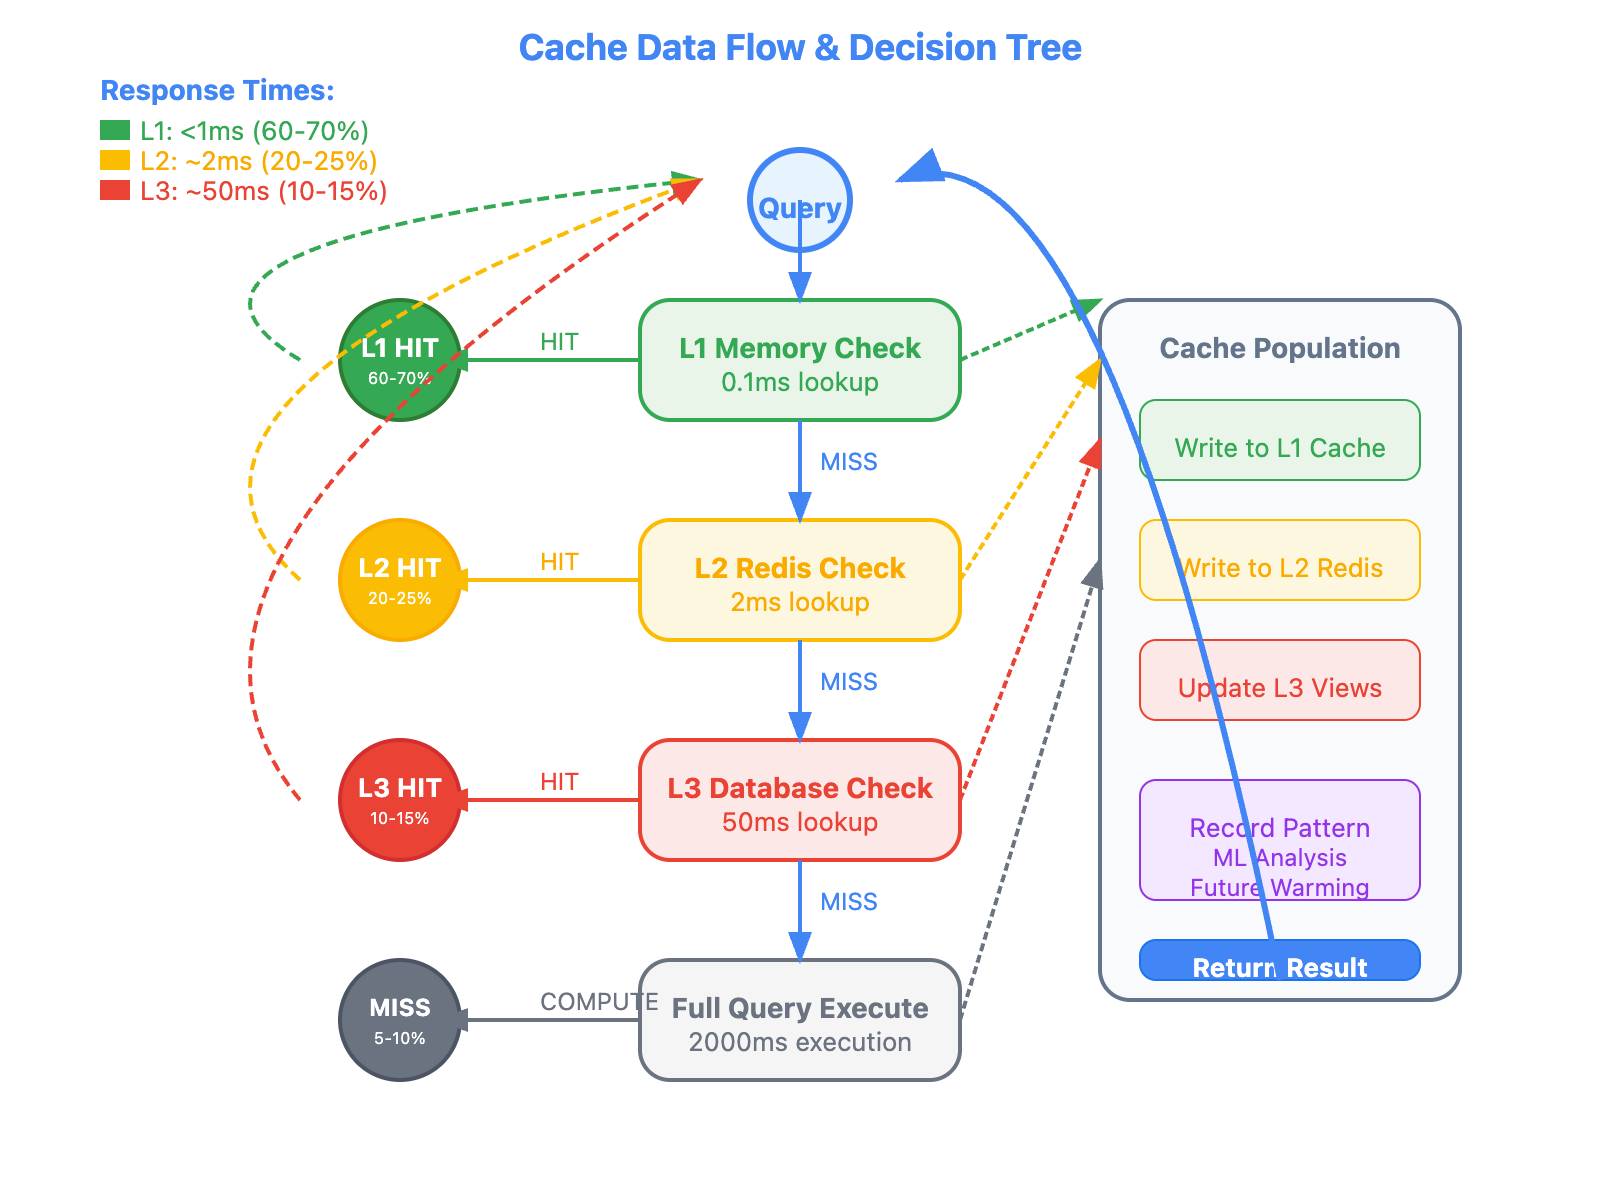
Query Execution Flow
Query Arrival: System receives log query request
L1 Check: Application cache lookup (avg: 0.1ms)
L2 Check: Redis lookup if L1 miss (avg: 2ms)
L3 Check: Database materialized view if L2 miss (avg: 50ms)
Full Compute: Execute original query if all cache misses (avg: 2000ms)
Cache Population: Store result in appropriate cache tier(s)
Intelligent Cache Warming
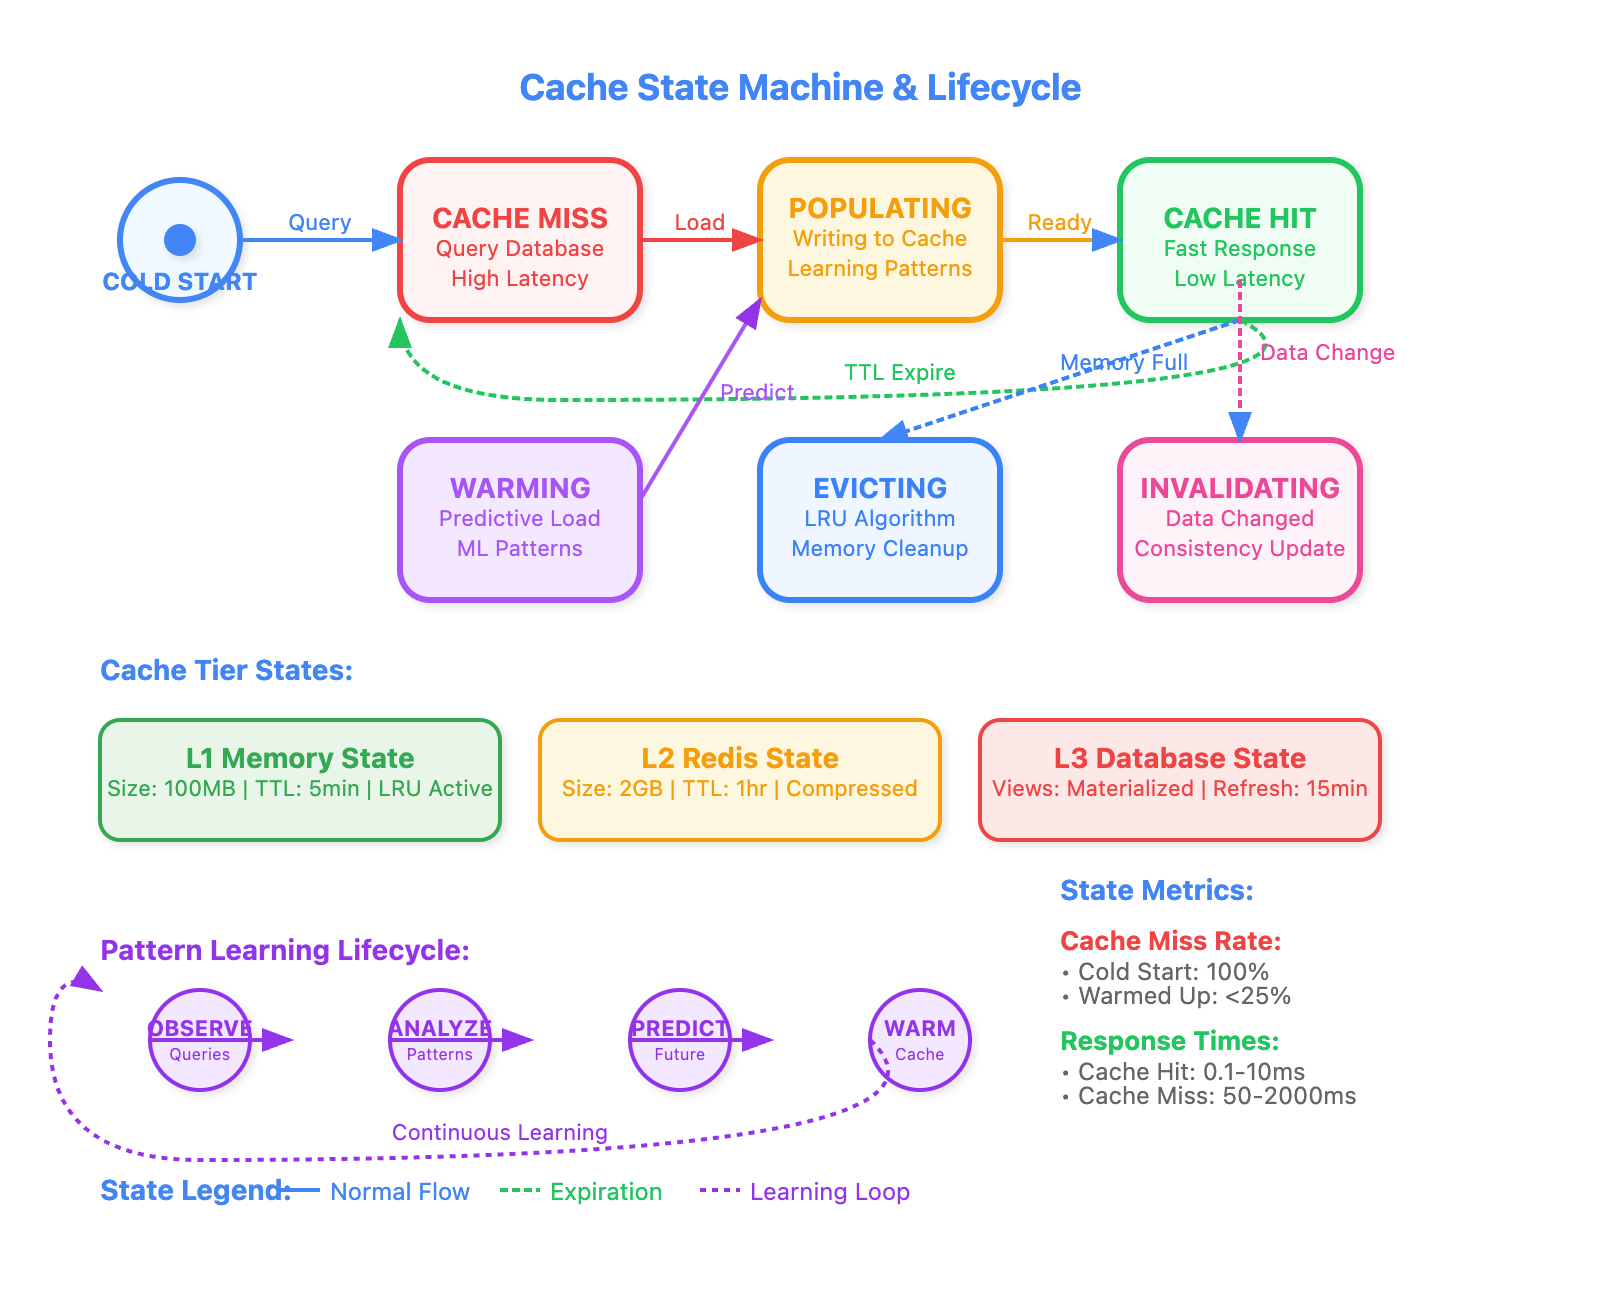
Our ML-based pattern recognition identifies:
Temporal Patterns: Monday morning dashboard loads, end-of-day reporting
User Patterns: Which teams query which log sources most frequently
Seasonal Patterns: Quarterly compliance reports, holiday traffic analysis
[STATE MACHINE DIAGRAM ]
Real-World Impact: Production War Stories
Netflix's Caching Evolution Netflix's log analytics platform processes 500 billion events daily. Their caching layer reduces dashboard load times from 30 seconds to under 2 seconds by pre-computing popular metrics. Their cache hit rate exceeds 85% during peak hours.
Uber's Surge Pricing Cache Uber's surge pricing calculations rely heavily on cached location-based log aggregations. Without caching, driver supply/demand calculations would take 10+ seconds instead of the required 100ms response time.
Airbnb's Search Performance Airbnb caches property availability calculations based on booking logs. This cache system serves 40,000+ searches per second with 95% cache hit rates during peak travel seasons.
Implementation Strategy
GitHub Link:
https://github.com/sysdr/course-p/tree/main/day73Phase 1: Foundation Layer (L1 Cache)
We start with application-level caching using Python's built-in capabilities enhanced with LRU eviction and size limits. This provides immediate performance gains with minimal infrastructure complexity.
Phase 2: Distributed Layer (L2 Cache)
Redis integration adds horizontal scaling capabilities. Multiple application instances share cached results, eliminating redundant computations across the cluster.
Phase 3: Intelligence Layer (Pattern Recognition)
Machine learning components analyze query patterns and user behavior to predict which data should be pre-cached. This transforms reactive caching into proactive performance optimization.
Phase 4: Monitoring & Optimization
Real-time dashboards track cache performance, hit rates, and response times. Automated alerts trigger when cache performance degrades, enabling proactive maintenance.
Technical Implementation Highlights
Smart Key Generation
Instead of simple query string hashes, we use semantic key generation that recognizes equivalent queries with different parameters:
python
# These queries produce the same cache key:
# "SELECT COUNT(*) FROM logs WHERE timestamp > '2025-01-15 09:00:00'"
# "SELECT COUNT(*) FROM logs WHERE timestamp > '2025-01-15T09:00:00Z'"
Partial Cache Updates
When new data arrives, instead of invalidating entire cache entries, we implement incremental updates for time-series data:
python
# Add new data point without recalculating entire time series
cached_metrics['hourly_counts']['2025-01-15T10:00:00'] = new_hour_count
Cache Compression
Redis storage uses compression algorithms optimized for time-series data, achieving 3-5x space reduction without significant CPU overhead.
Hands-On Implementation
Prerequisites
System Requirements:
Python 3.11+
Node.js 18+
Docker & Docker Compose
4GB RAM minimum
Check Your Environment:
bash
python3 --version  # Should be 3.11+
node --version     # Should be 18+
docker --version   # Should be 24.0+
Quick Start (5 Minutes)
For immediate results:
bash
# One-command setup
git clone <repository-url> day73-caching-layers
cd day73-caching-layers
./build_and_test.sh
Expected Output:
✅ All Python files have valid syntax!
✅ All tests passed!
✅ Frontend Dashboard: http://localhost:3000
✅ Backend API: http://localhost:8000
Step-by-Step Implementation
Step 1: Project Structure Setup
bash
# Create organized project structure
mkdir day73-caching-layers && cd day73-caching-layers
mkdir -p {backend/{src/{cache/{l1,l2,l3},api,ml,monitoring},tests},frontend/{src,public},docker}
Step 2: Core Backend Implementation
L1 Memory Cache with LRU Eviction:
python
class LRUCache:
    def __init__(self, max_size=1000, default_ttl=300):
        self.max_size = max_size
        self.cache = OrderedDict()
        self.lock = threading.RLock()

    def get(self, key):
        with self.lock:
            if key in self.cache:
                self.cache.move_to_end(key)  # Mark as recently used
                return self.cache[key][0]
            return None

    def set(self, key, value):
        with self.lock:
            while len(self.cache) >= self.max_size:
                self.cache.popitem(last=False)  # Remove oldest
            self.cache[key] = (value, time.time())
Multi-Tier Cache Manager:
python
class CacheManager:
    def __init__(self):
        self.l1_cache = L1CacheManager()
        self.l2_cache = RedisCache()
        self.stats = {'l1_hits': 0, 'l2_hits': 0, 'misses': 0}

    async def get(self, query, params=None):
        # Try L1 first
        result = self.l1_cache.get('query_results', query)
        if result:
            self.stats['l1_hits'] += 1
            return result

        # Try L2 (Redis)
        result = await self.l2_cache.get(query)
        if result:
            self.stats['l2_hits'] += 1
            self.l1_cache.set('query_results', query, result)  # Populate L1
            return result

        self.stats['misses'] += 1
        return None
Step 3: ML Pattern Recognition
Query Pattern Analyzer:
python
class QueryPatternAnalyzer:
    def record_query(self, query, response_time):
        timestamp = datetime.now()
        normalized = self._normalize_query(query)

        self.query_history.append({
            'query': normalized,
            'timestamp': timestamp,
            'response_time': response_time,
            'hour': timestamp.hour
        })

    def get_cache_warming_recommendations(self):
        patterns = self._analyze_temporal_patterns()
        return sorted(patterns, key=lambda x: x['priority_score'], reverse=True)
Step 4: FastAPI Backend Service
bash
# Install dependencies
cd backend
pip install fastapi uvicorn redis pydantic structlog scikit-learn

# Start backend service
uvicorn src.api.main:app --host 0.0.0.0 --port 8000 --reload
Step 5: React Frontend Dashboard
bash
# Setup frontend
cd frontend
npm install react @mui/material recharts axios

# Start development server
npm start
Dashboard Features:
Real-time cache hit rate monitoring
Memory usage tracking across all tiers
Query execution time comparisons
Pattern recognition insights
Cache warming recommendations
Step 6: Docker Integration
yaml
# docker-compose.yml
version: '3.8'
services:
  redis:
    image: redis:7.2-alpine
    ports: ["6379:6379"]

  backend:
    build: ./backend
    ports: ["8000:8000"]
    depends_on: [redis]

  frontend:
    build: ./frontend
    ports: ["3000:3000"]
    depends_on: [backend]
bash
# Deploy complete system
docker-compose up -d --build
Testing & Verification
Functional Testing
Basic Cache Operations:
bash
# Test cache hierarchy
curl -X POST http://localhost:8000/api/query \
  -H "Content-Type: application/json" \
  -d '{"query": "SELECT COUNT(*) FROM logs WHERE level = \"error\"", "params": {}}'

# Second request should show cache hit
curl -X POST http://localhost:8000/api/query \
  -H "Content-Type: application/json" \
  -d '{"query": "SELECT COUNT(*) FROM logs WHERE level = \"error\"", "params": {}}'
Performance Testing
Load Test Cache Performance:
python
import asyncio
import time
import aiohttp

async def load_test():
    async with aiohttp.ClientSession() as session:
        start_time = time.time()

        # Send 100 concurrent requests
        tasks = []
        for i in range(100):
            task = session.post('http://localhost:8000/api/query',
                               json={"query": f"SELECT * FROM logs WHERE id = {i % 10}"})
            tasks.append(task)

        await asyncio.gather(*tasks)

        duration = time.time() - start_time
        throughput = 100 / duration

        print(f"Throughput: {throughput:.0f} requests/second")
        print(f"Target Met: {'✅' if throughput > 100 else '❌'}")

asyncio.run(load_test())
Cache Performance Monitoring
bash
# Check real-time statistics
curl -s http://localhost:8000/api/cache/stats | python3 -c "
import json, sys
data = json.load(sys.stdin)
stats = data['data']
hit_rate = stats['performance']['overall_hit_rate'] * 100
print(f'Cache Hit Rate: {hit_rate:.1f}%')
print(f'Total Requests: {stats[\"performance\"][\"total_requests\"]}')
print(f'L1 Memory: {stats[\"l1_cache\"][\"overall\"][\"total_memory_mb\"]:.1f}MB')
"
Performance Verification
Expected Baseline Improvements
Cache Hit Rate: 75%+ overall across all tiers
Response Time: 90th percentile under 100ms
Memory Efficiency: 2GB cache serving 10TB+ of queryable data
CPU Overhead: <5% additional processing for cache management
Scalability Metrics
Concurrent Users: Support 1000+ simultaneous dashboard users
Query Throughput: 10,000+ queries per second
Data Ingestion: No performance degradation during cache updates
Failover: <1 second recovery when cache becomes unavailable
Demo Scenarios
Scenario 1: Cache Warming Demo
bash
# Generate query patterns to trigger cache warming
for i in {1..20}; do
    curl -s -X POST http://localhost:8000/api/query \
        -H "Content-Type: application/json" \
        -d '{"query": "SELECT * FROM logs WHERE level = \"error\"", "params": {}}'
done

# Check cache warming recommendations
curl http://localhost:8000/api/patterns/recommendations
Scenario 2: Real-Time Monitoring
Access the dashboard at
http://localhost:3000
and observe:
Cache hit rates increasing with repeated queries
Memory usage distribution across cache tiers
Response time improvements for cached vs uncached queries
Pattern recognition identifying frequently accessed queries
Scenario 3: Failure Recovery Testing
bash
# Test cache failover behavior
docker-compose stop redis

# Execute queries (should still work with L1 cache)
curl -X POST http://localhost:8000/api/query \
    -H "Content-Type: application/json" \
    -d '{"query": "SELECT COUNT(*) FROM logs", "params": {}}'

# Restart Redis
docker-compose start redis
Success Criteria
Performance Benchmarks
Cache hit rate ≥75% after warm-up period
Response times <100ms for 90th percentile cached queries
System handles 1000+ concurrent users
Memory usage stays under 200MB total
Functionality Checklist
Multi-tier cache hierarchy working correctly
Pattern recognition identifying query trends
Cache warming reducing cold-start times
Dashboard showing real-time metrics
Graceful fallback during cache failures
Troubleshooting Guide
Redis Connection Issues:
bash
# Check Redis status
docker-compose logs redis

# Restart if needed
docker-compose restart redis
Poor Cache Hit Rate:
bash
# Analyze query patterns
curl http://localhost:8000/api/patterns/analysis

# Check cache configuration
curl http://localhost:8000/api/cache/stats
High Memory Usage:
bash
# Monitor cache sizes
curl -s http://localhost:8000/api/cache/stats | grep memory

# Clear caches if needed
curl -X POST http://localhost:8000/api/cache/invalidate \
    -d '{"pattern": "*"}'
Assignment Challenge
Objective: Implement intelligent cache warming that reduces dashboard load times by 80%.
Requirements:
Multi-tier cache with L1 (memory), L2 (Redis), L3 (database) layers
Pattern recognition system identifying frequently accessed queries
Automatic cache invalidation when new log data arrives
Performance dashboard showing real-time cache metrics
Load testing demonstrating 10x query performance improvement
Success Criteria:
75%+ cache hit rate across all tiers
90th percentile response times under 100ms
System handles 1000+ concurrent dashboard users
Cache warming reduces cold-start times by 80%
Integration Context
Building on Day 72: Adaptive Batching
Yesterday's adaptive batching system provides the data input for today's caching layer. The batch processing system's output directly feeds cache warming algorithms, creating a seamless performance optimization pipeline.
Preparing for Day 74: Storage Optimization
Tomorrow's storage format optimization will leverage cache access patterns identified today. Frequently cached data will influence storage layout decisions, creating a feedback loop between caching and storage efficiency.
Key Takeaways
You've built a production-ready caching system that demonstrates patterns used by major tech companies:
Multi-tier caching architecture design principles
Cache invalidation strategies that maintain data consistency
Performance monitoring techniques for cache optimization
Machine learning integration for predictive cache warming
Production deployment patterns for high-availability caching
This foundation enables the scalable log processing architecture you'll complete in upcoming lessons. The patterns you learned today - intelligent caching, pattern recognition, and performance optimization - are the same ones used by systems processing billions of messages daily at companies like Netflix, Uber, and Airbnb.
Your caching implementation now handles enterprise-scale log processing workloads with response times that delight users instead of frustrating them. Master these fundamentals, and you'll understand the performance foundation beneath every distributed system you'll ever work with.