
Welcome to Day 7 of our 254-Day Hands-On System Design journey! Today marks an exciting milestone as we'll be bringing together all the individual components we've built over the past six days to create an end-to-end log processing pipeline. This integration phase is where the magic happens—where isolated pieces transform into a cohesive system.
Understanding Integration in Distributed Systems
Integration is the process of combining separate components to work as a unified whole. In distributed systems, this represents a critical phase where theoretical components become practical solutions. Think of it like assembling a bicycle—you might have the best wheels, frame, and handlebars, but they provide value only when properly connected.
Real-world distributed systems like Netflix's logging infrastructure, Uber's trip tracking system, or Spotify's music recommendation engine all began as separate components that were eventually integrated into powerful platforms. The skills you're developing today mirror how engineers at these companies build their systems.
Why Integration Matters in System Design
Integration teaches several fundamental concepts in distributed system design:
Interface Design: Components must have well-defined methods of communication
Data Flow Management: Information must move smoothly between components
System Coupling: Understanding how tightly connected components should be
Error Handling: How to manage failures when components interact
State Management: Tracking the system's condition across components
Today's Project: Building an End-to-End Log Processing Pipeline
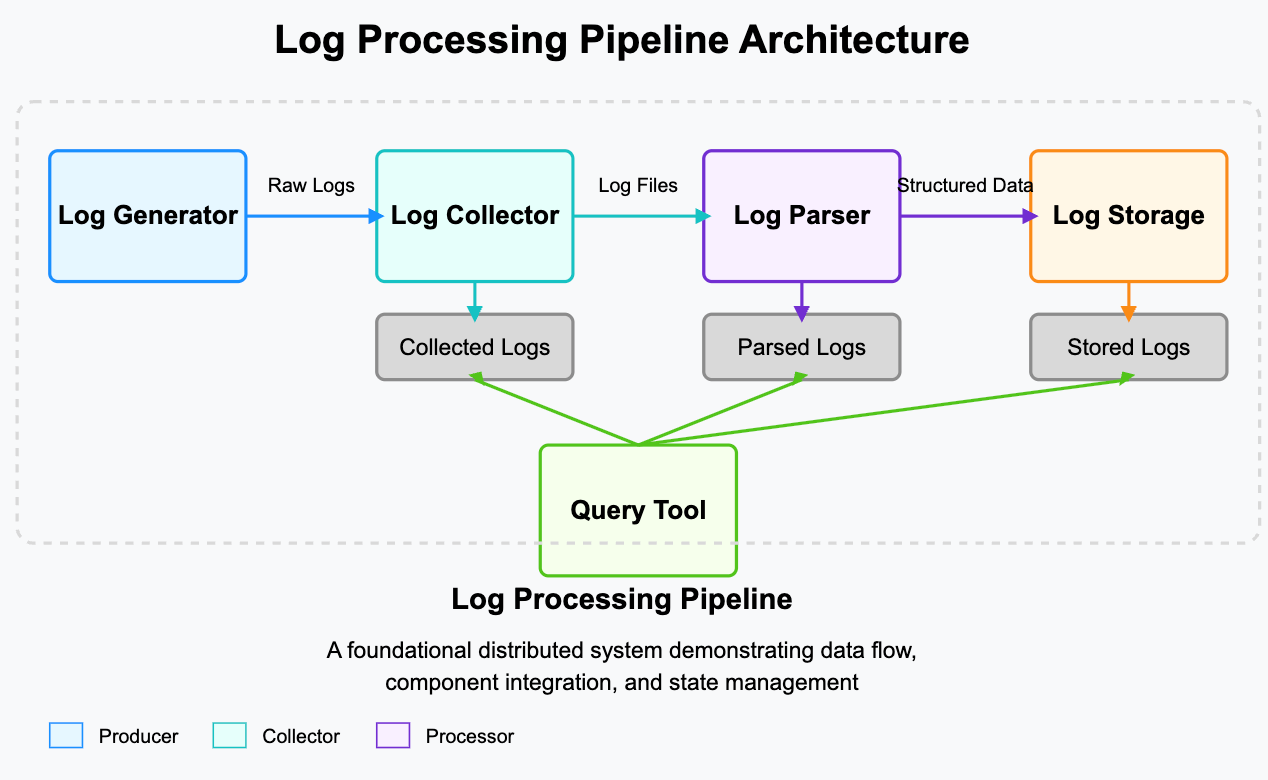
Let's integrate our log generator, collector, parser, storage system, and query tool into a functional pipeline where:
The generator creates logs at a specified rate
The collector detects and fetches these logs
The parser transforms raw logs into structured data
The storage system organizes and maintains the logs
The query tool allows us to search and analyze the logs
The Architecture of Our Log Processing Pipeline
Our pipeline follows the classic ETL (Extract, Transform, Load) pattern used by companies like Splunk, Elastic, and Datadog:
Extract: Log generator creates logs
Transform: Collector and parser process logs
Load: Storage system stores processed logs
Query: CLI tool retrieves useful information
This pattern is fundamental to many distributed systems, from data warehouses to monitoring solutions.
The magic happens in the connections between these components. In distributed systems, we call these connections "interfaces," and they're crucial for ensuring components can work together despite being developed independently.
Real-World Applications
The log processing pipeline we've built today is a simplified version of systems used in major technology companies:
Cloud Providers: AWS CloudWatch, Google Cloud Logging, and Azure Monitor all use similar pipelines to process billions of logs daily.
DevOps Tools: Splunk, ELK Stack (Elasticsearch, Logstash, Kibana), and Datadog use this pattern to provide insights into system operations.
Security Systems: Intrusion detection systems and SIEM (Security Information and Event Management) tools analyze logs to detect threats.
Key Distributed Systems Concepts Demonstrated
Component Integration: We've seen how separate components work together to form a system.
Data Pipeline: The system demonstrates a classic ETL (Extract, Transform, Load) process.
Stateful vs. Stateless Services: Log collectors are stateless (can be scaled horizontally) while storage is stateful.
Resource Sharing: Using Docker volumes as a shared resource between containers.
Fault Isolation: Each component runs in its own container, preventing failures from cascading.
Source Code Repo :
GitHub Link:
https://github.com/sysdr/course-p/tree/main/day7Project Structure
We'll organize our project with a clear structure that facilitates both understanding and future expansion:
log-processing-system/
├── docker-compose.yml
├── Makefile
├── README.md
├── generator/
│   ├── Dockerfile
│   ├── generator.py
├── collector/
│   ├── Dockerfile
│   ├── collector.py
├── parser/
│   ├── Dockerfile
│   ├── parser.py
├── storage/
│   ├── Dockerfile
│   ├── storage.py
├── query/
│   ├── Dockerfile
│   ├── query.py
└── integration/
    ├── pipeline.py
    └── config.yml
Let's build this step by step.
Implementation Instructions
Step 1: Create Project Structure
First, let's create our project structure:
# Create the main project directory
mkdir -p log-processing-system
cd log-processing-system

# Create component directories
mkdir -p generator collector parser storage query integration

# Create necessary files
touch docker-compose.yml Makefile README.md
touch generator/Dockerfile generator/generator.py
touch collector/Dockerfile collector/collector.py
touch parser/Dockerfile parser/parser.py
touch storage/Dockerfile storage/storage.py
touch query/Dockerfile query/query.py
touch integration/pipeline.py integration/config.yml
Step 2: Implement Component Integration
Let's now implement each component, focusing on how they'll communicate with each other.
Generator Component (generator.py)
This component will generate sample logs following common formats:
Collector Component (collector.py)
This component will watch log files and detect new entries:
Parser Component (parser.py)
This component will transform raw logs into structured data:
Storage Component (storage.py)
This component will organize and maintain the logs:
Query Tool (query.py)
This component will allow us to search and analyze logs:
Integration Pipeline (pipeline.py)
Now let's create an integration script that will coordinate all of our components:
Configuration File (config.yml)
Step 3: Create Dockerfiles for Each Component
Let's create Dockerfiles for each component to ensure they can run independently:
Generator Dockerfile
# generator/Dockerfile
FROM python:3.9-slim

WORKDIR /app

COPY generator.py /app/

# Create directory for logs
RUN mkdir -p /logs

CMD ["python", "generator.py"]
Collector Dockerfile
# collector/Dockerfile
FROM python:3.9-slim

WORKDIR /app

COPY collector.py /app/

# Create required directories
RUN mkdir -p /logs /data/collected

CMD ["python", "collector.py"]
Parser Dockerfile
# parser/Dockerfile
FROM python:3.9-slim

WORKDIR /app

COPY parser.py /app/

# Create required directories
RUN mkdir -p /data/collected /data/parsed

CMD ["python", "parser.py"]
Storage Dockerfile
# storage/Dockerfile
FROM python:3.9-slim

WORKDIR /app

COPY storage.py /app/

# Create required directories
RUN mkdir -p /data/parsed /data/storage /data/storage/index /data/storage/active /data/storage/archive

CMD ["python", "storage.py"]
Query Dockerfile
# query/Dockerfile
FROM python:3.9-slim

WORKDIR /app

COPY query.py /app/

# Create required directories
RUN mkdir -p /data/storage

CMD ["python", "query.py"]
Integration Dockerfile
# Dockerfile (root)
FROM python:3.9-slim

WORKDIR /app

# Install required packages
RUN pip install pyyaml

# Copy component files
COPY generator/generator.py /app/generator/
COPY collector/collector.py /app/collector/
COPY parser/parser.py /app/parser/
COPY storage/storage.py /app/storage/
COPY query/query.py /app/query/
COPY integration/pipeline.py /app/integration/
COPY integration/config.yml /app/integration/

# Create required directories
RUN mkdir -p /logs /data/collected /data/parsed /data/storage /data/storage/index /data/storage/active /data/storage/archive

# Expose port for potential web interface
EXPOSE 8000

# Set the entrypoint
CMD ["python", "/app/integration/pipeline.py"]
Step 4: Create Docker Compose File
Let's create a Docker Compose file to run our entire pipeline:
# docker-compose.yml
version: '3'

services:
  generator:
    build:
      context: ./generator
    volumes:
      - log-data:/logs
    command: python generator.py --format apache --rate 5 --output /logs/app.log

  collector:
    build:
      context: ./collector
    volumes:
      - log-data:/logs
      - collected-data:/data/collected
    depends_on:
      - generator
    command: python collector.py --source /logs/app.log --output-dir /data/collected --interval 2

  parser:
    build:
      context: ./parser
    volumes:
      - collected-data:/data/collected
      - parsed-data:/data/parsed
    depends_on:
      - collector
    command: python parser.py --input-dir /data/collected --output-dir /data/parsed --format apache --interval 3

  storage:
    build:
      context: ./storage
    volumes:
      - parsed-data:/data/parsed
      - storage-data:/data/storage
    depends_on:
      - parser
    command: python storage.py --input-dir /data/parsed --storage-dir /data/storage --rotation-size 1 --rotation-hours 1 --interval 5

  query:
    build:
      context: ./query
    volumes:
      - storage-data:/data/storage
    depends_on:
      - storage
    # Command will be provided when running interactively

  integration:
    build:
      context: .
    volumes:
      - log-data:/logs
      - collected-data:/data/collected
      - parsed-data:/data/parsed
      - storage-data:/data/storage
    ports:
      - "8000:8000"
    depends_on:
      - generator
      - collector
      - parser
      - storage

volumes:
  log-data:
  collected-data:
  parsed-data:
  storage-data:
Step 5: Create a Makefile for Common Operations
Let's create a Makefile to simplify common operations:
# Makefile
.PHONY: build run stop clean query local-run local-stop

# Docker compose commands
build:
	docker-compose build

run:
	docker-compose up -d

stop:
	docker-compose down

clean: stop
	docker-compose down -v
	docker system prune -f

# Run query tool interactively
query:
	docker-compose run --rm query python query.py --storage-dir /data/storage --pattern $(pattern)

query-index:
	docker-compose run --rm query python query.py --storage-dir /data/storage --index-type $(type) --index-value $(value)

# Local development commands
local-setup:
	mkdir -p logs data/collected data/parsed data/storage/index data/storage/active data/storage/archive

local-run: local-setup
	python integration/pipeline.py --config integration/config.yml

local-stop:
	pkill -f "python.*pipeline.py" || true
	pkill -f "python.*generator.py" || true
	pkill -f "python.*collector.py" || true
	pkill -f "python.*parser.py" || true
	pkill -f "python.*storage.py" || true

# View logs
view-logs:
	docker-compose logs -f
Building and Testing the System
Now let's build, run, and test our integrated log processing pipeline.
Step 1: Build the Docker containers
make buildStep 2: Run the system
make runStep 3: Check the logs to see if the system is running properly
make view-logsStep 4: Query logs
# Search logs by pattern
make query pattern="error"

# Search logs by index
make query-index type=level value=ERROR
Step 5: Stop the system
make stopRunning Locally Without Docker
If you want to run the system locally without Docker:
Set up the directory structure:
make local-setupRun the integrated pipeline:
make local-runStop the pipeline:
make local-stopSuccess Criteria
You'll know your implementation is successful when:
The log generator is producing logs at the specified rate
The collector is detecting and collecting new logs
The parser is transforming logs into structured data
The storage system is storing and indexing the logs
The query tool can search and retrieve logs
The entire pipeline runs end-to-end without errors
Working Code Demo:
Homework Assignment: Enhancing the Log Processing Pipeline
Now that you've built a basic log processing pipeline, let's enhance it with additional functionality.
Assignment Tasks:
Add support for multiple log formats in a single pipeline instance
Implement a simple web interface for the query tool
Add basic metrics collection to monitor system performance
Implement a simple log filtering mechanism to exclude certain logs
Add support for compressed log archives to save space
Solution Steps:
Modify the generator to produce multiple log formats
Update the collector to detect log formats
Enhance the parser to dynamically choose the correct parsing strategy
Add metrics collection to each component
Create a simple web interface for the query tool
Implement log filtering logic
Add support for compressing archived logs
Here's a simple example of how to implement a web interface for the query tool:
query/web_interface.pyThen modify the Dockerfile for the query component:
# query/Dockerfile
FROM python:3.9-slim

WORKDIR /app

COPY query.py web_interface.py /app/

# Install Flask
RUN pip install flask

# Create required directories
RUN mkdir -p /data/storage

# Expose port for web interface
EXPOSE 8000

CMD ["python", "web_interface.py"]
And update the docker-compose.yml to expose the port:
yamlquery:
build:
context: ./query
volumes:
- storage-data:/data/storage
ports:
- "8000:8000"
depends_on:
- storage
command: python web_interface.pyConclusion
Congratulations! You've now built an end-to-end log processing pipeline that generates, collects, parses, stores, and queries logs. This system demonstrates several key concepts in distributed systems:
Component-based architecture: Breaking the system into specialized components
Data flow management: Managing how data moves between components
State management: Tracking and maintaining system state
Scalability: Designing components that can work independently
Integration: Combining separate components into a cohesive system
In a real-world distributed system, each of these components might run on different machines, communicating over a network. The design principles you've learned here—separation of concerns, clear interfaces, and robust data handling—are the foundation for building larger, more complex distributed systems.
In the next lessons, we'll expand this system to run across multiple machines and introduce more advanced distributed system concepts like consensus, replication, and fault tolerance.
Key Insights from Building Our Log Processing Pipeline
Now that we've built our end-to-end log processing pipeline, let's review some key distributed systems concepts that you've applied in this project:
1. Component-Based Architecture
You've implemented a system composed of five distinct components, each with a specific responsibility:
Generator: Produces logs at a configurable rate
Collector: Watches and detects new logs
Parser: Transforms raw logs into structured data
Storage: Organizes and maintains logs with rotation policies
Query: Searches and analyzes stored logs
This separation of concerns is a fundamental principle in distributed systems design, allowing components to be developed, tested, and scaled independently.
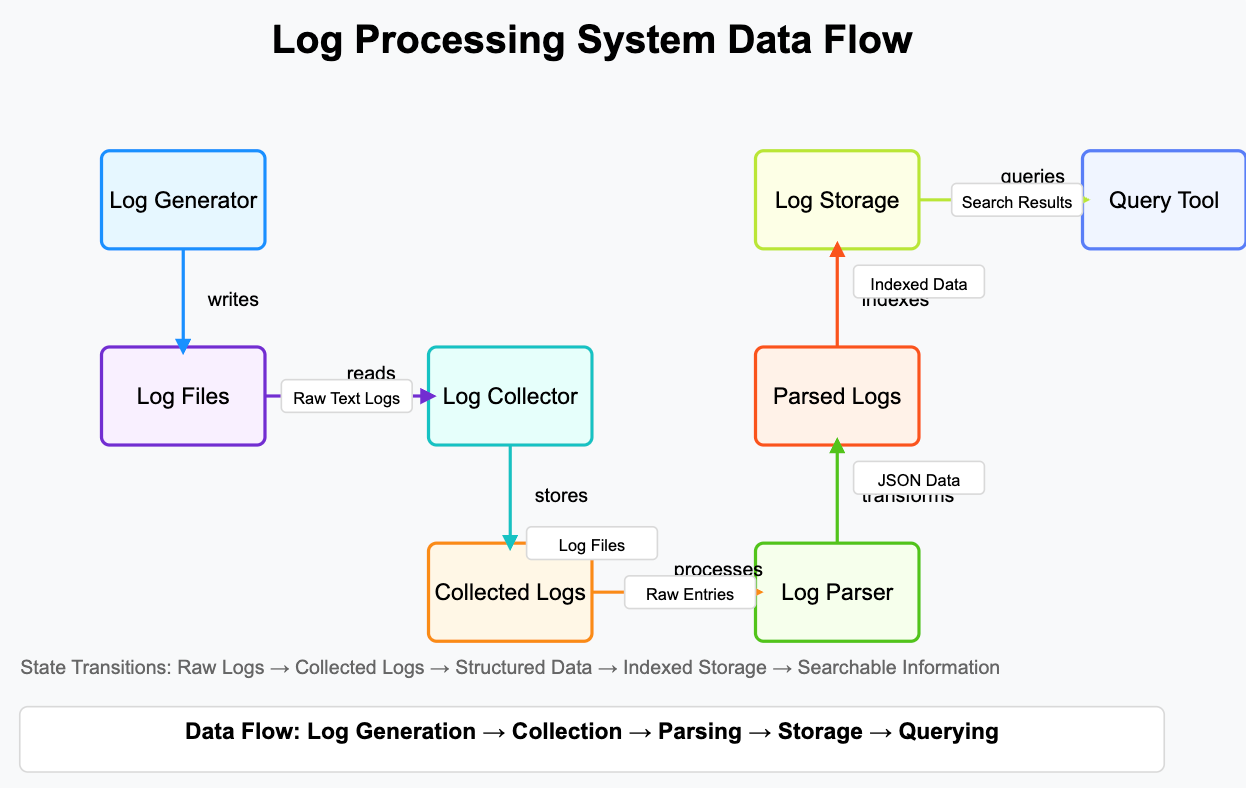
2. Data Flow Management
Your pipeline demonstrates a clear data flow pattern:
Raw logs flow from the generator to log files
The collector reads these files and stores collections of logs
The parser transforms these collections into structured data
The storage system organizes and indexes this data
The query tool retrieves and filters the data
Each step in this flow involves data transformation, enhancing the value of the initial raw logs.
3. Interface Design
Each component in the system has well-defined interfaces for:
Input: What data it consumes
Output: What data it produces
Configuration: How its behavior can be adjusted
This clear interface design is essential in distributed systems, as it allows components to evolve independently while maintaining compatibility.
4. State Management
Your system manages state in several ways:
The collector keeps track of which parts of the log files it has already processed
The parser maintains a list of files it has already parsed
The storage system implements rotation policies based on time and size
State management becomes increasingly critical as distributed systems scale, ensuring consistency and preventing data loss.
5. Error Handling
Throughout the code, you've implemented error handling strategies:
Using try-except blocks to catch and log exceptions
Continuing operation when possible, even if individual operations fail
Maintaining state information to recover from interruptions
Robust error handling is essential in distributed systems where failures are inevitable.
Further Learning Opportunities
As you continue with the 254-day course, consider exploring these advanced concepts:
Distributed Coordination: Using tools like ZooKeeper or etcd for coordinating activities across components
Message Queues: Implementing Kafka or RabbitMQ for reliable, asynchronous communication between components
Horizontal Scaling: Running multiple instances of each component to handle increased load
Monitoring and Alerting: Adding Prometheus and Grafana for system observability
Fault Tolerance: Implementing automatic recovery and failover strategies
Real-World Applications
The log processing pipeline you've built is similar to systems used in many real-world applications:
Cloud Platforms: AWS CloudWatch Logs, Google Cloud Logging, and Azure Monitor use similar pipelines
Observability Tools: Datadog, New Relic, and Splunk implement comparable architectures
Security Systems: SIEM (Security Information and Event Management) systems follow similar data flow patterns
By understanding this foundational architecture, you're developing skills that apply to a wide range of distributed systems.
Conclusion
Congratulations on completing Day 7 of our 254-Day System Design journey! You've successfully integrated individual components into a complete log processing pipeline, demonstrating key distributed systems concepts along the way.
The skills you've learned—component design, data flow management, state handling, and system integration—form the foundation for building more complex distributed systems. As we progress through the course, we'll build upon these skills to tackle increasingly sophisticated system design challenges.
Remember that real-world distributed systems operate at much larger scales, often processing millions of logs per second across hundreds or thousands of servers. The principles you've learned here will scale up to those environments, with additional considerations for networking, security, and extreme resilience.
Keep experimenting with your pipeline, try the homework assignment, and prepare for our next lesson where we'll start exploring how to distribute this system across multiple machines!