
What We’re Building Today
Yesterday we wired multi-region replication across our log pipeline. Today we harden that pipeline against the inevitable: components go down, networks partition, downstream services time out. We add circuit breakers — the single most important resilience pattern in any distributed system — directly into our log processing flow.
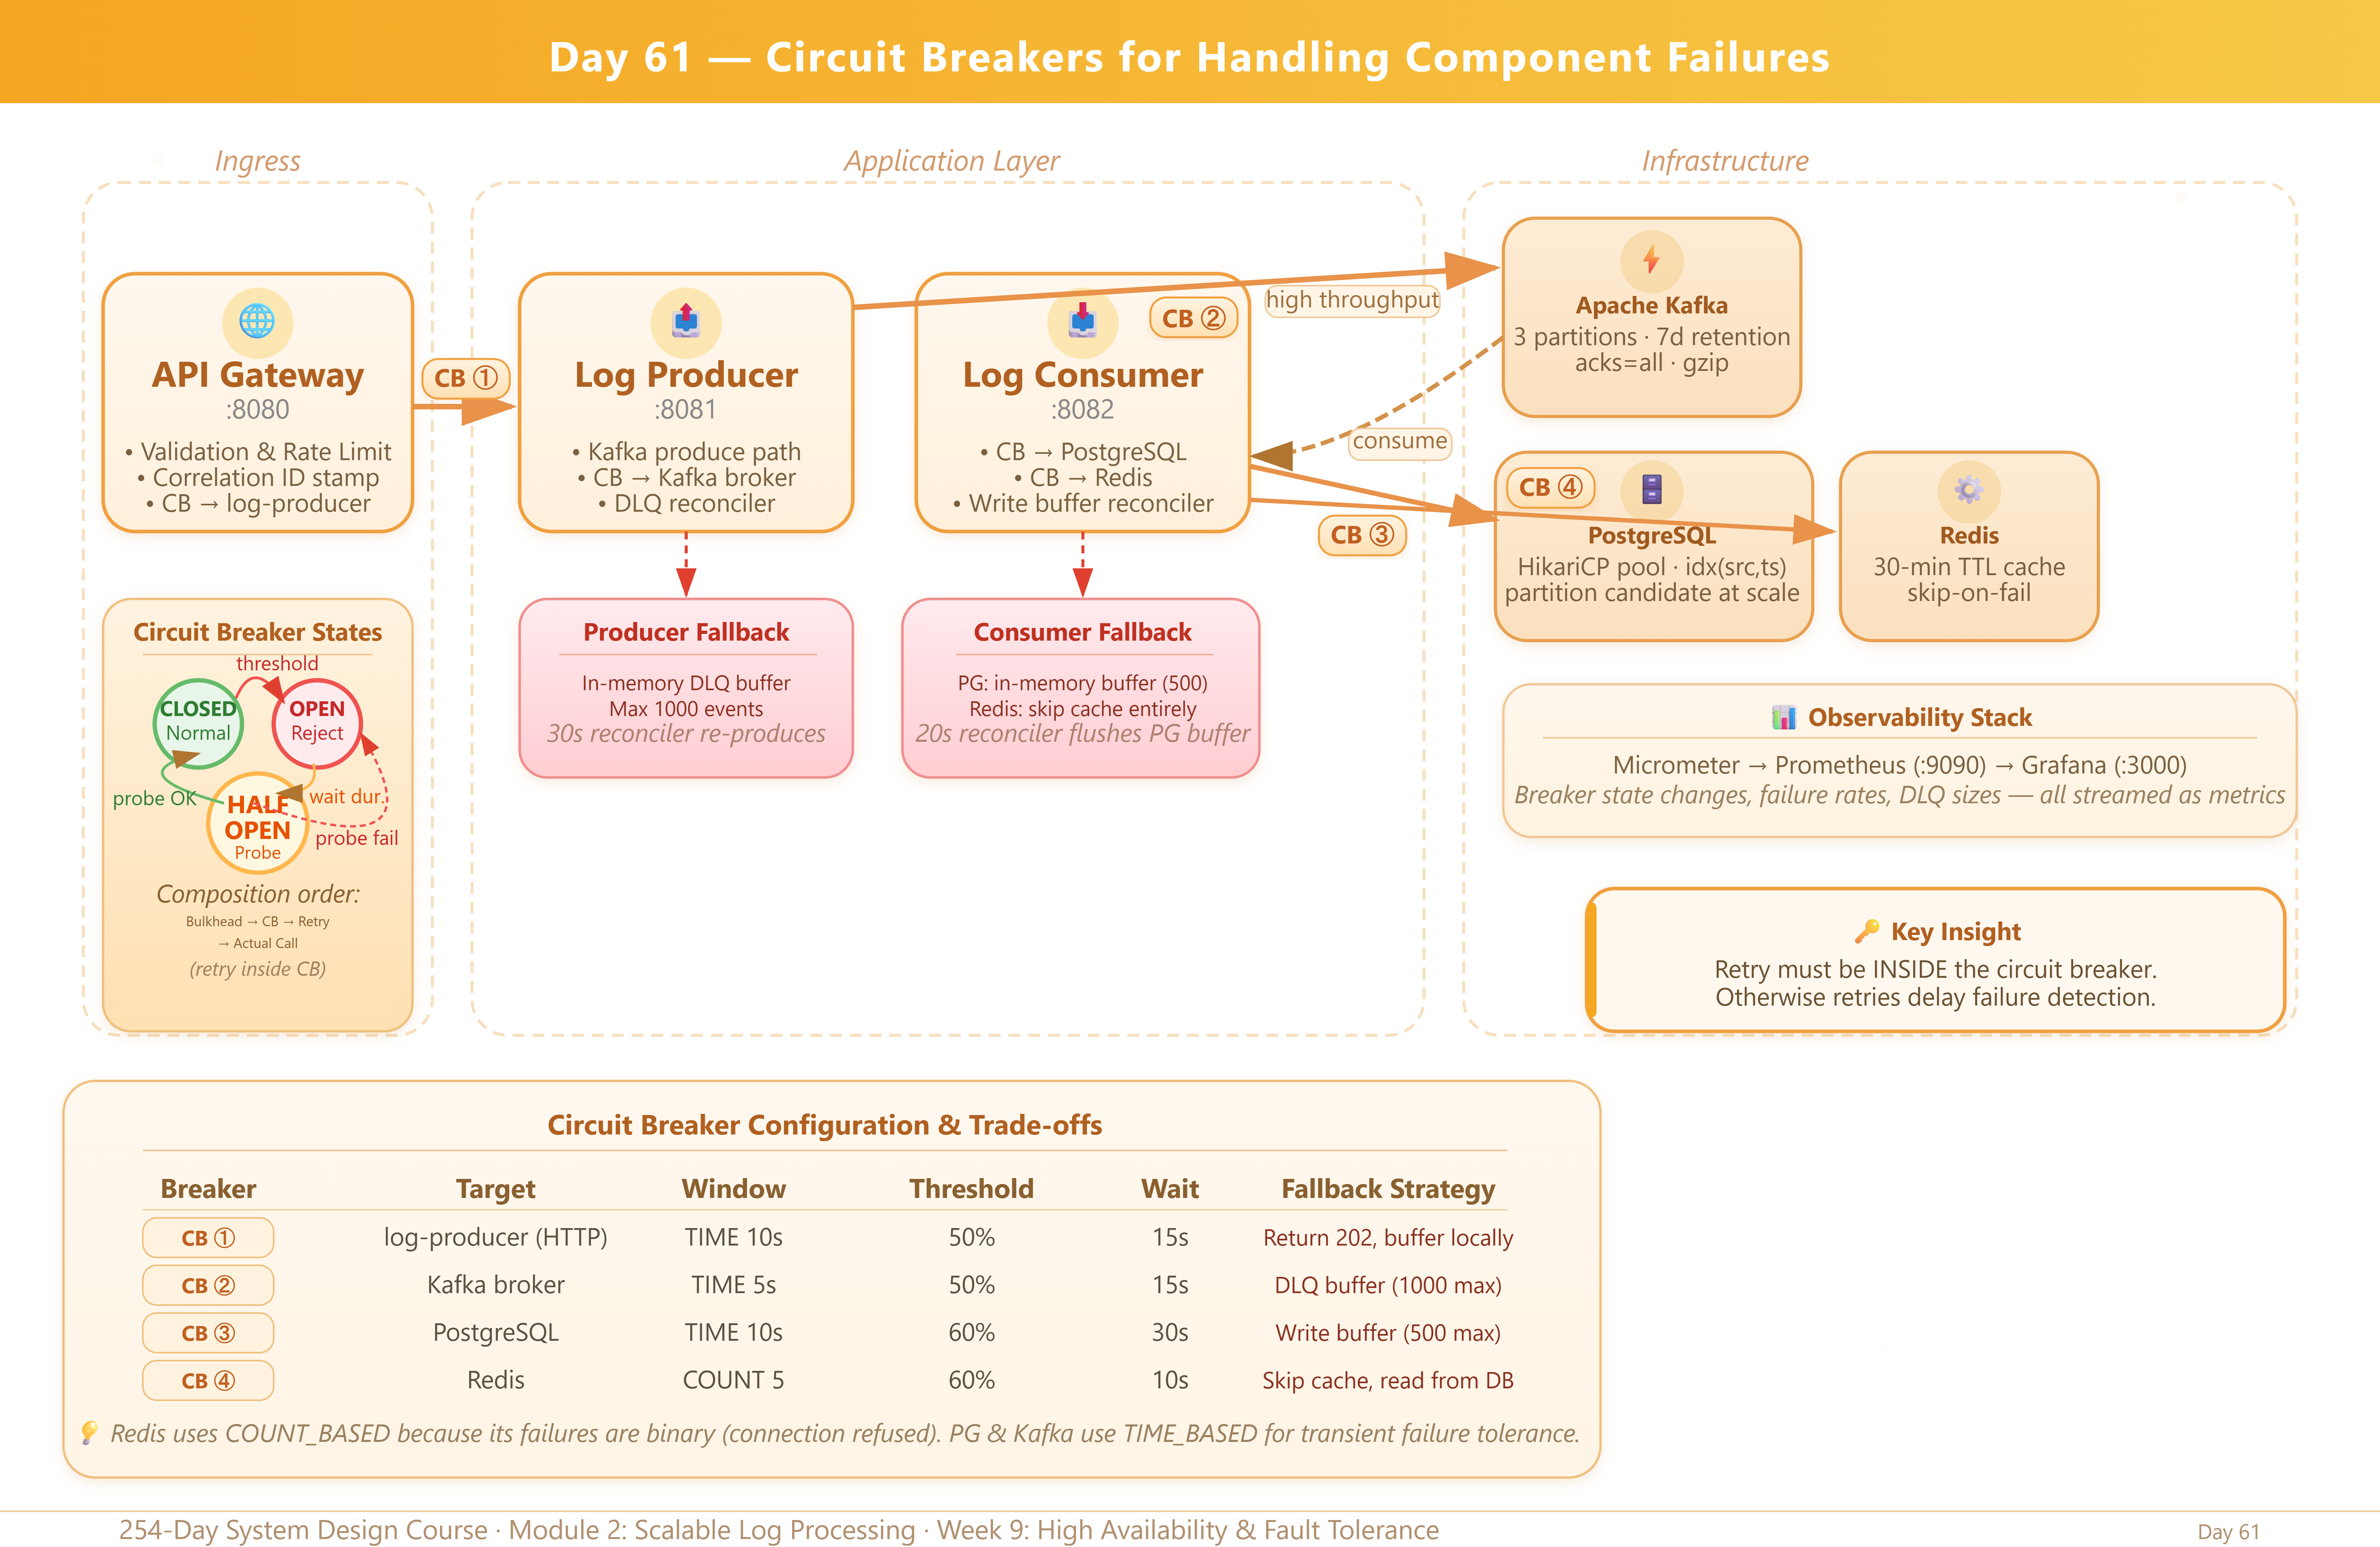
Circuit breaker wrappers around every outbound service call (Kafka produce, Redis cache-write, PostgreSQL persist)
State-machine-driven failure detection with configurable thresholds, timeouts, and half-open probing
Fallback strategies that keep the pipeline moving when a downstream is dead
Real-time health dashboards in Grafana that surface breaker trips before your on-call page fires
Why This Matters
Multi-region replication (Day 60) gave us durability. But durability without availability is just a well-preserved corpse. A single slow PostgreSQL replica can hold up every consumer thread if we let synchronous calls block indefinitely. In production at scale, this is not a hypothetical — it is a certainty. Netflix’s Hystrix documentation famously documented how a single downstream latency spike in their recommendation service cascaded into a full outage because every thread in the calling service was stuck waiting.
Circuit breakers are the distributed-systems equivalent of an electrical fuse: they detect abnormal current (errors or latency), trip open to stop the cascade, and periodically probe to see if the downstream has recovered. The pattern converts a hard failure in one service into a graceful degradation across the entire system. Every FAANG-scale platform runs this pattern on every single outbound network call — no exceptions. Today we wire it into our log pipeline so that a failing PostgreSQL node, a saturated Kafka broker, or a flapping Redis instance cannot bring down our ingestion throughput.
System Design Deep Dive
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
