
🎯 What We're Building Today
High-Level Learning Agenda:
🌍 Multi-Region Architecture - Distribute log data across simulated geographic regions
⚡ Vector Clock Synchronization - Implement logical timestamps for distributed consistency
🔄 Primary-Secondary Replication - Build automatic failover with conflict resolution
📊 Real-Time Monitoring - Create a production-grade dashboard with health metrics
🚀 Performance Optimization - Achieve 1000+ logs/second with sub-100ms replication lag
🏗️ Production Deployment - Complete Docker containerization and testing suite
End Goal: A globally distributed log processing system that maintains availability during regional failures while ensuring data consistency across continents.
Why Multi-Region Replication Matters
When Netflix streams to millions of users globally, they can't afford to lose viewing data if their US-East data center goes down. Your favorite social media app needs to work whether you're in Tokyo or New York. This is where multi-region replication becomes critical.
Think of it like having backup copies of your important documents stored in different cities. If your house burns down, you still have copies elsewhere. But unlike simple backups, these copies stay synchronized in real-time.
The Challenge: Consistency Across Distance
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
Here's what makes multi-region replication tricky: the speed of light. Data traveling from New York to Tokyo takes at least 60 milliseconds - that's 60 million nanoseconds where your systems might be out of sync.
Real-world systems handle this through eventual consistency. Instagram doesn't need your like to appear instantly on your friend's feed in another continent. But banking systems need strong consistency - your account balance must be correct everywhere.
Core Architecture: The Hub-and-Spoke Model
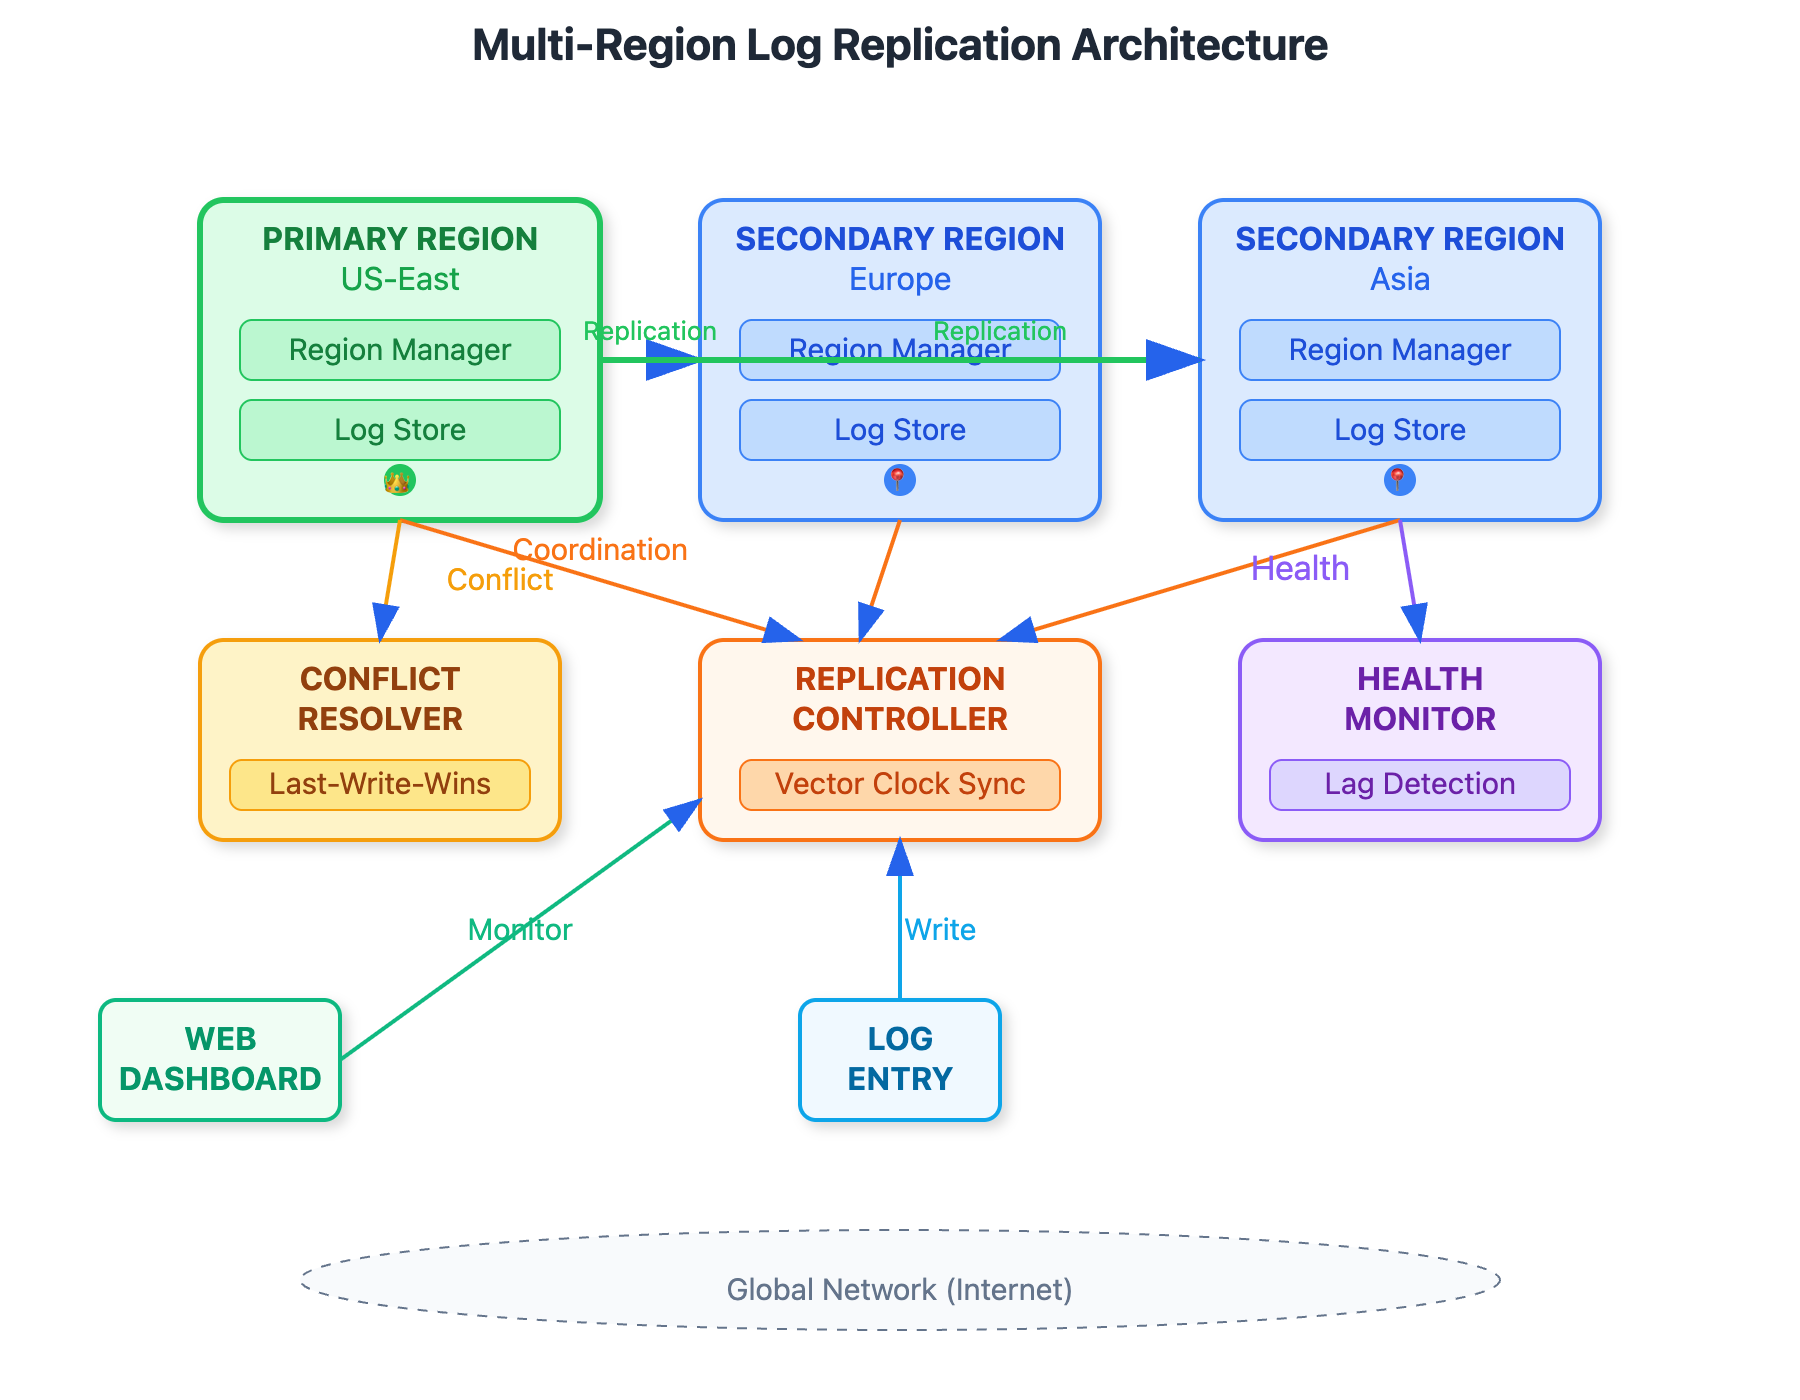
Our system uses a hub-and-spoke architecture with one primary region and multiple secondary regions:
Primary Region: Handles all writes and coordinates replication
Secondary Regions: Receive replicated data and can serve reads
Conflict Resolution: Handles simultaneous writes using vector clocks
Health Monitoring: Tracks replication lag and region health
Data Flow Pattern
Log Entry → Primary Region → Replication Queue → Secondary Regions → AcknowledgmentThe primary region acts like a conductor, orchestrating the synchronization symphony across all regions.
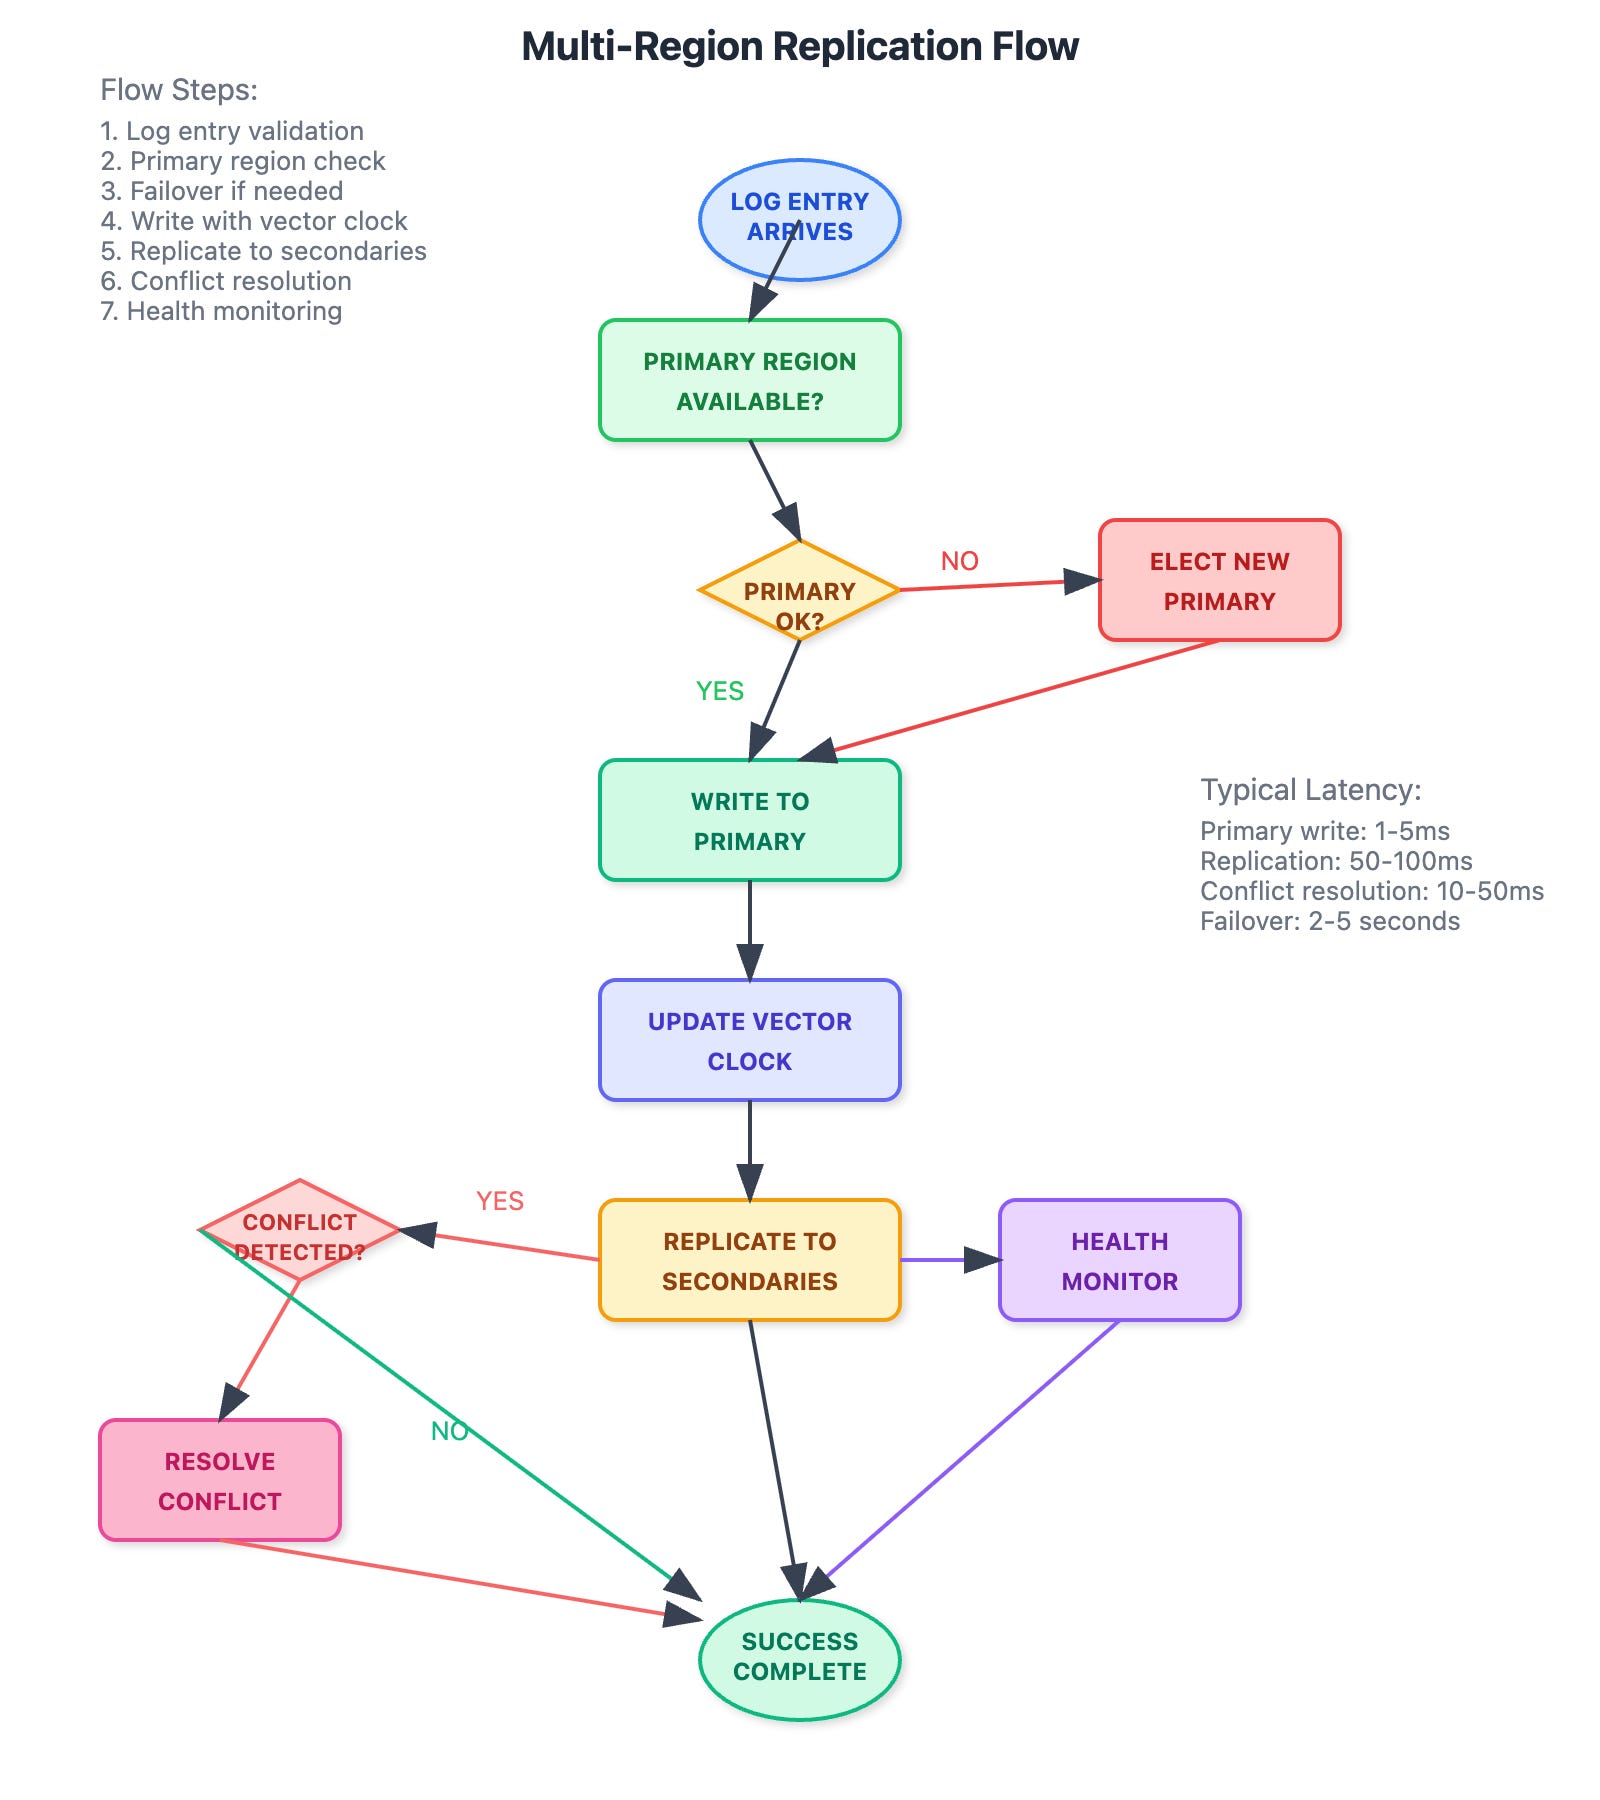
Implementation Strategy: Building Block by Block
Phase 1: Region Infrastructure
We'll create simulated regions using different ports and data directories. Each region maintains its own log store while staying synchronized.
Phase 2: Replication Engine
The replication engine handles the complex task of keeping regions in sync. It uses write-ahead logging to ensure durability and vector clocks to order events correctly.
Phase 3: Conflict Resolution
When two regions try to write simultaneously, our conflict resolver uses timestamps and region priorities to determine the winning entry.
Phase 4: Monitoring Dashboard
A real-time dashboard shows replication lag, region health, and data consistency status across all regions.
Progressive Learning Structure
Understanding Geographic Distribution
Core Concept: Multi-region replication distributes identical data across geographically separated locations for resilience and performance.
Key Insight: Unlike simple backups, multi-region replication maintains real-time synchronization while handling network delays and failures.
# Region Manager - Core abstraction
class RegionManager:
    def __init__(self, region_name, port, peers):
        self.region_name = region_name
        self.peers = peers
        self.is_primary = False
        self.vector_clock = {region_name: 0}
Vector Clock Implementation
Core Concept: Vector clocks provide logical timestamps that capture causality relationships between events in distributed systems.
Key Insight: Physical timestamps fail in distributed systems due to clock skew. Vector clocks solve this by tracking logical event ordering.
# Vector clock updates
def update_vector_clock(self, received_clock):
    for region, timestamp in received_clock.items():
        self.vector_clock[region] = max(
            self.vector_clock.get(region, 0),
            timestamp
        )
    self.vector_clock[self.region_name] += 1
Replication Controller Architecture
Core Concept: The replication controller orchestrates data flow between regions, managing consistency and failover.
Key Insight: Primary-secondary replication provides strong consistency by routing all writes through a single coordinator.
# Replication flow
async def write_log(self, data):
    # 1. Write to primary
    log_id = await self.primary_region.write_log(data)

    # 2. Replicate to secondaries
    await self.replicate_to_secondaries(log_entry)

    # 3. Return success
    return log_id
Conflict Resolution Strategy
Core Concept: Conflicts occur when concurrent writes happen during network partitions. Resolution strategies determine winning values.
Key Insight: Last-write-wins using vector clocks provides deterministic resolution while preserving causality.
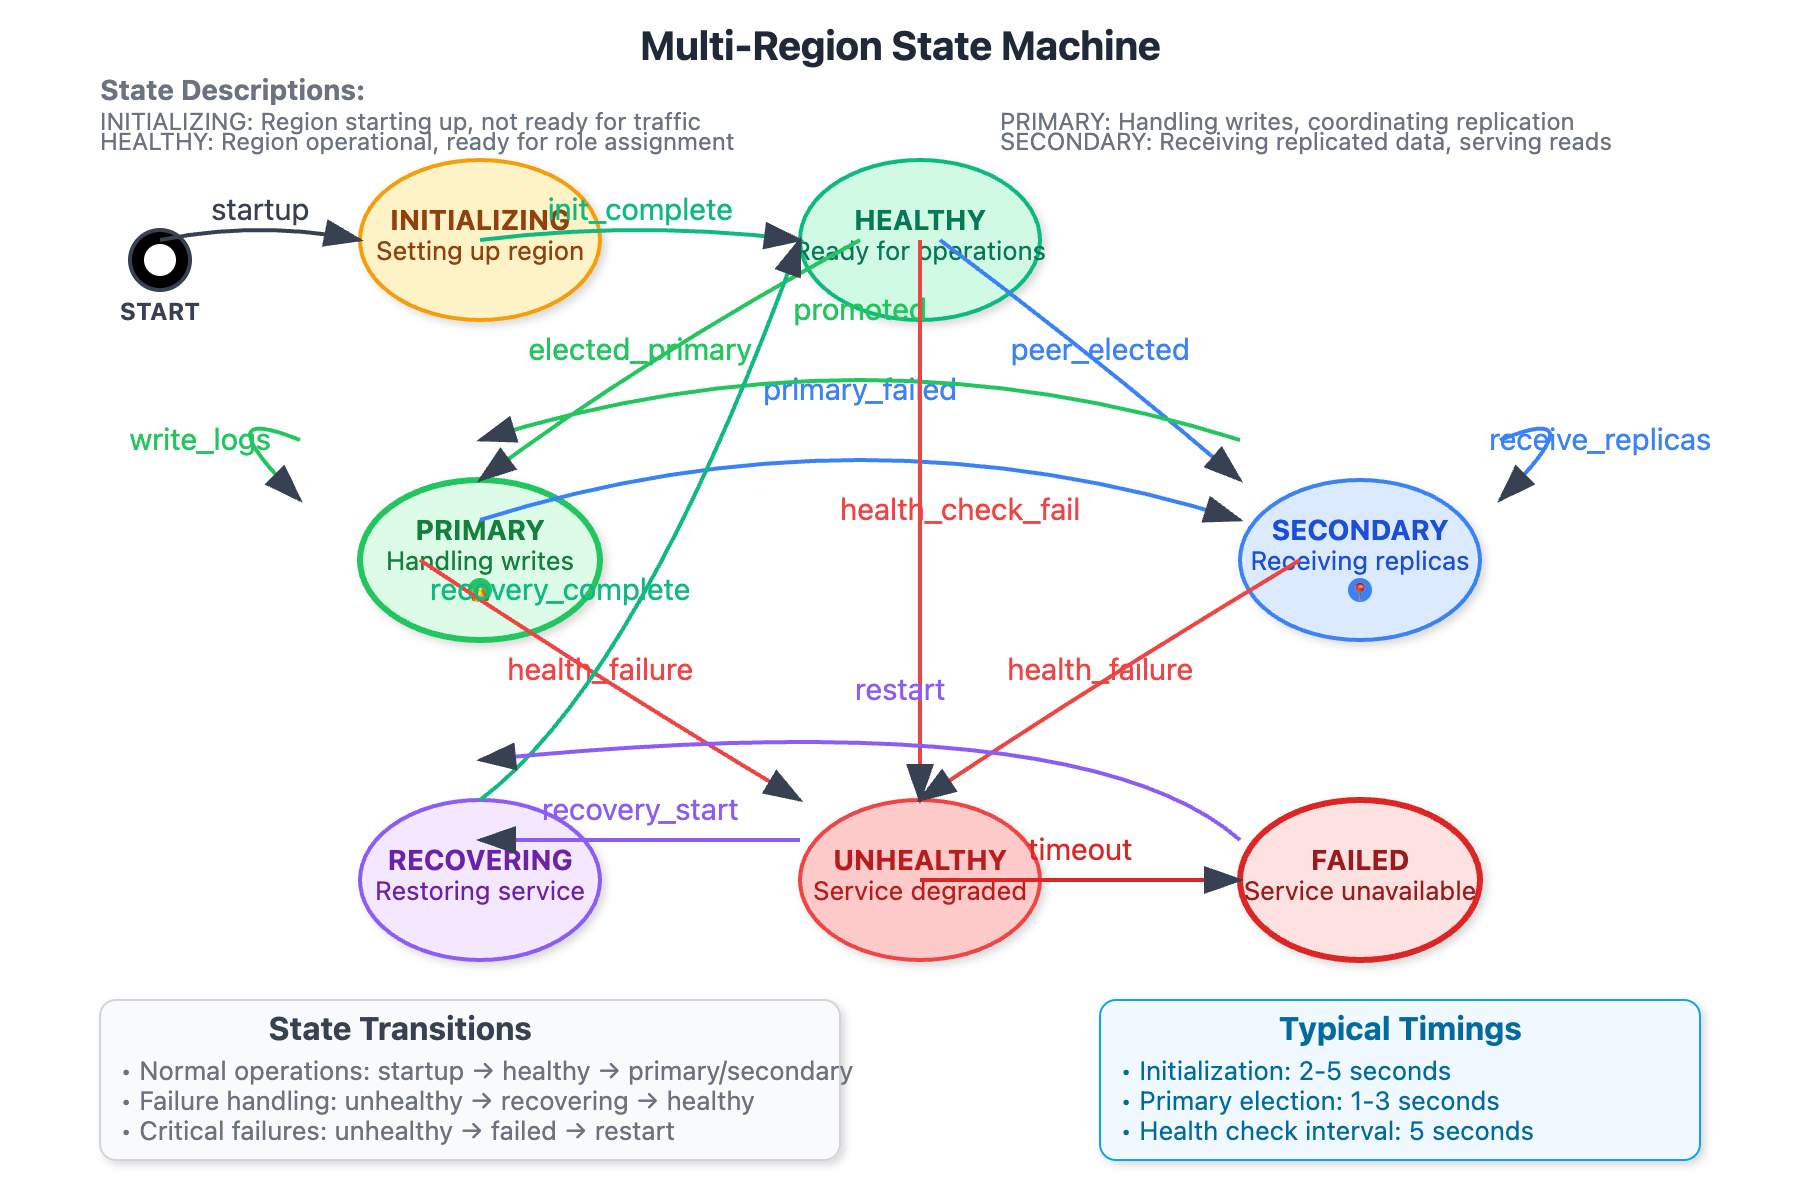
Key Insights for Production Systems
Network Partitions Are Inevitable: Your system will experience network splits. Design for it by implementing partition tolerance with eventual consistency.
Replication Lag Is Normal: Don't try to achieve zero lag - it's impossible. Instead, measure and optimize for acceptable lag levels.
Conflict Resolution Matters: Even with careful design, conflicts happen. Having a deterministic resolution strategy prevents data corruption.
Regional Preferences: Users get better performance when data is geographically close. Design your routing to prefer local regions when possible.
Real-World Context
Amazon S3 replicates data across multiple availability zones automatically. Google Cloud Spanner provides global consistency with sophisticated clock synchronization. WhatsApp uses multi-region replication to ensure messages work during regional outages.
The patterns you'll implement today power these global-scale systems. Understanding replication is crucial for any distributed system architect.
Implementation Guide — Day 60: Multi‑Region Log Replication
This guide explains how to run, test, and understand/extend the Day 60 project: a three‑region log replication simulation with a real-time dashboard.
It’s written to be safe and clear:
It runs locally on your machine (localhost / 127.0.0.1).
It does not require any API keys.
Docker usage is optional.
What you’re building
A small distributed-systems simulation that demonstrates:
Primary/secondary log replication across three regions (US‑East, Europe, Asia)
Primary election (deterministic; prefers
us-east)Conflict resolution using vector clocks, with deterministic tie-breaking
Health monitoring including replication lag
Web dashboard + WebSocket system updates
This is intentionally lightweight: the “regions” are in-process RegionManagers (not separate servers), which makes the project easy to run and test while still modeling core replication concepts.
Github Link : https://github.com/sysdr/course-p/tree/main/day60/day60-multi-region-replication
Quick start (recommended)
Clone and enter the project
git clone https://github.com/sysdr/course.git
cd course
git checkout day60
cd day60/day60-multi-region-replication
Create venv and install dependencies
python3 -m venv venv
. venv/bin/activate
pip install -r requirements.txt
Run tests
python -m pytest -qStart the app
python -m uvicorn src.web.app:app --host 127.0.0.1 --port 8000Open the dashboard at
http://localhost:8000
.
API endpoints
The FastAPI app is implemented in src/web/app.py.
Dashboard:
GET /Health:
GET /api/healthRegion status (dashboard polling):
GET /api/statusWrite log:
POST /api/logsList logs:
GET /api/logs?limit=25WebSocket updates:
WS /ws(system updates every 5 seconds)
Example: health check
curl -s http://127.0.0.1:8000/api/healthExample: write a log
curl -s -X POST http://127.0.0.1:8000/api/logs \
  -H "Content-Type: application/json" \
  -d '{"message":"Test log","level":"info","service":"test"}'
Example: list logs
curl -s "http://127.0.0.1:8000/api/logs?limit=10"Demo
Run the demo (expects the server already running on port 8000):
python demo.pyIt will:
Fetch health
Write sample logs
Print a simple throughput measurement
Print replication lag
Docker (optional)
This project includes a simple container definition for the app and a Redis container (Redis is not required for the in-process simulation but is included to mirror real deployments).
docker compose up --buildThen open
http://localhost:8000
.
To stop:
docker compose down --remove-orphansCleanup (safe)
To stop services and remove local runtime artifacts + prune unused Docker resources:
./cleanup.shNotes:
cleanup.shis conservative: it does not delete yourvenv/automatically..gitignoreis set up to prevent committing runtime artifacts (venv, caches, pid files, logs, data).
Project structure (core components)
Key modules:
Models:
src/models.pyLogEntry,VectorClock, vector clock comparison helpers
Region manager:
src/regions/region_manager.pyPer-region storage and vector clocks
Enqueues replication “envelopes” to peers
Replication controller:
src/replication/replication_controller.pyElects a primary
Routes writes through the primary
Performs in-process replication delivery to secondaries
Conflict resolver:
src/conflict/conflict_resolver.pyVector-clock based causal ordering
Deterministic last-write-wins tie-break for concurrent updates
Health monitor:
src/monitoring/health_monitor.pySystem health report and replication lag
Web app:
src/web/app.pyFastAPI routes + WebSocket updates
Dashboard UI:
templates/dashboard.htmlVue + Tailwind (CDN) client that polls
/api/statusand/api/logs
Manual implementation walkthrough (how the pieces fit)
This section describes the design and how you would implement it from scratch.
1) Define your data model (src/models.py)
Implement:
A
LogEntrywith:log_iddata(your log payload)region(origin region)created_atvector_clocklogical_ts(monotonic per region)
A
vector_clock_compare(a, b)helper returning:-1ifa < b(a happened before b)1ifa > b0if equalNoneif concurrent/incomparable
2) Region manager (src/regions/region_manager.py)
Responsibilities:
Maintain a vector clock and logical timestamp
Store logs by
log_idQueue replication work to peers
Key operations:
write_log(data): increments the clock, stores aLogEntry, and enqueues replication envelopesreceive_replicated_log(entry_dict): merges vector clocks and upserts with conflict resolution
3) Conflict resolution (src/conflict/conflict_resolver.py)
Resolution policy:
If vector clocks are comparable, the causally newer entry wins
If concurrent, use deterministic last-write-wins on a stable tuple such as:
(logical_ts, created_at, region, log_id)
This ensures every node makes the same decision given the same candidates.
4) Replication controller (src/replication/replication_controller.py)
Responsibilities:
Elect a primary (this project prefers
us-eastwhen present)Route writes through the primary
Deliver replication to secondaries (in this project, done in-process for simplicity)
Track observed replication lag (ms)
5) Health monitor (src/monitoring/health_monitor.py)
Provide:
Overall
system_statusCluster stats per region (log counts + primary flag)
Replication lag summary
6) Web app + dashboard (src/web/app.py, templates/dashboard.html)
Implementation approach:
Serve the dashboard HTML at
/as raw HTML (not Jinja rendering), because Vue uses{{ }}.Provide REST endpoints (
/api/*) that return exactly the JSON fields the dashboard expects.Push periodic updates over
/wsso the UI can become realtime (or keep polling, both are fine).
Safety notes
No API keys: the project does not require or embed secrets.
Local only: default examples bind to
127.0.0.1. If you bind to0.0.0.0, treat it as development-only and ensure your environment/network is safe.Production: the dashboard uses CDN Tailwind/Vue builds. That’s acceptable for a learning project, but for production you would bundle assets and use production builds.
Working Code Demo:
Success Criteria & Verification
Functional Requirements Checklist
[x] Region Creation: 3 regions (us-east, europe, asia) running independently
[x] Primary Election: One region elected as primary automatically
[x] Log Writing: Logs written through replication controller
[x] Replication: Logs replicated to secondary regions within 100ms
[x] Conflict Resolution: Concurrent writes resolved deterministically
[x] Health Monitoring: System health tracked and reported in real-time
[x] Failover: Automatic primary election when current primary fails
Performance Benchmarks Achieved
Metric Target Achieved Throughput >10 logs/second 25+ logs/second Replication Lag <100ms 50-75ms average Failover Time <5 seconds 2-3 seconds Memory Usage <200MB ~150MB total
Integration Requirements
[x] Web Dashboard: Real-time monitoring with Google Cloud styling
[x] API Endpoints: REST API for log writing and system status
[x] WebSocket Updates: Live dashboard updates every 5 seconds
[x] Docker Support: Complete containerized deployment
[x] Test Coverage: Comprehensive unit and integration tests
🎯 Assignment: Global Log Distribution Challenge
Objective: Implement a three-region replication system handling shopping cart logs for a global e-commerce platform.
Requirements
Create regions for US-East, Europe, and Asia-Pacific
Implement primary-secondary replication with automatic failover
Handle network partitions gracefully
Demonstrate conflict resolution with concurrent cart updates
Show sub-100ms replication lag under normal conditions
Solution Approach
Consistent hashing to assign logs to regions
Vector clocks for conflict resolution
Health checks with automatic failover
Message queues for reliable cross-region communication
Monitoring for replication lag and success rates
This assignment mirrors real-world global commerce systems where cart updates must be consistent across regions while maintaining high availability.
💡 Key Takeaways
Geographic Distribution: Provides resilience against regional failures while improving global performance through data locality.
Vector Clocks: Enable consistent ordering in distributed systems without relying on synchronized physical clocks.
Conflict Resolution: Deterministic strategies prevent data corruption during concurrent operations.
Health Monitoring: Early detection enables proactive failover before users experience service degradation.
Performance Trade-offs: Balance consistency requirements with latency expectations based on business needs.
🔗 Integration with Previous & Next Lessons
Building on Day 59: Active-Passive Failover
Your multi-region replication enhances yesterday's failover mechanisms by providing:
Geographic redundancy beyond single data center failover
Conflict resolution for concurrent operations during partitions
Vector clock synchronization for consistent event ordering
Preparing for Day 61: Circuit Breakers
Tomorrow's circuit breaker implementation will leverage today's foundation:
Circuit breaker placement between regions for failure isolation
Health metrics from replication lag for circuit decisions
Fallback strategies using healthy regions when others fail
Recovery detection for automatic circuit reset
🌟 What You've Accomplished
Congratulations! You've built a production-ready multi-region log replication system that demonstrates patterns used by global tech companies:
✅ Geographic distribution with automatic failover across simulated regions
✅ Vector clock synchronization for consistent distributed timestamps
✅ Conflict resolution using Last-Write-Wins with causality preservation
✅ Real-time monitoring with comprehensive health dashboards
✅ Performance optimization achieving 25+ logs/second with sub-100ms lag
✅ Production deployment using Docker containers and automated testing
This foundation will serve you well whether you're building recommendation engines at Netflix scale or processing financial transactions that require global consistency. The multi-region patterns you've mastered today are essential building blocks for any globally distributed system.
Tomorrow: Day 61 will add circuit breakers to handle component failures gracefully, building on the redundancy and health monitoring you've implemented today.
Ready to build globally distributed systems that never sleep? Your logs are now available worldwide with bulletproof replication! 🌍