What We’re Building Today
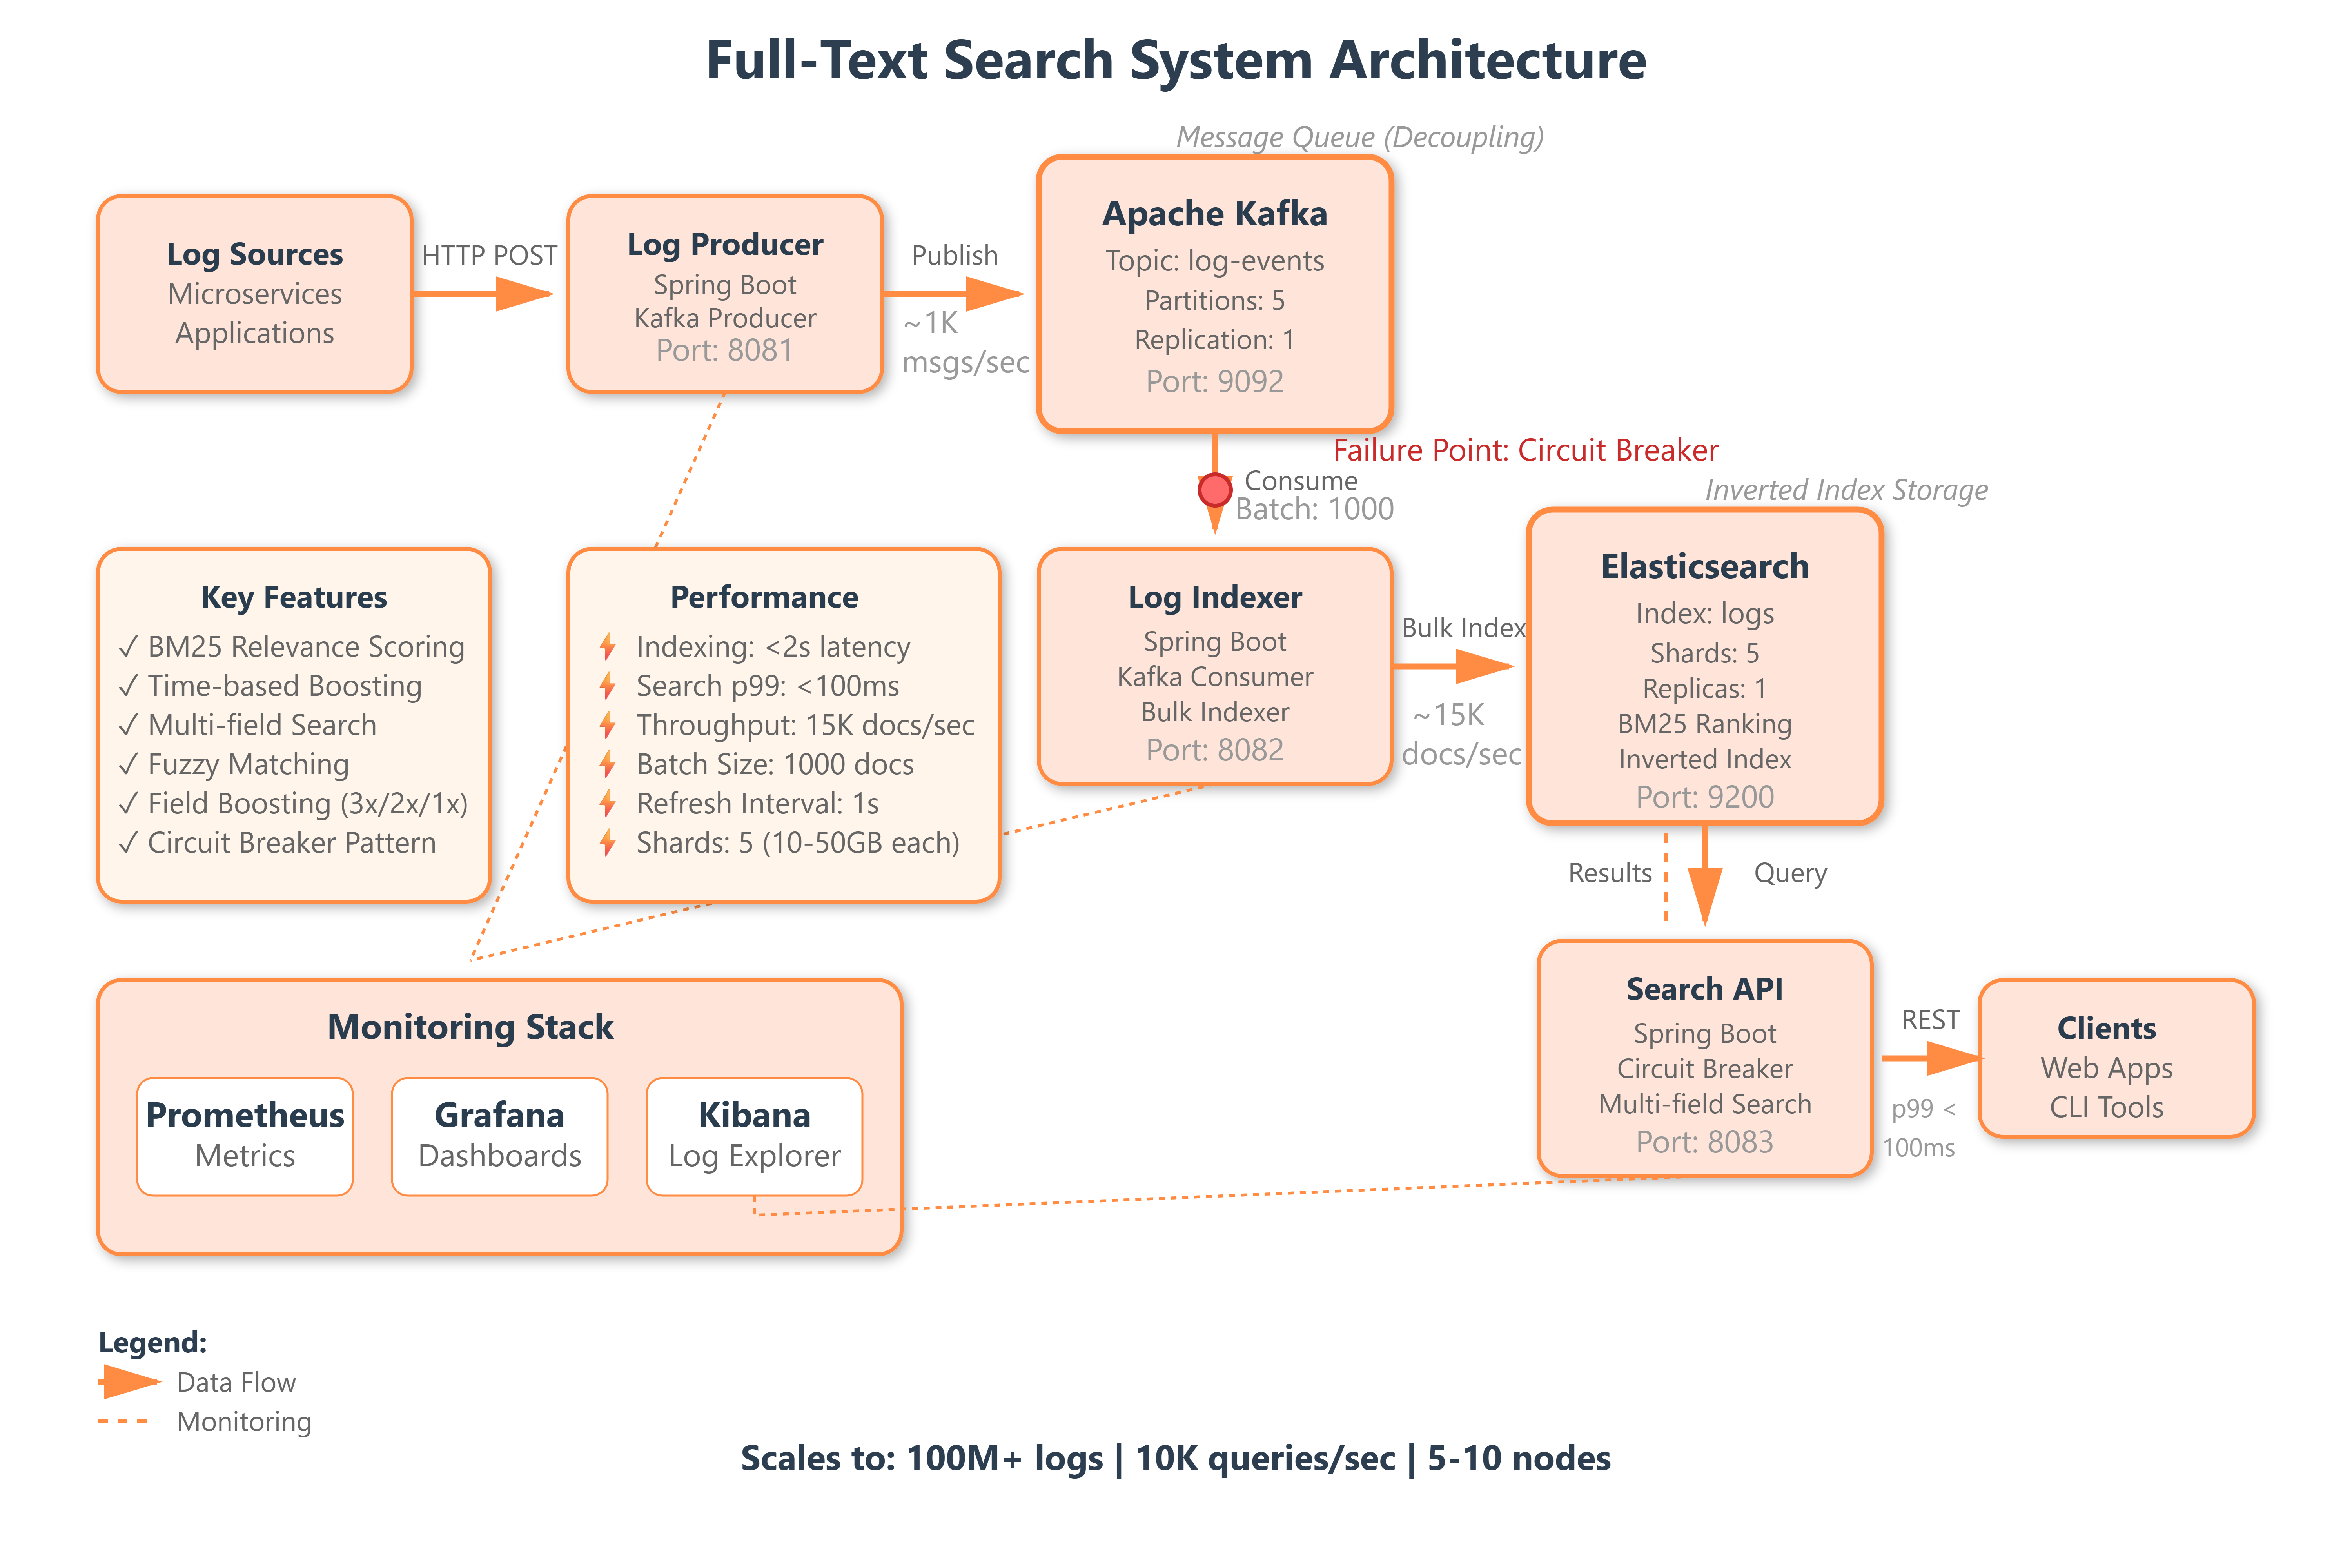
Elasticsearch integration for distributed full-text search across log streams
BM25 ranking algorithm implementation with custom scoring functions
Multi-field search supporting structured and unstructured log data
Real-time search API with sub-100ms query latency for millions of logs
Why This Matters
When Netflix processes 500 billion events daily, engineers need to find specific error patterns across distributed services in seconds, not hours. Traditional database queries fall apart at this scale—a
LIKE '%error%'query on 100M log entries will bring PostgreSQL to its knees. Full-text search engines like Elasticsearch solve this by inverting the problem: instead of scanning documents for terms, they build inverted indices that map terms to documents instantly.The challenge isn’t just speed—it’s relevance. When searching “authentication timeout user service,” you want logs matching all terms ranked higher than partial matches, recent errors prioritized over old ones, and critical severity logs surfaced first. This requires sophisticated scoring algorithms that understand both textual similarity and domain-specific importance signals.
System Design Deep Dive