Looking for Professional Growth ?
The difference between a "design interview" and a "production system" is massive. Close that gap today with the Hands on Distributed Log System Building course. Get 40% off for a limited time: https://sdcourse.substack.com/fbbab0d8
What We’re Building Today
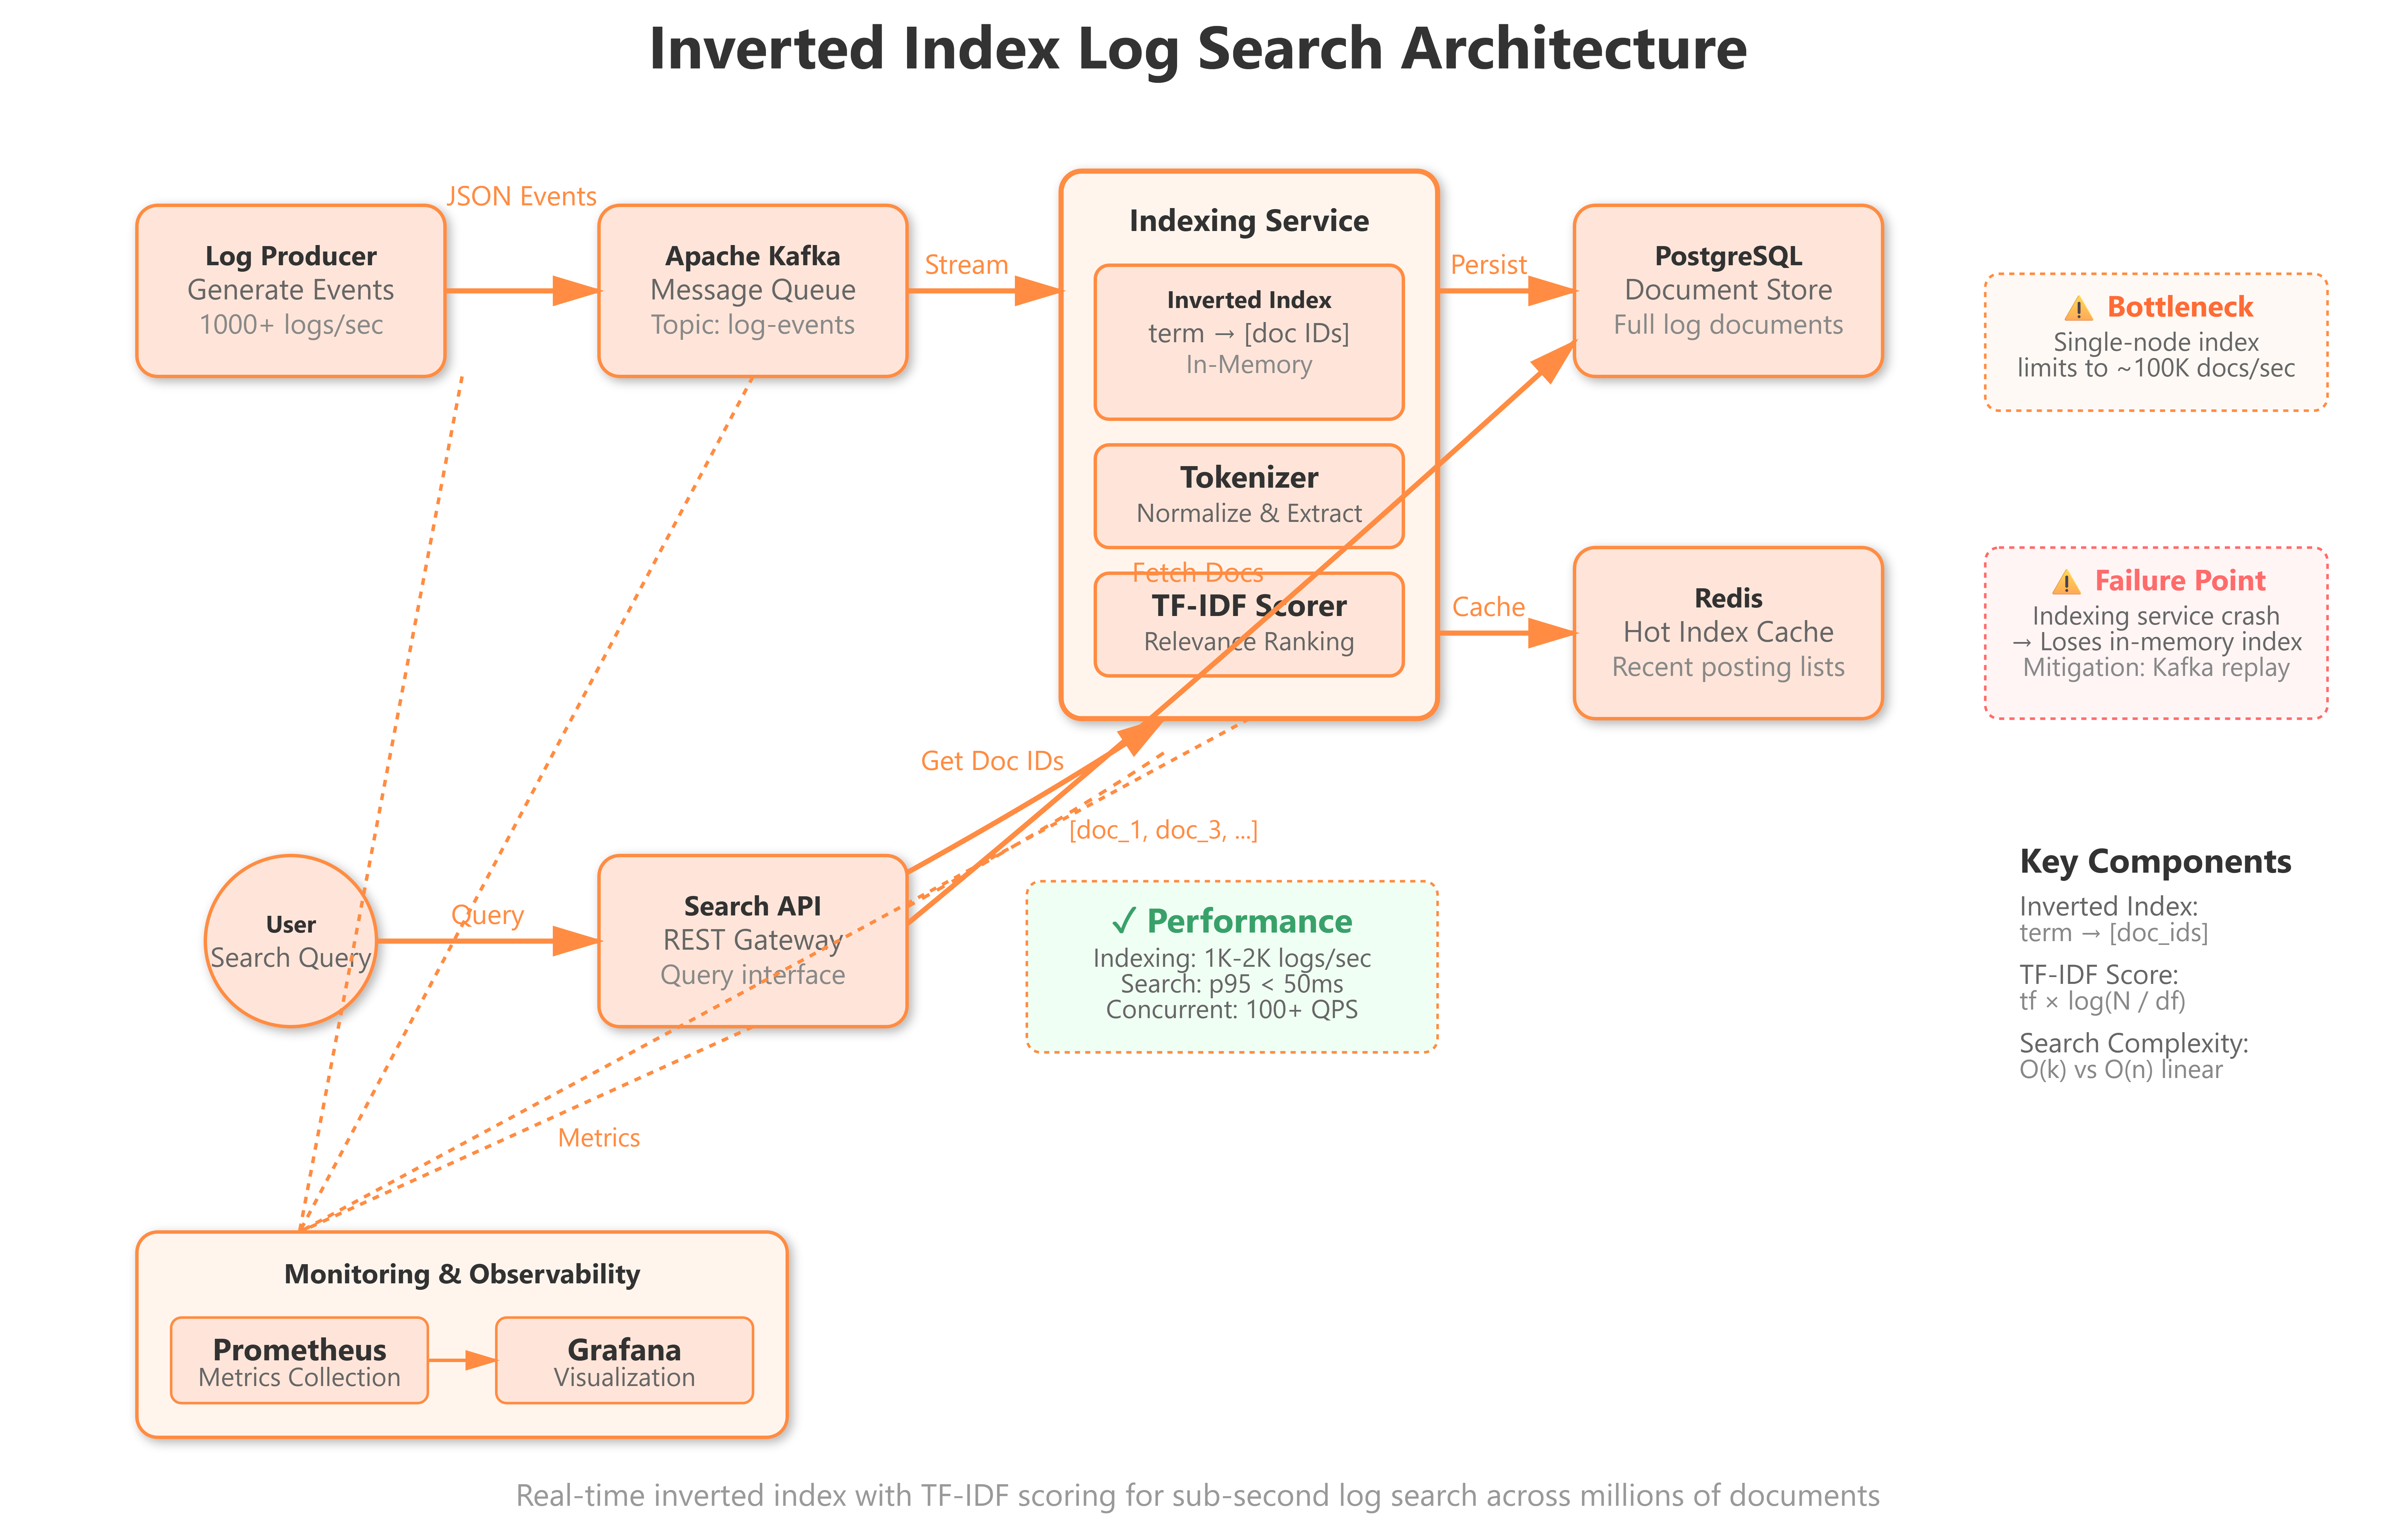
Real-time inverted index that tokenizes and indexes log messages as they arrive via Kafka
Search API with relevance scoring and ranked results for natural language queries
Index persistence layer using Redis for hot data and PostgreSQL for cold storage
Query processing engine supporting boolean operators and phrase matching
Why This Matters
Every major observability platform—Splunk, Datadog, Elastic—runs on inverted indices. When you search “ERROR user authentication failed” across billions of log entries and get results in milliseconds, you’re querying an inverted index. This data structure powers everything from application monitoring to security incident response.
Without inverted indices, log search would require scanning every log entry linearly—O(n) complexity that becomes impossible at scale. An inverted index transforms this into O(k) lookups where k is the number of query terms, enabling sub-second searches across terabytes of logs. Understanding inverted indices is fundamental to building search infrastructure that scales from thousands to trillions of documents.
Today’s implementation bridges the gap between local prototypes and production search engines, showing how the same architectural patterns scale from single-node deployments to distributed clusters processing petabytes daily.
System Design Deep Dive