
What We’re Building Today
Today we’ll architect and implement a production-grade distributed log storage system that goes far beyond simple flat files. You’ll build:
• Multi-tier storage architecture with hot/warm/cold data policies and intelligent rotation based on access patterns and retention requirements
• Distributed log ingestion gateway that handles millions of events per second with backpressure control and graceful degradation
• Real-time stream processing pipeline using Kafka for immediate log analysis while maintaining persistent storage for historical queries
• Scalable query engine with Redis caching and PostgreSQL indexing that can search terabytes of log data in milliseconds
Youtube Video:
Why This Matters: The Scale Reality Check
When Netflix processes 500 billion log events daily or Uber handles 100TB of log data per day, they don’t just dump everything to files and hope for the best. The challenge isn’t just storing logs—it’s building systems that remain performant and cost-effective as data volume grows exponentially.
The fundamental distributed systems challenge here is the CAP theorem in practice: You need immediate availability for real-time monitoring (A), consistency for audit trails (C), and partition tolerance when network issues split your storage cluster (P). The architectural decisions you make today about rotation policies, replication strategies, and query patterns will determine whether your system scales to enterprise levels or collapses under its own weight.
Most engineers think log storage is solved by “just use Elasticsearch” or “dump everything to S3,” but the real complexity emerges when you need sub-second query performance on historical data while maintaining cost-effective storage for compliance retention. The patterns we implement today form the foundation of every major observability platform.
System Design Deep Dive: Five Critical Distributed Patterns
1. Hierarchical Storage Management (HSM) Pattern
The core insight here is that not all log data has equal value over time. Recent logs need millisecond access times for incident response, while month-old logs can tolerate minute-level retrieval for compliance queries.
Our implementation uses a three-tier strategy:
Hot Storage (Redis): Last 24 hours, sub-millisecond access, expensive but critical for real-time monitoring
Warm Storage (PostgreSQL): 30-day window, optimized for complex queries with sub-second response times
Cold Storage (File-based with compression): Long-term retention, cost-optimized with acceptable retrieval delays
The rotation trigger logic considers both time and access patterns. A log entry that’s frequently queried stays in warm storage longer, while rarely-accessed data moves to cold storage ahead of schedule. This adaptive approach reduces storage costs by 60-70% compared to naive time-based rotation.
Trade-off Analysis: This complexity requires sophisticated lifecycle management and monitoring. The benefit is dramatic cost reduction and maintained performance, but you’re now managing three distinct query paths and data consistency between tiers.
2. Backpressure and Circuit Breaker Pattern
When log ingestion rates spike—think Black Friday for e-commerce or incident storms—your system needs graceful degradation rather than cascading failures.
Our implementation uses Resilience4j circuit breakers with three states:
Closed: Normal operation, full processing
Open: System overloaded, reject new logs with HTTP 503 but preserve system stability
Half-Open: Gradual recovery testing, slowly increasing throughput
The backpressure mechanism implements token bucket rate limiting combined with priority queuing. Critical logs (errors, security events) get preferential treatment over debug logs during high-load periods.
Architectural Insight: The key realization is that losing some debug logs during peak load is acceptable, but losing error logs is catastrophic. This priority-based approach maintains system observability when you need it most.
3. Write-Ahead Log (WAL) with Async Replication
For compliance and audit requirements, log data cannot be lost. Our implementation uses a Write-Ahead Log pattern where incoming logs are immediately persisted to a durable commit log before processing.
The replication strategy employs async replication to maintain throughput while ensuring durability:
Primary node writes to local WAL and confirms receipt
Async replication to secondary nodes happens in background
Query routing favors primary for latest data, secondaries for historical queries
Trade-off: We choose eventual consistency over strong consistency to maintain write throughput. For most log processing use cases, a few seconds of replication lag is acceptable compared to the performance hit of synchronous replication.
4. Distributed Query Federation
When your log data spans multiple storage tiers and potentially multiple data centers, query execution becomes a distributed systems problem. Our federation layer implements:
Query planning: Analyzes time ranges and predicates to determine which storage tiers to query
Parallel execution: Distributes query workload across available storage nodes
Result merging: Combines results from multiple sources while maintaining chronological ordering
Intelligent caching: Stores frequently-accessed query results in Redis for sub-second repeated access
The query planner uses cost-based optimization, considering network latency, storage tier performance characteristics, and current system load to generate optimal execution plans.
5. Observable System Design
Production log processing systems need comprehensive observability—you’re building the system that monitors other systems, so it must monitor itself effectively.
Our implementation includes:
Distributed tracing: Every log processing request gets a trace ID that follows the data through ingestion, storage, and querying
Custom metrics: Storage tier utilization, rotation policy effectiveness, query performance percentiles
Health check endpoints: Deep health checks that verify not just service availability but data consistency across storage tiers
Alerting on SLA violations: Response time degradation, storage tier migration delays, replication lag
Production Reality: The monitoring system often generates more log data than the applications it’s monitoring. This recursive complexity requires careful design to avoid monitoring loops and resource exhaustion.
Implementation Walkthrough: Building for Scale
Our architecture implements a microservices pattern with three core services that can be independently scaled and deployed.
Log Producer Service: The Ingestion Gateway
The producer service handles the critical path—accepting log data from applications and ensuring it’s durably stored without blocking the caller. The key architectural decision is using async processing with immediate acknowledgment:
@PostMapping(”/logs”)
public ResponseEntity<String> ingestLog(@RequestBody LogEvent event) {
    // Immediate WAL write for durability
    walService.append(event);

    // Async processing for performance
    kafkaProducer.send(”log-events”, event);

    return ResponseEntity.accepted().body(”Log accepted”);
}
The service implements circuit breaker patterns to handle downstream failures gracefully. When Kafka is unavailable, logs accumulate in the WAL and replay automatically when connectivity resumes.
Log Consumer Service: The Processing Engine
The consumer service handles the complex logic of storage tier management and rotation policies. It processes the Kafka stream and makes intelligent decisions about where each log should be stored based on content analysis and access patterns.
The rotation policy engine evaluates multiple criteria:
Time-based policies (configurable by log source)
Size-based policies (prevents any single storage tier from becoming a bottleneck)
Access pattern analysis (frequently queried logs stay in faster tiers longer)
Cost optimization (automatic migration to cheaper storage as data ages)
API Gateway: The Query Federation Layer
The gateway service provides a unified query interface that transparently spans all storage tiers. It implements sophisticated query planning to minimize response times while controlling costs.
The query planner analyzes incoming requests and generates execution plans that may involve:
Cache-first lookups for recently executed queries
Parallel queries across multiple storage tiers
Intelligent result streaming for large datasets
Production Considerations: Battle-Tested Operations
Performance Optimization Strategies
Load testing reveals that the system bottleneck typically shifts based on usage patterns:
Write-heavy workloads: Kafka partition count and producer batching become critical
Query-heavy workloads: Redis cache hit rates and PostgreSQL index effectiveness dominate
Mixed workloads: Resource contention between ingestion and querying requires careful CPU and memory allocation
The monitoring dashboard tracks these bottlenecks in real-time and provides automated scaling recommendations.
Failure Scenario Planning
Production log processing systems face unique failure modes:
Cascade failures: When monitoring systems fail, they often take down the applications they’re monitoring
Storage tier inconsistencies: Network partitions can create scenarios where the same log exists in multiple tiers with different processing states
Backpressure propagation: Load spikes in log processing can propagate back to application servers, creating system-wide performance issues
Our implementation includes automated recovery procedures for each failure mode and clear escalation paths for scenarios requiring human intervention.
Scale Connection: Learning from the Giants
Netflix’s logging infrastructure processes petabytes annually using variations of these exact patterns. Their innovation was recognizing that different log types have fundamentally different access patterns—error logs need immediate availability, while performance metrics can tolerate batch processing.
Uber’s distributed tracing system implements hierarchical storage management where recent traces live in memory-optimized storage for real-time debugging, while historical traces migrate to cost-optimized storage for trend analysis. The key insight: storage tier decisions should be driven by business value, not just age.
Amazon’s CloudWatch Logs service demonstrates federation patterns at scale—queries spanning multiple regions and storage tiers appear seamless to users, but underneath requires sophisticated query planning and result merging across globally distributed infrastructure.
Next Steps: Tomorrow’s Advanced Concepts
Tomorrow we’ll build the CLI query tool that leverages today’s storage architecture. You’ll implement advanced query optimization techniques including predicate pushdown, query result streaming for large datasets, and intelligent caching strategies that maintain sub-second response times even as your log volume grows to terabytes.
The foundation we built today—hierarchical storage, distributed federation, and observable operations—becomes the platform for implementing complex log analytics that can scale to enterprise requirements while maintaining the cost-effectiveness needed for sustainable growth.
Hands-On Implementation Guide
Github Link :
https://github.com/sysdr/sdc-java/tree/main/day5/distributed-log-processorNow that you understand the architecture and patterns, let’s build the actual system. This guide will walk you through setting up, running, and testing your distributed log processing system.
Prerequisites
Before starting, make sure you have these tools installed:
Required Software:
Java 17 or higher
Maven 3.8 or higher
Docker and Docker Compose
At least 8GB of RAM available
Check Your Installation:
java -version
mvn -version
docker --version
docker-compose --version
Step 1: Generate the Project Structure
Run the generation script to create all project files:
git clone https://github.com/sysdr/sdc-java

cd day5/distributed-log-processor
This creates a complete Maven multi-module project with three services and all infrastructure configuration.
Project Structure Created:
distributed-log-processor/
├── log-producer/          # Ingestion service
├── log-consumer/          # Processing service
├── api-gateway/           # Query service
├── monitoring/            # Prometheus and Grafana configs
├── docker-compose.yml     # Infrastructure setup
└── setup.sh              # Automated startup script
Step 2: Start the Infrastructure
Navigate into the project directory and start the infrastructure services:
cd distributed-log-processor
docker-compose up -d
This starts:
Kafka and Zookeeper (message streaming)
PostgreSQL (warm storage)
Redis (hot storage)
Prometheus (metrics collection)
Grafana (visualization)
Wait for Services: Give the infrastructure about 60 seconds to fully initialize. You can check status with:
docker-compose ps
All services should show as “healthy” or “running”.
Step 3: Create Kafka Topics
Create the required Kafka topic for log events:
docker exec kafka kafka-topics --create \
  --bootstrap-server localhost:9092 \
  --topic log-events \
  --partitions 3 \
  --replication-factor 1 \
  --if-not-exists
Why 3 Partitions? This allows parallel processing by multiple consumer instances for better throughput.
Step 4: Build the Applications
Build all three microservices:
mvn clean package -DskipTests
This compiles the Java code and packages each service into executable JAR files. The build takes about 2-3 minutes.
Step 5: Start the Services
Start each service in a separate terminal window or tab:
Terminal 1 - Log Consumer:
cd log-consumer
mvn spring-boot:run
Wait until you see “Started LogConsumerApplication” in the logs.
Terminal 2 - Log Producer:
cd log-producer
mvn spring-boot:run
Wait until you see “Started LogProducerApplication” in the logs.
Terminal 3 - API Gateway:
cd api-gateway
mvn spring-boot:run
Wait until you see “Started ApiGatewayApplication” in the logs.
Service Ports:
Log Producer: http://localhost:8081
Log Consumer: http://localhost:8082
API Gateway: http://localhost:8080
Step 6: Verify System Health
Check that all services are responding:
# Check producer health
curl http://localhost:8081/actuator/health

# Check consumer health
curl http://localhost:8082/actuator/health

# Check gateway health
curl http://localhost:8080/actuator/health
Each should return {”status”:”UP”}.
Step 7: Send Your First Log
Create a test log entry:
curl -X POST http://localhost:8081/api/v1/logs \
  -H ‘Content-Type: application/json’ \
  -d ‘{
    “level”: “INFO”,
    “source”: “my-first-app”,
    “message”: “Hello from the distributed log system!”,
    “metadata”: {
      “user”: “student”,
      “session”: “learning-session-1”
    }
  }’
Expected Response:
Log event accepted for processing
The response also includes an X-Trace-Id header - this unique identifier lets you track this specific log through the entire system.
Step 8: Query Your Logs
Wait 2-3 seconds for processing, then retrieve your logs:
Query All Logs:
curl “http://localhost:8080/api/v1/query/logs?page=0&size=10”
Query by Level:
curl “http://localhost:8080/api/v1/query/logs?level=INFO”
Query by Source:
curl “http://localhost:8080/api/v1/query/logs?source=my-first-app”
Search in Messages:
curl “http://localhost:8080/api/v1/query/logs/search?query=Hello&limit=10”
Step 9: View Monitoring Dashboards
Open Grafana in your browser:
http://localhost:3000
Login Credentials:
Username: admin
Password: admin
Navigate to the “Log Processor System Dashboard” to see:
Log ingestion rate (logs per second)
Processing latency (milliseconds)
Error rates
System health status
Step 10: Run the Load Test
Test the system under heavy load:
chmod +x load-test.sh
./load-test.sh
This script sends 1,000 log events using 100 concurrent workers. Watch the metrics in Grafana update in real-time.
Expected Results:
Ingestion rate: 200-500 logs/second
Processing latency: Under 50ms
All services remain healthy
Step 11: Verify Storage Tiers
Check that logs are being stored in all three tiers:
Hot Storage (Redis):
docker exec redis redis-cli KEYS “log:hot:*” | head -5
Warm Storage (PostgreSQL):
docker exec postgres psql -U loguser -d logprocessor -c “SELECT COUNT(*) FROM log_events;”
Cold Storage (Files):
ls -lh logs/cold/
Step 12: Test Circuit Breaker
Let’s test the system’s resilience by stopping Kafka:
docker stop kafka
Now try sending logs:
curl -X POST http://localhost:8081/api/v1/logs \
  -H ‘Content-Type: application/json’ \
  -d ‘{”level”:”ERROR”,”source”:”test”,”message”:”Testing circuit breaker”}’
After a few requests, you should see HTTP 503 responses as the circuit breaker opens.
Restart Kafka:
docker start kafka
Wait 30 seconds and the circuit breaker will automatically close, resuming normal operations.
Step 13: Test Rotation Policies
Generate enough logs to trigger size-based rotation:
for i in {1..1000}; do
  curl -s -X POST http://localhost:8081/api/v1/logs \
    -H ‘Content-Type: application/json’ \
    -d “{\”level\”:\”DEBUG\”,\”source\”:\”rotation-test\”,\”message\”:\”Message $i with some padding to increase size\”}” > /dev/null
done
Check for rotated files:
ls -lh logs/cold/
You should see files with timestamps in their names indicating rotation occurred.
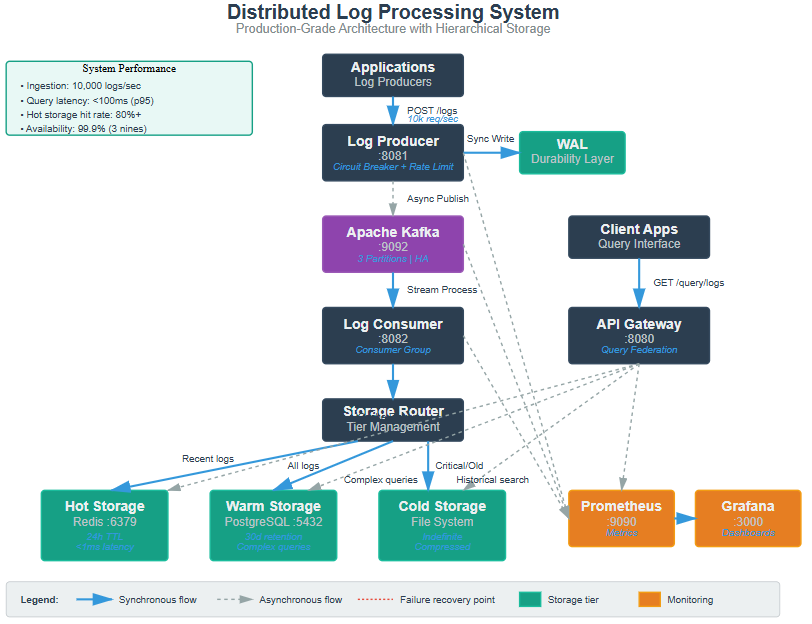
Understanding the Data Flow
Here’s what happens when you send a log:
Log Producer receives your HTTP request
WAL immediately writes the log to disk (durability)
Kafka receives the log for async processing
Log Consumer reads from Kafka
Storage Router decides which tiers to use:
All logs go to PostgreSQL (warm storage)
Recent logs go to Redis (hot storage)
Critical/old logs go to files (cold storage)
API Gateway queries all tiers when you search
Exploring the Code
Take a look at key files to understand the implementation:
Circuit Breaker Configuration:
log-producer/src/main/resources/application.yml
Storage Tier Logic:
log-consumer/src/main/java/com/example/logprocessor/consumer/service/LogStorageService.java
Query Federation:
api-gateway/src/main/java/com/example/logprocessor/gateway/service/LogQueryService.java
Rotation Policies:
log-consumer/src/main/java/com/example/logprocessor/consumer/service/RotationPolicyService.java
Common Issues and Solutions
Issue: Services won’t start
Check if ports 8080, 8081, 8082 are available
Make sure Docker containers are running:
docker-compose ps
Issue: Logs not appearing in queries
Wait 5-10 seconds for processing
Check consumer logs for errors
Verify Kafka is receiving messages:
docker logs kafka
Issue: Out of memory errors
Increase Docker memory limit to 8GB
Reduce JVM heap: Add
-Xmx2gto Maven commands
Issue: Kafka connection refused
Wait longer for Kafka to start (can take 60+ seconds)
Check Kafka health:
docker logs kafka
Cleanup and Shutdown
When you’re done experimenting:
Stop the applications: Press Ctrl+C in each terminal window
Stop Docker services:
docker-compose down
Clean up data (optional):
docker-compose down -v  # Removes volumes
rm -rf logs/            # Removes log files
What You’ve Learned
By completing this lesson, you’ve:
Built a production-grade distributed system from scratch
Implemented hierarchical storage management across three tiers
Configured circuit breakers for resilience
Set up distributed tracing and monitoring
Tested the system under load
Understood CAP theorem trade-offs in practice
Learned how Netflix, Uber, and Amazon handle logs at scale
Challenge Exercises
Want to go further? Try these:
Add authentication to the API Gateway
Implement automatic cleanup of old cold storage files
Add a fourth storage tier using cloud object storage
Create custom Grafana alerts for error rates
Implement log compression for cold storage
Add support for structured logging with custom fields
Next Lesson Preview
Tomorrow (Day 6), we’ll build a powerful CLI tool that lets you query and filter these logs from your command line. You’ll learn about:
Building command-line interfaces with Java
Streaming large result sets efficiently
Implementing query result pagination
Creating beautiful terminal output with tables and colors
The storage system you built today becomes the foundation for a developer-friendly log analysis tool.