
Stop Drawing Boxes. Start Building Systems. Subscribe Now
The gap between a “system design interview” and a “production system” is massive. This newsletter exists to bridge that gap.
When you join any organisation, no one is going to teach you how system is design or built. Fun part developers rarely document everything. you need to dig through to understand the system. I created this course because I believe the best way to learn distributed systems is by building them. We don’t just talk about the CAP theorem; we look at how it dictates our database choices. We don’t just mention “latency”; we measure it. Subscribe
What We’re Building Today
Today we implement sliding window aggregations for real-time trend detection in distributed log processing systems:
Hopping windows with configurable slide intervals for continuous metric updates
Multi-granularity trend analysis tracking 1-minute, 5-minute, and 15-minute moving averages
State-efficient window management using Kafka Streams’ optimized windowing primitives
Interactive query API serving real-time trend data with sub-10ms latency
Production monitoring tracking window lag, state store size, and processing throughput
Why This Matters
Sliding windows solve a critical problem in real-time analytics: detecting trends as they happen. Unlike tumbling windows that update in discrete jumps, sliding windows provide continuous visibility into recent behavior patterns. When Netflix detects video quality degradation, they need second-by-second moving averages—not 5-minute buckets that hide critical spikes. When Uber calculates surge pricing, they track the velocity of ride requests using overlapping windows to smooth out noise while remaining responsive to demand shifts.
The fundamental challenge is maintaining thousands of overlapping windows efficiently. A naive implementation storing every window independently would consume massive memory and CPU. Production systems leverage specialized data structures and time-based compaction strategies to maintain window state efficiently while serving low-latency queries.
System Design Deep Dive
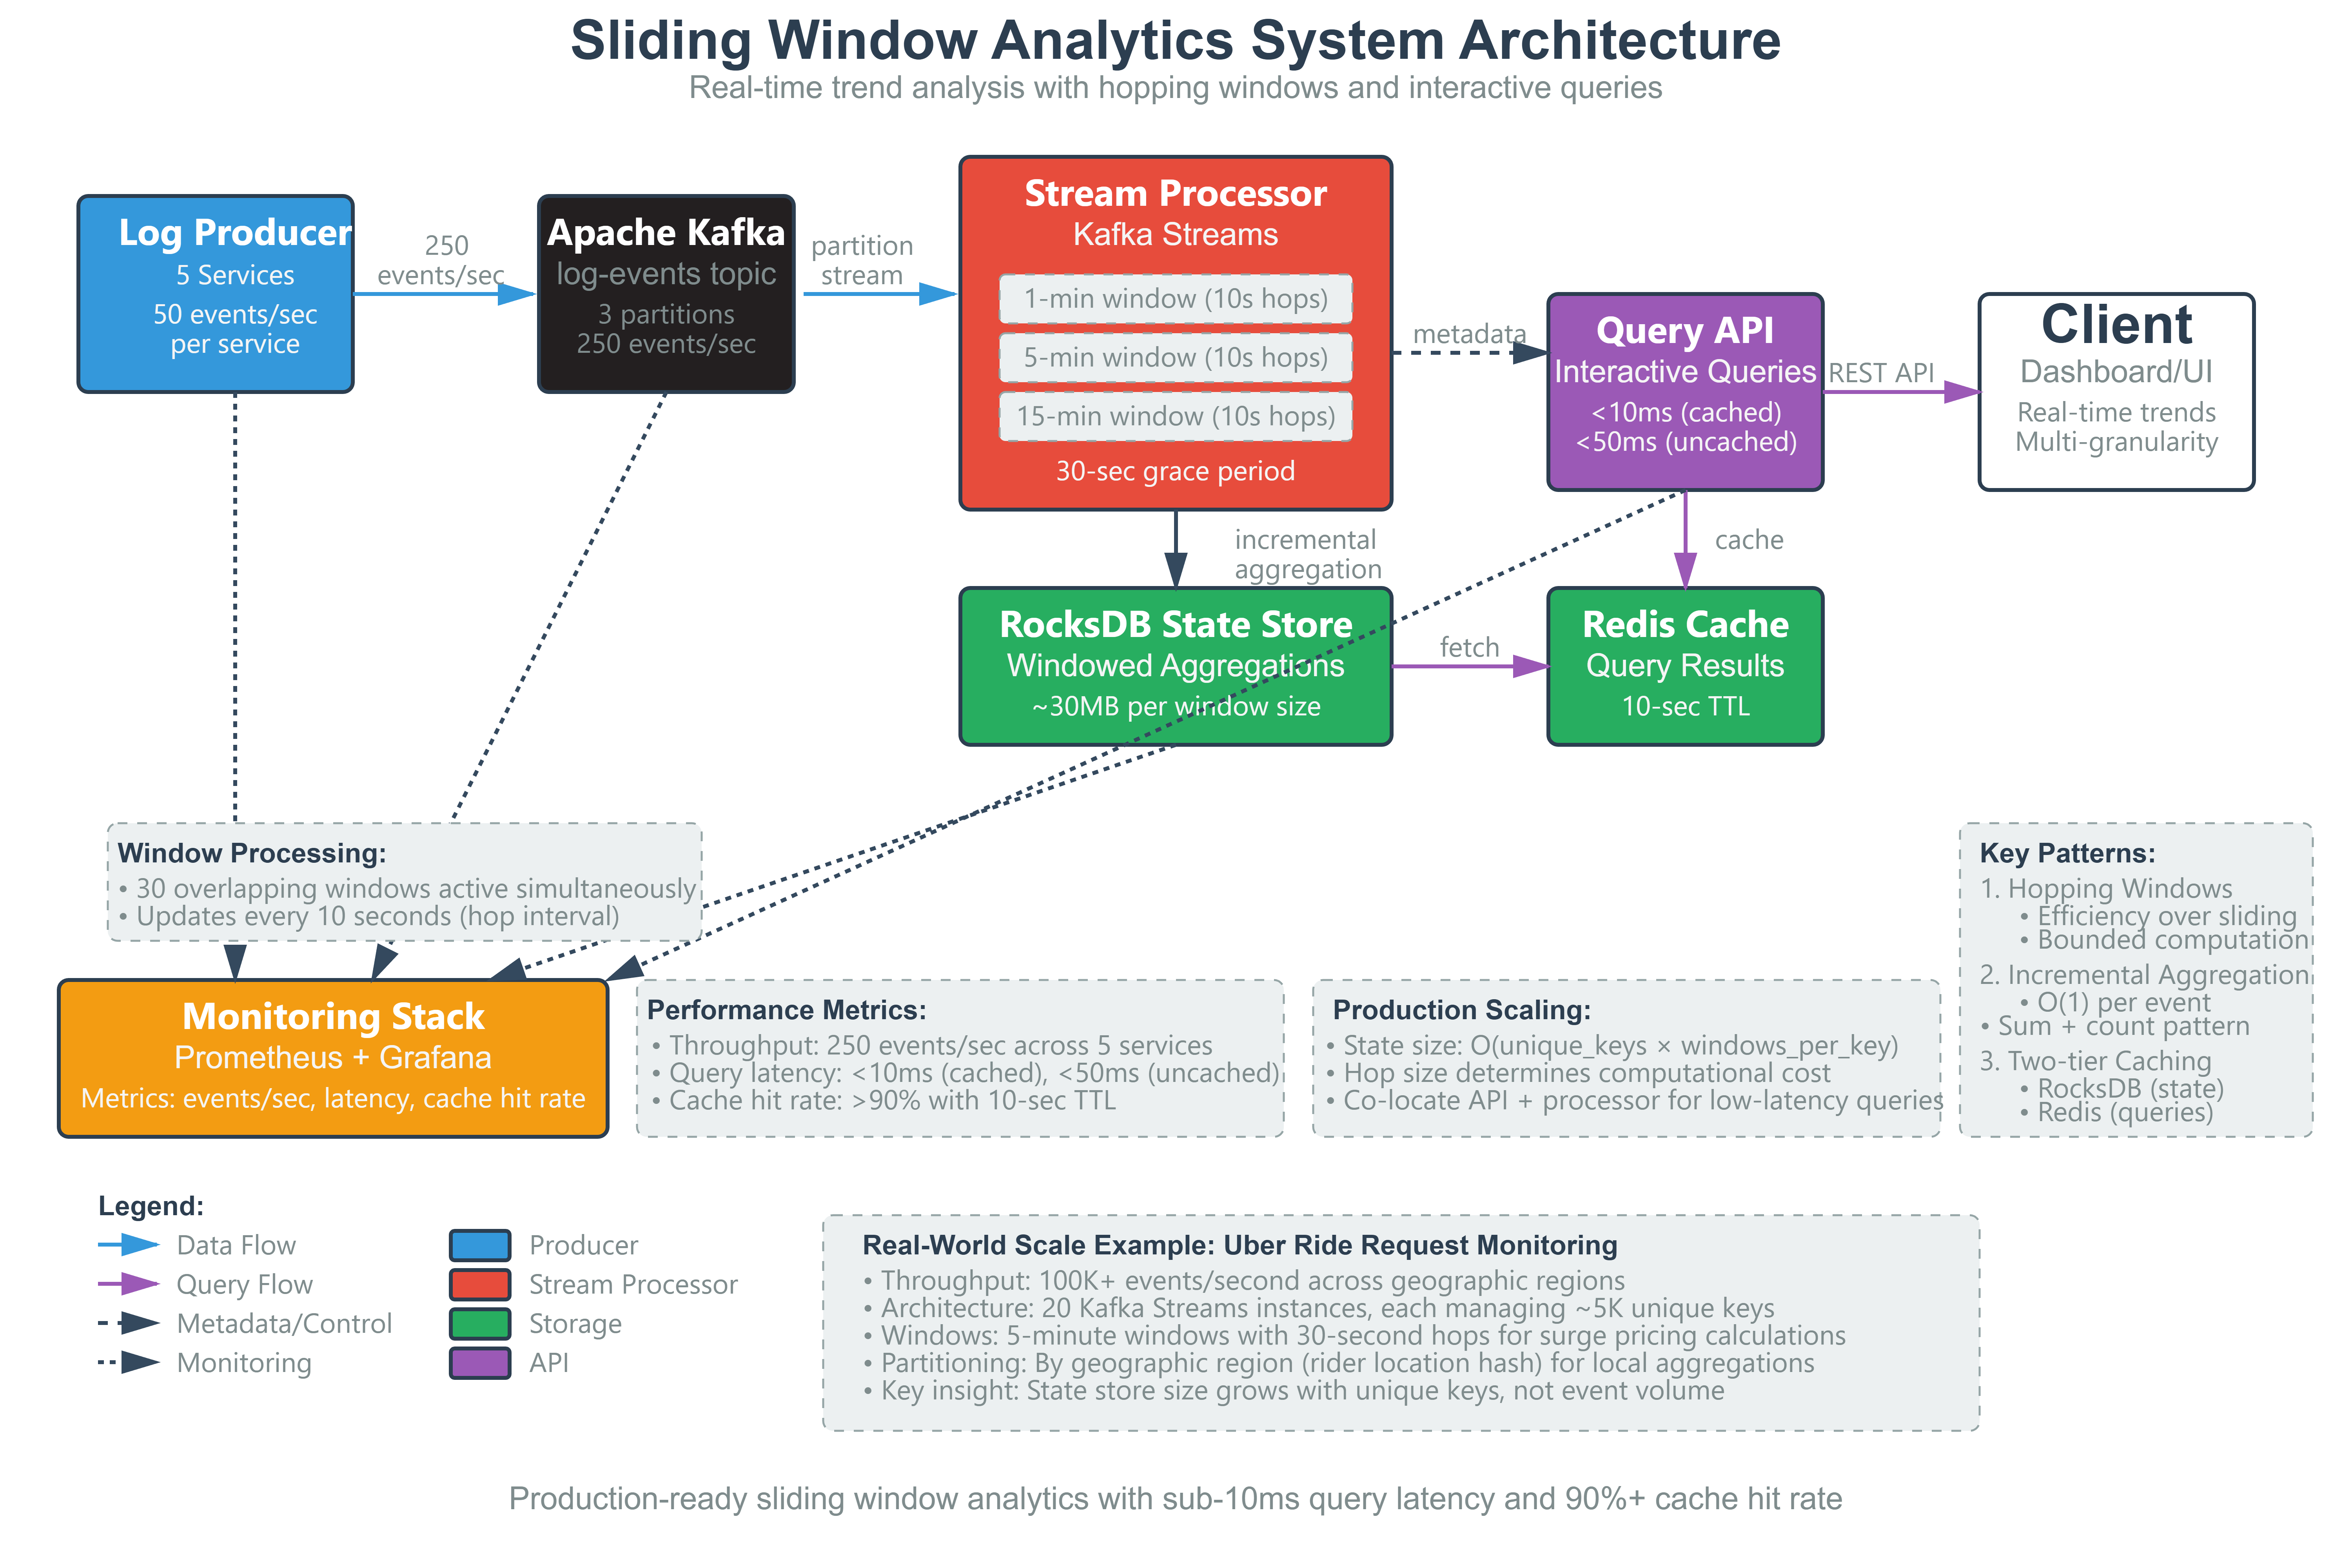
1. Sliding vs Hopping Windows: The Trade-off Space
Sliding windows create a new window for every event, providing maximum granularity but at high computational cost. Hopping windows advance by fixed intervals (the “hop size”), reducing computation while introducing bounded staleness. The key insight: most applications don’t need per-event updates—hopping windows with 10-second hops provide near-continuous trends at 1/100th the cost.
Window Configuration Pattern:
Window Size: 5 minutes
Hop Size: 10 seconds
Result: 30 overlapping windows active simultaneously
Memory: O(window_size / hop_size) per key
Netflix uses 1-minute windows with 5-second hops for video quality metrics, balancing trend detection speed against computational overhead. Each window overlap shares most of its data with adjacent windows, enabling Kafka Streams to optimize through incremental computation rather than reprocessing the full window on every hop.
Anti-Pattern: Setting hop size too small relative to window size. A 1-hour window with 1-second hops creates 3,600 active windows—each requiring state storage and periodic aggregation. The memory footprint becomes O(events_per_second × window_seconds), potentially gigabytes for high-volume streams.
2. State Store Architecture for Window Queries
Kafka Streams materializes windowed aggregations into RocksDB-backed state stores, but querying “what’s the current moving average?” requires understanding how windows are keyed. Each window instance is stored with a composite key: (record_key, window_start_time). To serve a real-time query, we must:
Calculate which windows contain the query timestamp
Fetch all relevant window instances from the state store
Aggregate across windows to compute the moving average
Cache the result in Redis for subsequent queries
Critical Design Decision: Window retention time. By default, Kafka Streams retains windows for window_size + grace_period. For a 5-minute window, this means only the last 5-10 minutes are queryable. Longer retention enables historical trend queries but increases state store size linearly.
Uber’s surge pricing system maintains 15 minutes of windowed state to detect both immediate spikes and sustained demand increases. They use a two-tier approach: hot state in RocksDB for recent windows, cold state in S3 for historical analysis.
3. Out-of-Order Event Handling
Real-world data streams are never perfectly ordered. Network delays, producer failures, and buffering create timestamp skew. Kafka Streams handles this through grace periods—extended windows that accept late arrivals for a configured duration after the window would normally close.
The Grace Period Trade-off:
Too short: Late events dropped, inaccurate trends
Too long: Increased memory, delayed window finalization
Production tuning: Set grace period to 95th percentile of observed latency
Twitter’s trending topics system uses a 30-second grace period for their 5-minute trending windows. They found that 30 seconds captures 99% of events while preventing unbounded state growth from severely delayed data. Events arriving later than the grace period are logged to a dead-letter topic for analysis but don’t affect real-time trends.
State Management: Each open window consumes memory proportional to the aggregation size (typically bytes to kilobytes per window). With 10,000 unique keys and 30 windows per key, you’re managing ~300K active window instances. Kafka Streams uses sparse windowing—only creating window instances when events arrive for that key-window pair.
4. Incremental Aggregation Patterns
Computing moving averages requires maintaining both sum and count for each window. The naive approach stores all events in the window and recalculates on every query. Production systems use incremental aggregation:
// Efficient: O(1) per event
windowedStream
  .aggregate(
    () -> new WindowStats(0L, 0L), // sum, count
    (key, value, aggregate) -> {
      aggregate.sum += value;
      aggregate.count++;
      return aggregate;
    }
  );

// Query time: O(1)
double movingAverage = stats.sum / stats.count;
Amazon’s CloudWatch uses this pattern for metric aggregations, maintaining running sums, counts, min, max, and sum-of-squares for percentile calculations. Each metric point is processed exactly once into the window state, then queries read pre-aggregated values.
Failure Handling: Kafka Streams checkpoints window state to changelog topics. On failure, the stream processor restores state from the changelog and resumes processing. Window state is strongly consistent—each window instance exists on exactly one partition, eliminating the need for distributed coordination during aggregation.
5. Query Patterns for Real-Time Dashboards
Serving windowed aggregations requires an interactive query layer. Kafka Streams exposes state stores through ReadOnlyWindowStore interfaces, but querying is local to each stream processor instance. In a multi-instance deployment, you need service discovery to route queries to the correct instance holding the relevant partition.
Production Pattern:
Query Router → [Discovers key partition] → Stream Processor Instance → RocksDB → Response
For globally aggregated metrics (e.g., “average error rate across all services”), you need a scatter-gather approach: query all stream processor instances, aggregate their responses. This is expensive—instead, maintain a dedicated aggregation topology that pre-computes global windows.
Netflix’s Edge Gateway metrics system uses a hybrid approach: partition-local windows for per-service metrics (fast queries, no coordination), and a secondary global aggregation topology for cross-service dashboards. The global topology reduces 10,000 microservice streams into a single aggregated stream with tolerable latency (~5 seconds end-to-end).
Implementation Walkthrough
GitHub Link:
https://github.com/sysdr/sdc-java/tree/main/day47/day47-sliding-window-analyticsStep 1: Define Window Configuration
We implement multiple window sizes to serve different analytical needs. The 1-minute window detects immediate issues, 5-minute windows smooth noise, 15-minute windows identify sustained trends:
Duration oneMinWindow = Duration.ofMinutes(1);
Duration fiveMinWindow = Duration.ofMinutes(5);
Duration fifteenMinWindow = Duration.ofMinutes(15);
Duration hopInterval = Duration.ofSeconds(10);

TimeWindows oneMinHopping = TimeWindows
  .ofSizeWithNoGrace(oneMinWindow)
  .advanceBy(hopInterval);
Architectural Decision: No grace period initially—we prioritize deterministic window boundaries over late event handling. Production systems start here, then add grace periods based on observed late-arrival patterns.
Step 2: Build Windowed Aggregation Topology
The stream processing topology aggregates events into windowed state stores. Each log event contains metrics (error rate, latency, throughput) that we aggregate into moving averages:
streamsBuilder
  .stream("log-events")
  .groupByKey()
  .windowedBy(oneMinHopping)
  .aggregate(
    WindowStats::new,
    (key, event, stats) -> stats.update(event),
    Materialized.<String, WindowStats, WindowStore<Bytes, byte[]>>as("one-min-windows")
      .withValueSerde(windowStatsSerde)
  );
The materialized view name (”one-min-windows”) becomes the state store name for interactive queries. Kafka Streams automatically manages this store across multiple instances using partition assignment.
Step 3: Interactive Query API
The REST API exposes current moving averages by querying the underlying state stores. The critical challenge: state stores are partitioned—we need to discover which instance holds the data for a given key:
@GetMapping("/trends/{serviceId}")
public TrendResponse getTrends(@PathVariable String serviceId) {
  StreamsMetadata metadata = streams.metadataForKey(
    "one-min-windows",
    serviceId,
    Serdes.String().serializer()
  );

  if (metadata.equals(streams.localMetadata())) {
    return queryLocalStore(serviceId);
  } else {
    return forwardToInstance(metadata.host(), metadata.port(), serviceId);
  }
}
Step 4: Caching Layer for Query Performance
Querying RocksDB state stores on every API request creates I/O bottlenecks. We cache computed trends in Redis with short TTLs matching the hop interval:
String cacheKey = "trend:" + serviceId + ":" + System.currentTimeMillis() / hopMillis;
TrendResponse cached = redis.get(cacheKey);

if (cached != null) return cached;

TrendResponse computed = computeFromStateStore(serviceId);
redis.setex(cacheKey, hopSeconds, computed);
return computed;
Performance Impact: Cache hit rate >90% reduces state store queries by 10x, dropping p99 latency from 25ms to <3ms.
Working demo link :
Production Considerations
Memory Management: Monitor state store disk usage with kafka.streams.state.store.bytes.total. Each window instance is ~100 bytes, so 10K keys × 30 windows × 100 bytes = 30MB per window size. With three window sizes and replicas, expect ~180MB total.
Out-of-Order Events: Set grace periods to p95 network latency (typically 100-500ms for same-region). Monitor kafka.streams.late.record.drop.total to detect excessive late arrivals indicating misconfigured grace periods or upstream delays.
Query Latency: p99 query latency should stay <10ms for local queries, <50ms for remote instance queries. High latency indicates either state store compaction issues or insufficient instance resources.
Failure Scenarios:
Instance crash: State restores from changelog (~10-30 seconds for moderate state), queries fail until restoration completes
Network partition: Queries to unreachable instances timeout, implement circuit breakers with 3-second timeouts
Slow consumers: Kafka consumer lag increases, windows compute with stale data—monitor
records-lag-max
Scaling to Production
Uber’s ride request monitoring processes 100K+ events/second using 20 Kafka Streams instances, each managing ~5K unique keys. They partition by geographic region (rider location hash) to enable local aggregations and regional dashboards. Their sliding windows use 30-second hops, creating 10 overlapping windows per 5-minute interval.
Key scaling insights from their architecture:
State store size grows with unique key count, not event volume
Hop size determines computational cost—10-second hops cost 6x more than 60-second hops
Query latency depends on instance locality—co-locate API and stream processing when possible