
What We’re Building Today
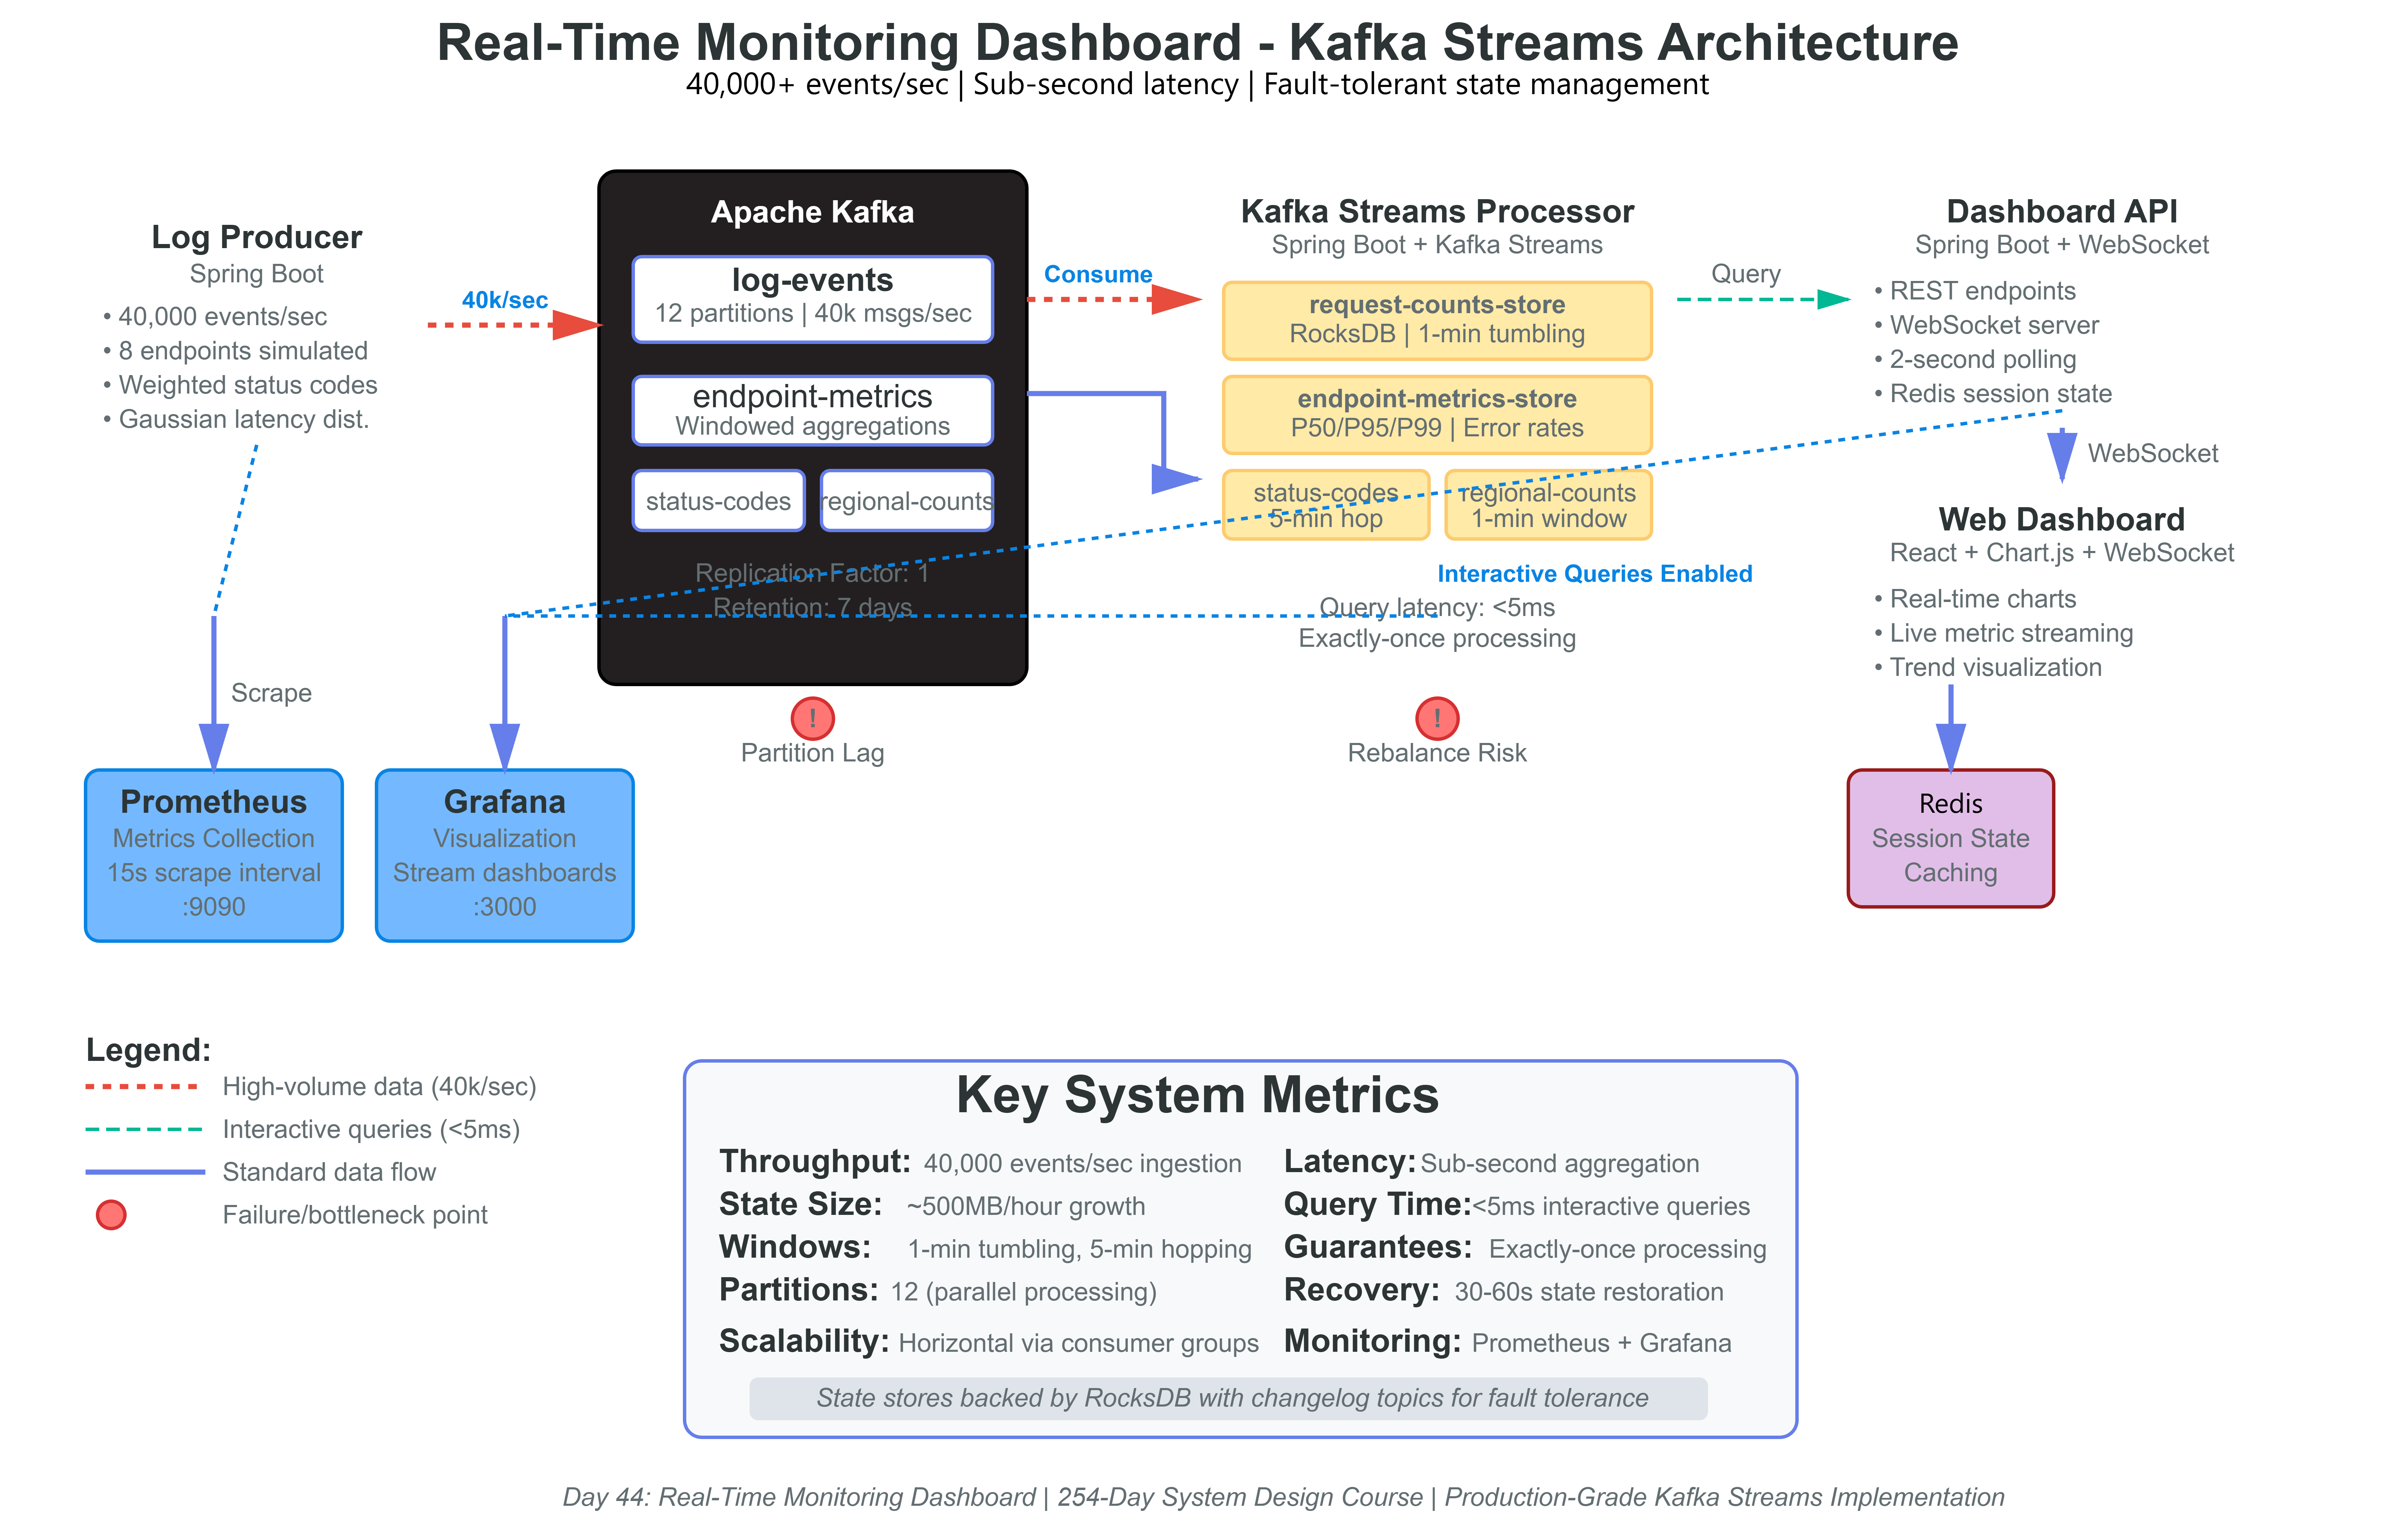
Live metrics aggregation system processing 40,000+ events/second with sub-second latency
Kafka Streams processor performing windowed aggregations, percentile calculations, and anomaly detection
Real-time dashboard API serving live statistics with WebSocket updates
Production monitoring stack with Grafana dashboards tracking stream processor health
Fault-tolerant state management using RocksDB-backed state stores with changelog topics
Why This Matters: Observability at Internet Scale
When Netflix processes 450 billion events per day from their streaming platform, or Uber analyzes 100 million trip events daily, they need real-time visibility into system behavior. Traditional batch processing creates blind spots—by the time you see yesterday’s metrics, today’s incidents have already cascaded. Real-time stream processing transforms raw events into actionable insights within milliseconds, enabling immediate detection of anomalies, capacity issues, and user-impacting problems.
The challenge isn’t just aggregating data—it’s maintaining accurate state across failures, handling late-arriving events, managing memory with billions of unique keys, and providing consistent results during rebalances. A poorly designed streaming pipeline can lose data during crashes, produce duplicate counts after restarts, or fall behind during traffic spikes. Today we’ll build a production-grade monitoring system that handles these challenges using Kafka Streams’ exactly-once semantics, fault-tolerant state stores, and windowed aggregations.
System Design Deep Dive: Stream Processing Patterns
1. Stateful Stream Processing with RocksDB
Kafka Streams maintains state locally in embedded RocksDB databases, backed by Kafka changelog topics. When your stream processor calculates “requests per minute” or “95th percentile latency,” it’s not querying a database—it’s updating in-memory/on-disk state stores that survive process crashes. Each state store has a corresponding changelog topic that captures every state mutation. If a processor crashes, the replacement reads the changelog to rebuild state from the last checkpoint.
Trade-off: Local state provides sub-millisecond query latency but limits scalability to disk capacity per instance. For aggregations tracking millions of unique keys, you must partition state across multiple processor instances. The group_id determines which processor owns which keys—consistent hashing ensures the same keys always route to the same partition.
Anti-pattern: Storing unbounded state. Without time-based eviction (windowing) or size limits, state stores grow indefinitely. A service tracking “unique users per endpoint” will eventually run out of disk if it never expires old keys. Always implement retention policies aligned with business requirements.
2. Windowed Aggregations and Time Semantics
Stream processing must handle time ambiguity—events arrive with: processing time (when the processor sees it), event time (when it actually occurred), and ingestion time (when Kafka received it). A log event from 10 minutes ago arriving now (due to network delays) must contribute to the correct time window, not the current one.
Kafka Streams supports tumbling windows (non-overlapping 1-minute buckets), hopping windows (overlapping 5-minute windows advancing every 1 minute), and session windows (grouped by inactivity gaps). Each creates different trade-offs: tumbling windows provide simple counts but miss trends across boundaries; hopping windows smooth outliers but duplicate event processing; session windows handle bursty traffic but complicate memory management.
Production insight: Always configure grace periods for late arrivals. A 1-minute window with 30-second grace accepts events up to 1:30 after window close, balancing completeness against latency. LinkedIn’s Samza learned this the hard way—their initial streaming pipelines dropped 2% of events during peak load because they closed windows too aggressively.
3. Materialized Views and Interactive Queries
State stores serve dual purposes: internal processing state and queryable materialized views. Your Kafka Streams application can expose REST endpoints that query local state stores directly, bypassing external databases. When the dashboard requests “current requests/sec by endpoint,” the API queries the stream processor’s state store—no database roundtrip needed.
Scaling consideration: State stores are partitioned—a query for /api/users might land on instance-1, but that instance only holds state for partition 0. You need either: (1) scatter-gather queries across all instances, (2) routing proxy directing queries to correct partition, or (3) global state stores replicated to all instances. Global stores solve routing but triple memory usage for frequently queried data.
Twitter’s architecture: Their real-time analytics use interactive queries against Kafka Streams state stores for the first 7 days of data, then fall back to Druid for historical analysis. This hybrid approach balances query latency (5ms from state stores vs 50ms from Druid) against storage costs.
4. Exactly-Once Stream Processing
Kafka Streams achieves exactly-once semantics through transactional writes—each processing step (read input, update state, write output) executes atomically. If the processor crashes mid-transaction, the entire operation rolls back. This prevents duplicate counts after restarts, a common bug in at-least-once processing.
Implementation: Enable processing.guarantee=exactly_once_v2 and ensure all state operations happen within the topology. External side effects (database writes, API calls) break exactly-once guarantees—if your stream processor writes to PostgreSQL, then crashes, the Kafka message will be reprocessed but the DB write won’t roll back, creating duplicates.
Trade-off: Exactly-once processing adds 10-15% latency overhead from transactional commits. For monitoring dashboards where occasional duplicates are acceptable, at-least-once processing provides better throughput. For financial transactions or user account state, exactly-once is mandatory.
5. Stream Processing Failure Modes
Stream processors fail differently than request-response services. A crashed processor doesn’t just stop responding—it triggers rebalances that temporarily halt all partition processing. During rebalance, the dashboard shows stale data until state restoration completes (reading changelog topics can take 30-60 seconds for large state stores).
Cascading failures: One slow processor instance causes Kafka consumer group heartbeat timeouts, triggering rebalances across all instances, pausing all processing during state restoration, creating backlog that overloads instances when they resume. This cascade can bring down entire streaming pipelines.
Mitigation: Implement backpressure handling—if state stores can’t keep up with ingestion rate, the processor should pause consumption rather than accepting unbounded backlog. Configure max.poll.interval.ms generously (5 minutes) to prevent false-positive timeouts during legitimate processing spikes.
Implementation Walkthrough: Building the Monitoring Pipeline
GitHub Link:
https://github.com/sysdr/sdc-java/tree/main/day44/realtime-monitoring-dashboard Service Architecture
Our system consists of four Spring Boot services:
log-producer generates realistic log events (HTTP requests, database queries, cache operations) at 40,000 events/second. Each event includes timestamp, endpoint, response time, status code, and user identifier. Events flow into log-events Kafka topic with 12 partitions for parallelism.
stream-processor consumes from log-events, performs windowed aggregations (requests per minute, error rates, latency percentiles), and materializes results to state stores. It exposes REST endpoints querying these state stores—no external database required. The processor computes:
Request count per endpoint per minute (tumbling window)
Error rate by status code per 5-minute window (hopping)
P50, P95, P99 latency using t-digest algorithm
Anomaly detection flagging 3-sigma deviations
dashboard-api serves WebSocket connections, polling the stream processor’s interactive queries every second and pushing updates to connected clients. It maintains connection state in Redis for horizontal scaling—multiple API instances can serve different dashboard clients.
dashboard-ui provides a single-page React application with real-time charts. We use Recharts for time-series visualization and WebSocket API for live data streaming.
Kafka Streams Topology
StreamsBuilder builder = new StreamsBuilder();

KStream<String, LogEvent> events = builder.stream("log-events");

// Windowed aggregation: requests per endpoint per minute
KTable<Windowed<String>, Long> requestCounts = events
    .groupBy((key, event) -> event.getEndpoint())
    .windowedBy(TimeWindows.ofSizeWithNoGrace(Duration.ofMinutes(1)))
    .count(Materialized.as("request-counts-store"));

// Error rate calculation
KTable<Windowed<String>, Double> errorRates = events
    .groupBy((key, event) -> event.getEndpoint())
    .windowedBy(TimeWindows.ofSizeWithNoGrace(Duration.ofMinutes(5)))
    .aggregate(
        ErrorRateAccumulator::new,
        (key, event, accumulator) -> accumulator.add(event),
        Materialized.as("error-rates-store")
    )
    .mapValues(acc -> acc.calculateRate());
The topology defines data flow transformations—grouping, windowing, aggregation—that execute across multiple instances. State stores (request-counts-store) automatically partition across stream processor instances based on endpoint hash.
Interactive Query Implementation
The stream processor exposes REST endpoints that query local state stores:
@GetMapping("/metrics/requests")
public Map<String, Long> getRequestCounts() {
    ReadOnlyWindowStore<String, Long> store =
        streams.store(StoreQueryParameters.fromNameAndType(
            "request-counts-store",
            QueryableStoreTypes.windowStore()
        ));

    Instant now = Instant.now();
    Instant start = now.minus(Duration.ofMinutes(5));

    Map<String, Long> results = new HashMap<>();
    store.all().forEachRemaining(kv -> {
        if (kv.key.window().end() >= start.toEpochMilli()) {
            results.put(kv.key.key(), kv.value);
        }
    });
    return results;
}
This query runs in O(k) time where k is the number of endpoints—no database query, no network calls, pure local state access.
Working Demo Link :
State Store Failure Recovery
When a stream processor crashes, Kafka Streams handles recovery automatically:
Consumer group rebalances—partitions reassign to surviving instances
New partition owner reads changelog topic from last committed offset
State store rebuilds from changelog (may take 30-60 seconds)
Processing resumes once state restoration completes
During restoration, the state store is unavailable—queries return 503. The dashboard API must handle this gracefully, showing “loading” state until the processor recovers.
Production Considerations
Performance bottlenecks: State store compaction is CPU-intensive—RocksDB background threads can consume 20-30% CPU even during steady-state operation. Monitor rocksdb.total-sst-files-size metric—growth beyond available disk indicates insufficient compaction. Increase rocksdb.max-background-compactions if you see compaction delays.
Memory management: Each windowed aggregation creates new state store entries—1,000 endpoints × 5-minute window retention × 12 windows = 60,000 state entries. With 40,000 events/sec, memory usage grows at ~500MB/hour. Implement time-based retention using suppress operators to purge old windows automatically.
Monitoring critical metrics:
kafka-streams-state-store-lag: Indicates how far behind state stores are from Kafka topics (target: <1000)stream-processor-commit-latency-avg: Time to commit state changes (target: <100ms)rebalance-time: Downtime during partition reassignment (target: <30 seconds)
Failure scenario testing: Simulate instance crashes with kill -9, verify state restoration completes within SLA, confirm no data loss or duplicate counts. Test backpressure handling—what happens when ingestion rate exceeds processing capacity? The system should pause consumption rather than falling behind indefinitely.
Scale Connection: Real-World Stream Processing
LinkedIn’s Venice: Processes 400,000 events/second using Kafka Streams with 2TB of state distributed across 50 stream processor instances. They achieve P99 query latency of 5ms by pre-aggregating hot keys (top 1000 endpoints) into separate state stores cached in memory.
Uber’s AresDB: Real-time analytics on 100 million trips/day use GPU-accelerated aggregations in Kafka Streams pipelines. By offloading percentile calculations to CUDA kernels, they reduced per-event processing time from 2ms to 0.3ms, enabling real-time fraud detection across 10,000+ cities.
Netflix’s Keystone: Monitors 450 billion events/day from streaming devices using Kafka Streams for real-time alerting. They partition state by region (us-east-1, eu-west-1) to isolate failures—an outage in one region doesn’t halt global monitoring.
Key Insight: Real-time monitoring isn’t about speed—it’s about maintaining accurate state across failures while processing unbounded data streams. The hard problem is making your aggregations survive the chaos of production: crashes, rebalances, network partitions, and traffic spikes.