
The Message Highway That Never Sleeps
Picture the data highways inside Netflix's infrastructure during a Friday night when millions stream simultaneously. Every click, every pause, every recommendation generates logs that must flow instantly to dozens of systems. This isn't handled by simple queues—it requires Apache Kafka, the distributed streaming platform that's become the backbone of modern log processing.
Today we're building your first production-ready Kafka cluster, the critical infrastructure that transforms chaotic log streams into organized, reliable data highways.
Why Kafka Rules Log Processing
Yesterday you built priority queues for critical logs, but what happens when you need to handle 10 million log events per second while guaranteeing delivery to multiple consumers? Traditional message queues hit walls that Kafka demolishes:
Persistent Storage: Unlike in-memory queues, Kafka persists messages to disk, creating an immutable log that survives crashes and allows historical replay.
Horizontal Scaling: Need more throughput? Add brokers. Need better distribution? Add partitions. Kafka scales linearly.
Multiple Consumers: The same log stream feeds real-time analytics, batch processing, and alerting systems simultaneously without interference.
Kafka's Distributed Architecture
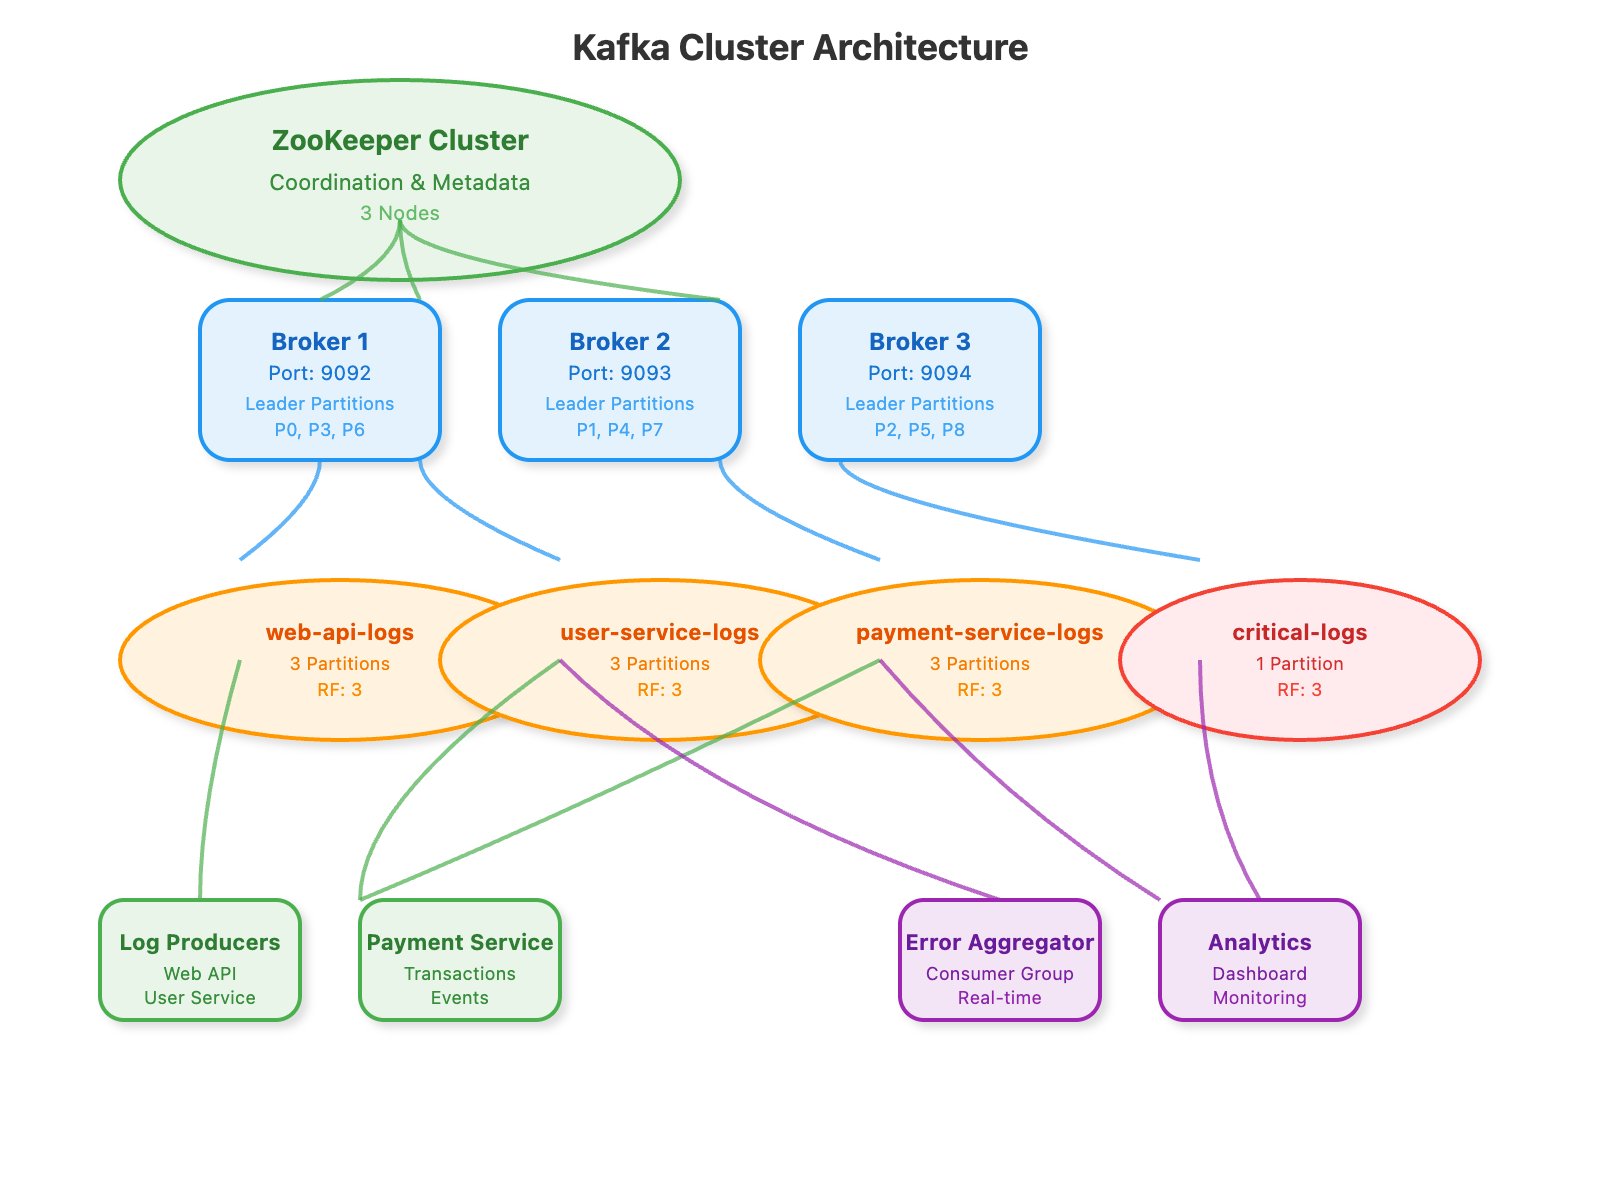
GitHub Link:
https://github.com/sysdr/course-p/tree/main/day38