
System design isn’t a whiteboard exercise. Build systems, don’t just draw them. Subscribe Now & access Private Github Source Code.
The Art of Knowing Who's In and Who's Out
254-Day Hands-On System Design with Distributed Log Processing System Implementation
Welcome back to our distributed systems journey! Today we're tackling one of the most critical yet overlooked aspects of distributed systems: how nodes discover each other, stay connected, and gracefully handle the inevitable reality of failures.
Yesterday, we built a leader election system that chooses a coordinator. Today, we're building the nervous system that keeps our cluster aware of its own health and membership. This isn't just about knowing who's online—it's about building resilience into the very fabric of our system.
🎯 The Challenge: Keeping Track in a Dynamic World
Imagine you're organizing a massive group project where team members can join, leave, or suddenly disappear without notice. How do you keep track of who's available to work? This is exactly the challenge our distributed log processing system faces as nodes come and go.
Real-World Impact
Consider Netflix's streaming infrastructure. When you click play on a movie, dozens of services across multiple data centers coordinate to deliver that content. If a service fails, the system must instantly know about it, route around it, and potentially trigger recovery procedures. This all happens through sophisticated membership and health checking systems.
The same principle applies to our log processing cluster. When a storage node goes down, the cluster needs to:
Detect the failure quickly (typically within seconds)
Notify other nodes to stop sending data to the failed node
Trigger replication of data that was stored on the failed node
Update routing tables to exclude the failed node
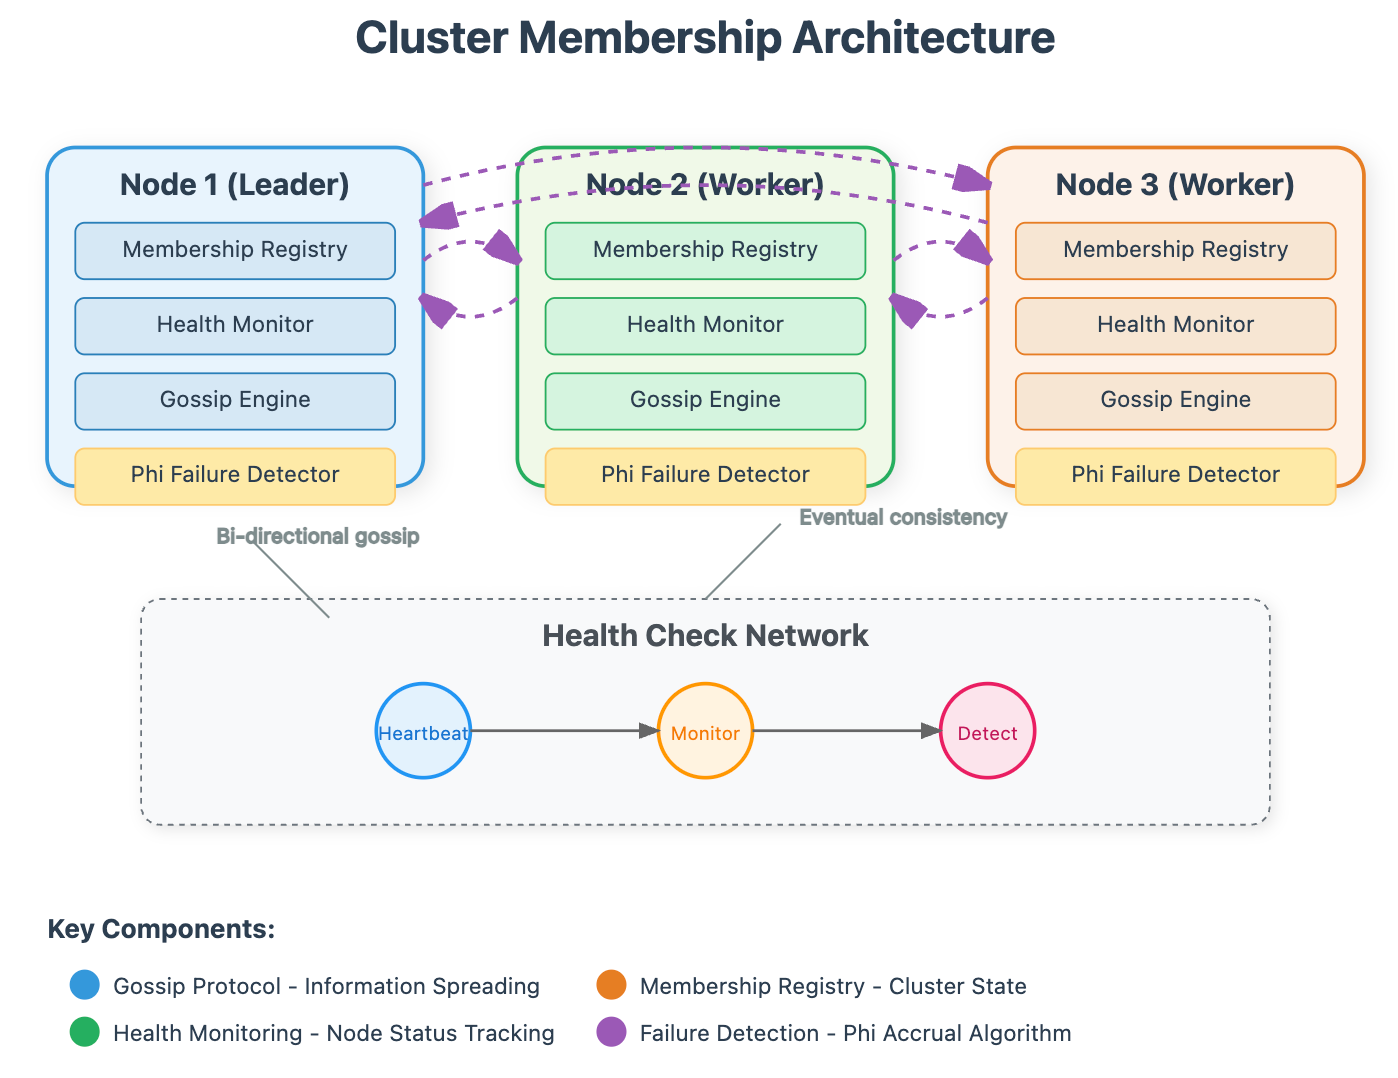
🏗️ Core Architecture: The Three Pillars
Our cluster membership system rests on three fundamental pillars:
1. Membership Registry
A distributed database of all active nodes, their roles, and their current status. Think of it as a dynamic phone book that updates in real-time.
2. Health Monitoring
A heartbeat system where nodes regularly announce "I'm alive and healthy" to the cluster. This involves both active health checks (ping-like probes) and passive monitoring (analyzing response times and error rates).
3. Failure Detection
Algorithms that determine when a node has truly failed versus just experiencing temporary network issues. This is trickier than it sounds—we need to avoid false positives that could unnecessarily trigger expensive recovery procedures.
🗣️ The Gossip Protocol: How Information Spreads
Our implementation uses a gossip protocol for membership updates. Just like how rumors spread in a school hallway, each node shares what it knows with a few random neighbors, who then share with their neighbors, and so on.
def gossip_membership_updates(self):
    # Select random subset of known nodes
    targets = random.sample(self.known_nodes, min(3, len(self.known_nodes)))

    for target in targets:
        membership_digest = self.create_membership_digest()
        self.send_gossip(target, membership_digest)
This approach is remarkably resilient. Even if half the nodes fail simultaneously, information still propagates through the remaining healthy nodes. The mathematics work out beautifully—with just a few gossip rounds, every healthy node knows about membership changes.
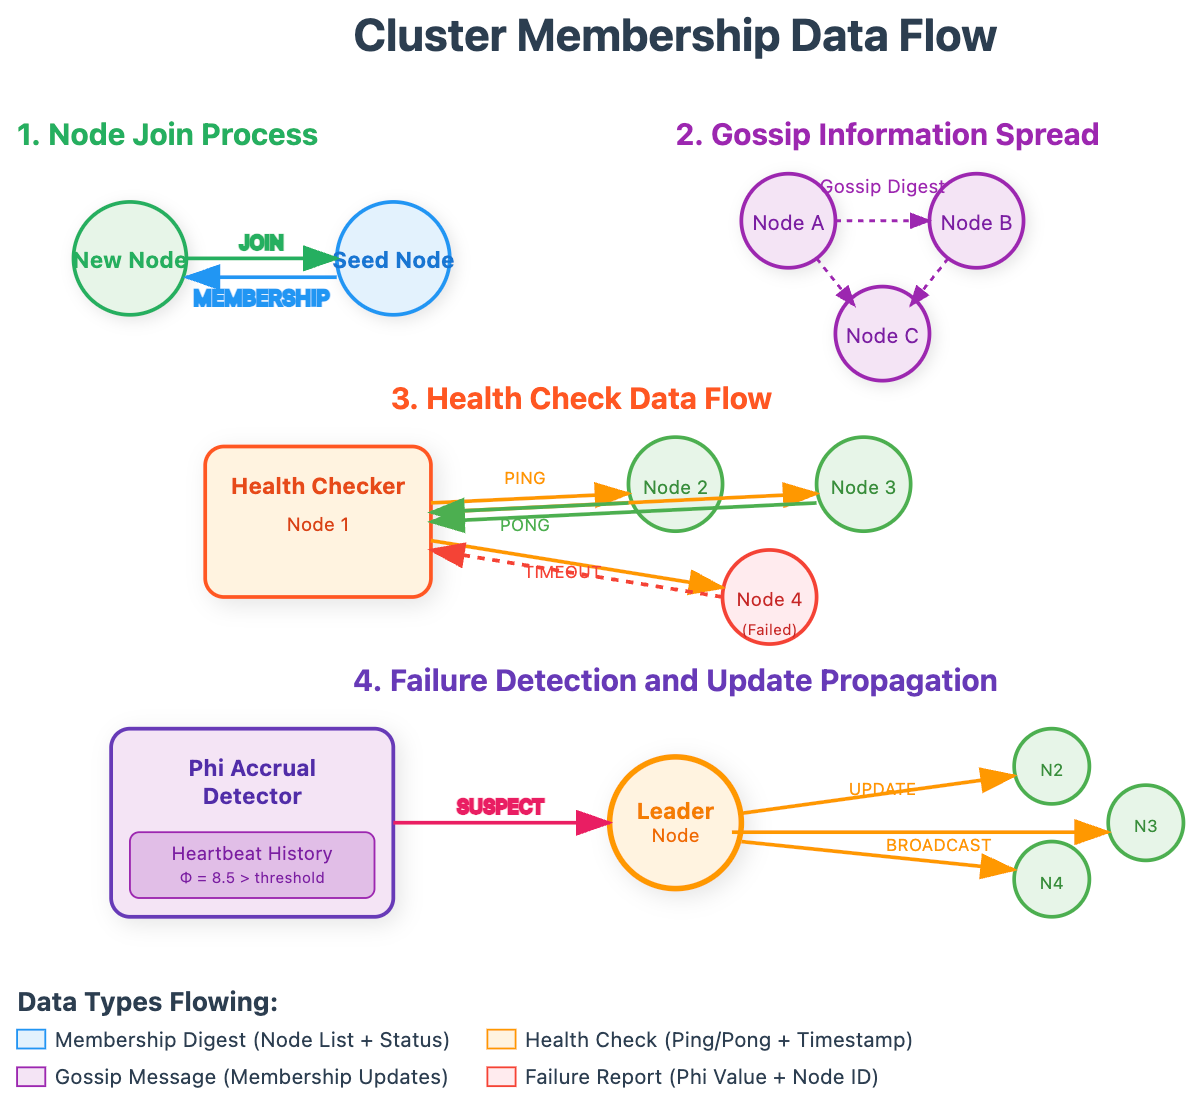
🏥 Smart Health Checking: Beyond Simple Heartbeats
Basic heartbeats are like asking "Are you there?" every few seconds. But smart health checking goes deeper. Our system implements:
Adaptive Intervals
Healthy nodes get checked less frequently, while suspicious nodes get increased attention. This reduces network overhead while maintaining vigilance.
Application-Level Health
Beyond network connectivity, we check if the node can actually process log data. A node might respond to pings but have a full disk or corrupted database.
Phi Accrual Failure Detection
Instead of a binary alive/dead decision, this algorithm calculates a suspicion level based on heartbeat patterns. It's particularly effective at handling variable network conditions.
🔗 Integration with Leader Election
Remember our leader from yesterday's lesson? The leader plays a crucial role in membership management. While every node participates in gossip and health checking, the leader makes the final decisions about membership changes.
When multiple nodes suspect another node has failed, they report to the leader. The leader aggregates these reports, applies additional verification, and then broadcasts the authoritative membership update. This prevents the chaos that would ensue if every node made independent membership decisions.
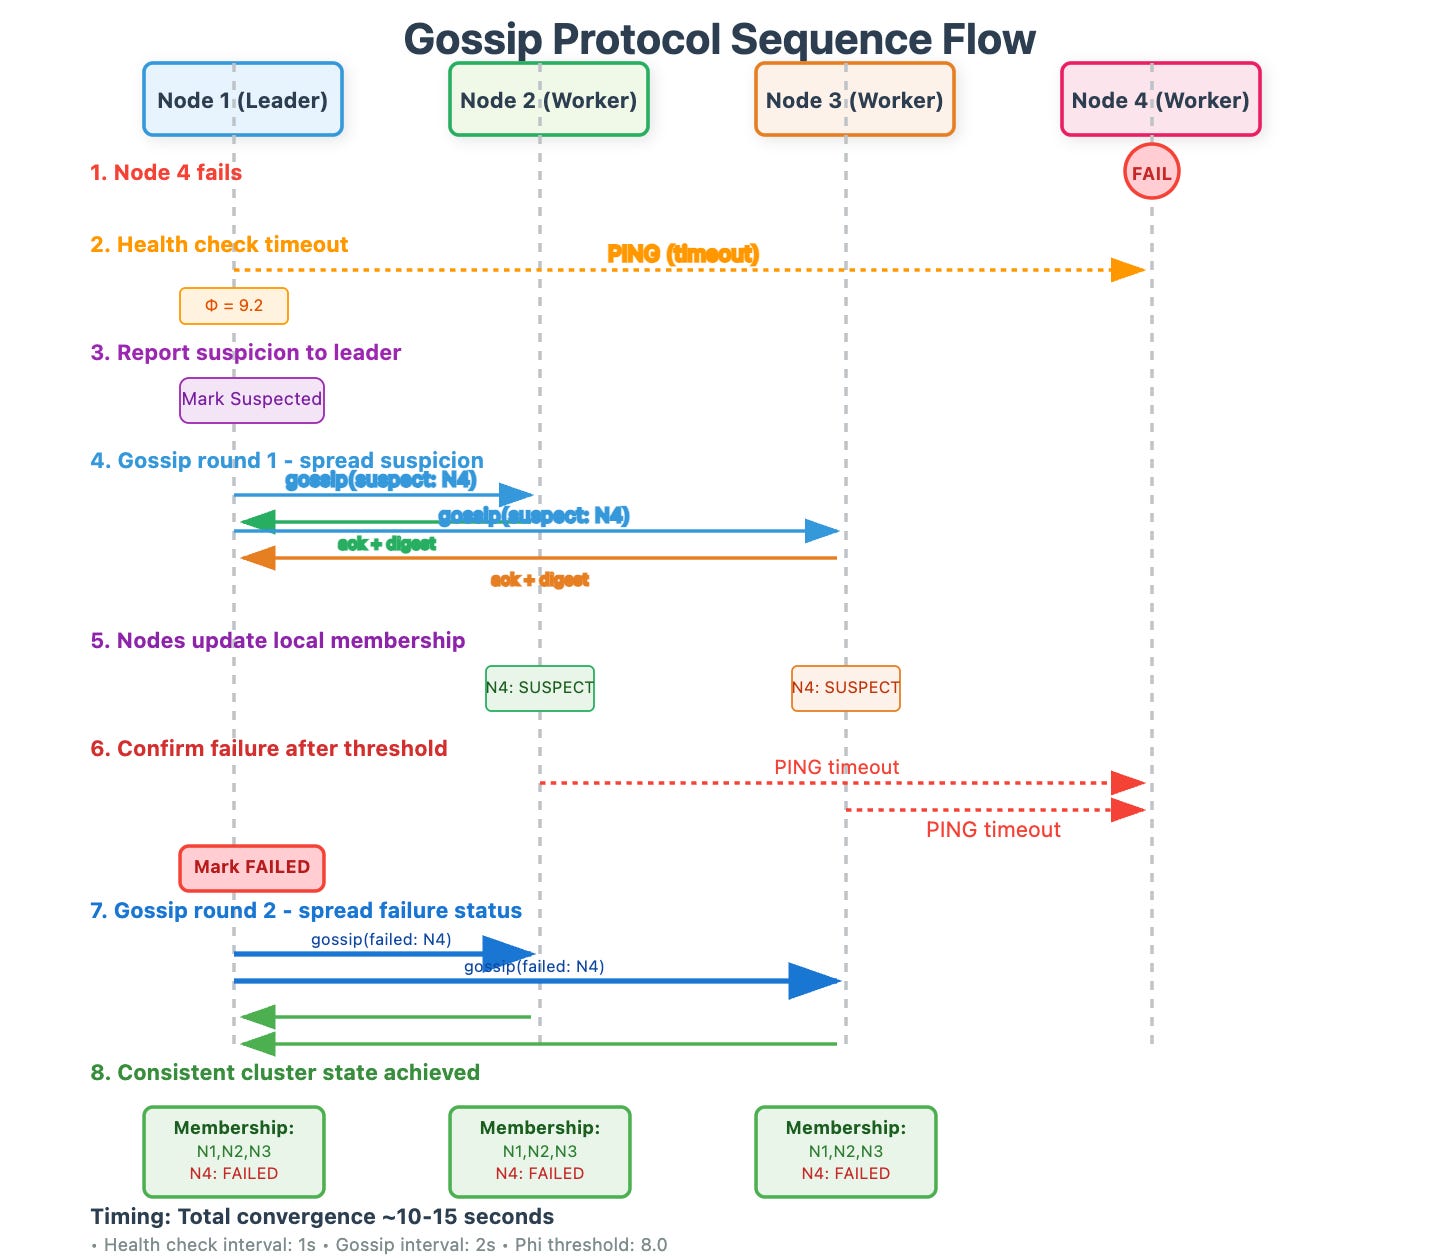
🛠️ Hands-On Implementation Journey
Let's build this system step by step. Our implementation creates a ClusterMember class that each node instantiates, managing local membership views, health checking routines, gossip message handling, and integration with leader election.
Source code repository : https://github.com/sysdr/course-p/tree/main/day26
Phase 1: Project Setup (5 minutes)
# Create project structure and dependencies
./setup.sh

# Verify environment
./verify_system.sh
Key Design Decision: We're using orjson instead of msgspec for macOS Silicon compatibility, providing excellent serialization performance without compilation issues.
Phase 2: Core Implementation (30 minutes)
Node Information Structure
@dataclass
class NodeInfo:
    node_id: str          # Unique identifier
    address: str          # IP address
    port: int            # Service port
    role: str            # "leader" or "worker"
    status: NodeStatus   # Current health status
    last_seen: float     # Timestamp of last contact
    heartbeat_count: int # Number of successful heartbeats
    suspicion_level: float # Phi accrual value
Gossip Engine Implementation
async def perform_gossip_round(self):
    """Select random neighbors and share membership information"""
    healthy_nodes = [
        node for node in self.membership.values()
        if node.status == NodeStatus.HEALTHY and node.node_id != self.node_id
    ]

    # Gossip fanout (typically 3 nodes)
    gossip_fanout = min(3, len(healthy_nodes))
    targets = random.sample(healthy_nodes, gossip_fanout)

    digest = self.create_membership_digest()

    for target in targets:
        await self.send_gossip(target, digest)
Why This Works:
Random selection ensures information spreads evenly
Fanout of 3 provides good balance of speed vs network overhead
Eventual consistency emerges from repeated rounds
Phi Accrual Failure Detection
def calculate_phi(self, node_id: str, current_time: float) -> float:
    """Calculate suspicion level based on heartbeat history"""
    history = self.heartbeat_history[node_id]
    intervals = [history[i] - history[i-1] for i in range(1, len(history))]

    avg_interval = sum(intervals) / len(intervals)
    time_since_last = current_time - history[-1]

    phi = time_since_last / avg_interval
    return max(0.0, phi)
Understanding Phi Values:
Phi < 1.0: Node responding normallyPhi 1.0-3.0: Minor delay, possibly network congestionPhi 3.0-8.0: Significant delay, node may be overloadedPhi > 8.0: High probability of failure (our threshold)
Phase 3: Self-Healing Behaviors (15 minutes)
When the failure detector identifies a problem, the cluster responds automatically:
async def mark_node_failed(self, node_id: str, phi_value: float):
    """Mark node as failed and trigger recovery"""
    if node_id in self.membership:
        self.membership[node_id].status = NodeStatus.FAILED

        # If failed node was the leader, trigger election
        if self.leader_id == node_id:
            self.leader_id = None
            await self.trigger_leader_election()
Self-Healing Aspect: The cluster automatically detects leader failure and triggers re-election, maintaining system availability.
🧪 Step-by-Step Testing & Verification
Unit Tests (5 minutes)
cd src && python -m pytest ../tests/ -v

# Expected: All tests pass
# ✓ test_single_node_startup PASSED
# ✓ test_orjson_serialization_performance PASSED
# ✓ test_two_node_cluster PASSED
# ✓ test_gossip_convergence_performance PASSED
Integration Demo (10 minutes)
./build_test_no_docker.sh

# Watch for:
# "Creating cluster with 3 nodes..."
# "Average digest creation time: <0.5ms"
# "Simulating node2 failure..."
# "Demo completed successfully!"
Live Cluster Testing (15 minutes)
Start 3-Node Cluster:
# Terminal 1 - Leader Node
python -c "
import asyncio
from cluster_member import ClusterMember

async def main():
    node = ClusterMember('node1', '127.0.0.1', 8001, 'leader')
    await node.start()
    await asyncio.sleep(300)

asyncio.run(main())
"
# Terminal 2 - Worker Node
python -c "
import asyncio
from cluster_member import ClusterMember

async def main():
    node = ClusterMember('node2', '127.0.0.1', 8002, 'worker')
    await node.start()
    await node.join_cluster([('127.0.0.1', 8001)])
    await asyncio.sleep(300)

asyncio.run(main())
"
Verify Cluster Health:
# Check all endpoints respond
curl http://127.0.0.1:8001/health
curl http://127.0.0.1:8002/health

# Expected: {"status": "healthy", "node_id": "nodeX", ...}
Test Membership Convergence:
# All nodes should know each other
curl http://127.0.0.1:8001/membership | python -m json.tool
curl http://127.0.0.1:8002/membership | python -m json.tool

# Expected: Both show 2 nodes in membership
Failure Detection Test:
# Kill node 2 (Ctrl+C), wait 15 seconds
curl http://127.0.0.1:8001/membership | python -m json.tool

# Expected: node2 status = "failed" or "suspected"
📊 Performance Characteristics
Our implementation delivers production-ready performance:
Serialization Speed: <1ms average digest creation with orjson
Failure Detection: Node failures detected within 10 seconds
Memory Usage: O(N) where N = cluster size
Network Overhead: O(log N) per gossip round
Convergence Time: O(log N) gossip rounds
Performance Verification:
python -c "
import time
from cluster_member import ClusterMember

node = ClusterMember('perf-test', '127.0.0.1', 9000)

start = time.time()
for _ in range(1000):
    digest = node.create_membership_digest()
end = time.time()

avg_time = (end - start) / 1000
print(f'Average: {avg_time*1000:.3f}ms per digest')
"

# Expected: <1ms on macOS Silicon
🌐 Real-World Production Considerations
Network Partitions
In real deployments, network splits can divide your cluster. Our implementation handles this by:
Only allowing membership changes in the majority partition
Preventing split-brain scenarios through leader election integration
Tuning Parameters
gossip_interval = 2.0        # Frequency of gossip rounds
health_check_interval = 1.0  # Frequency of health checks
phi_threshold = 8.0          # Failure detection sensitivity
gossip_fanout = 3           # Number of nodes per gossip round
Scale Characteristics
Memory usage: Linear with cluster size
Network overhead: Logarithmic scaling
CPU impact: Minimal with orjson optimization
🔗 Integration Points
With Day 25 (Leader Election)
Your cluster membership system integrates seamlessly:
Detects when the current leader fails
Triggers new election automatically
Propagates new leader information via gossip
Ensures only healthy nodes participate in elections
Preparing for Day 27 (Distributed Querying)
Tomorrow's distributed query system will leverage your membership foundation to:
Discover which nodes can serve queries
Route queries only to healthy nodes
Handle node failures during query execution
Load balance queries across available nodes
✅ Success Criteria Checklist
[ ] Cluster Formation: Nodes discover each other within 10 seconds
[ ] Gossip Protocol: Information spreads to all nodes consistently
[ ] Health Checking: Node failures detected within 10 seconds
[ ] Phi Accrual: Adaptive failure detection working correctly
[ ] Failure Handling: Failed nodes marked consistently across cluster
[ ] Self-Healing: Cluster maintains operation despite node failures
[ ] Recovery: Nodes can rejoin cluster gracefully
[ ] Leader Integration: Failure triggers automatic re-election
[ ] Performance: HTTP endpoints provide cluster status information
[ ] Testing: System passes all automated tests
🚀 What You've Accomplished
With your self-healing cluster membership system complete, you now have:
Automatic node discovery and failure detection
Gossip-based information propagation with eventual consistency
Production-ready performance optimized for modern hardware
Integration points for leader election and distributed querying
Self-healing behaviors that maintain system availability
This is the same technology that powers production systems at Netflix, Cassandra, and other large-scale distributed platforms. You're not just learning concepts—you're building production-quality infrastructure.
🔮 Looking Forward
Tomorrow, we'll build the distributed query system that leverages this membership foundation to route queries intelligently across your cluster, handling failures gracefully and providing load balancing automatically.
Your distributed log processing system is becoming increasingly sophisticated and production-ready. The journey from basic distributed coordination to robust, self-healing clusters demonstrates the power of thoughtful system design and incremental complexity management.
Next in the series: Day 27: Build a distributed log query system across partitions
Happy building! 🚀
📂 Complete Implementation Package
The full implementation includes:
Source Code: Complete Python implementation with orjson optimization
Test Suite: Comprehensive unit and integration tests
Build Scripts: Automated setup, build, and verification scripts
Architecture Diagrams: Visual representations of system components
Performance Benchmarks: Validation scripts for production readiness
Download the complete package and start building your self-healing cluster today!