System design isn’t a whiteboard exercise.
In the real world, documentation is rare and no one hands you a manual. Stop memorizing the CAP theorem and start understanding how it dictates database choices. Bridge the gap between the interview and production. Build systems, don’t just draw them. Subscribe Now.
Picture this: You're running a massive restaurant chain with hundreds of locations. Each restaurant has its own way of writing orders—some use abbreviations, others write in full sentences, and some even use their own coding system. Now imagine trying to process all these orders centrally without knowing what format each one uses. Chaos, right?
This is exactly what happens in distributed log processing systems without a schema registry. Today, we're building the "menu translator" that ensures every log message follows a known, validated format before it enters our processing pipeline.
Why Schema Registry Matters in Real Systems
Companies like Confluent (Kafka's commercial arm) and LinkedIn built schema registries because they were drowning in format inconsistencies. When you're processing millions of log events per second from thousands of services, a single malformed message can crash your entire pipeline. The schema registry acts as a gatekeeper, ensuring only properly formatted data gets through.
System Context: Your Log Processing Architecture
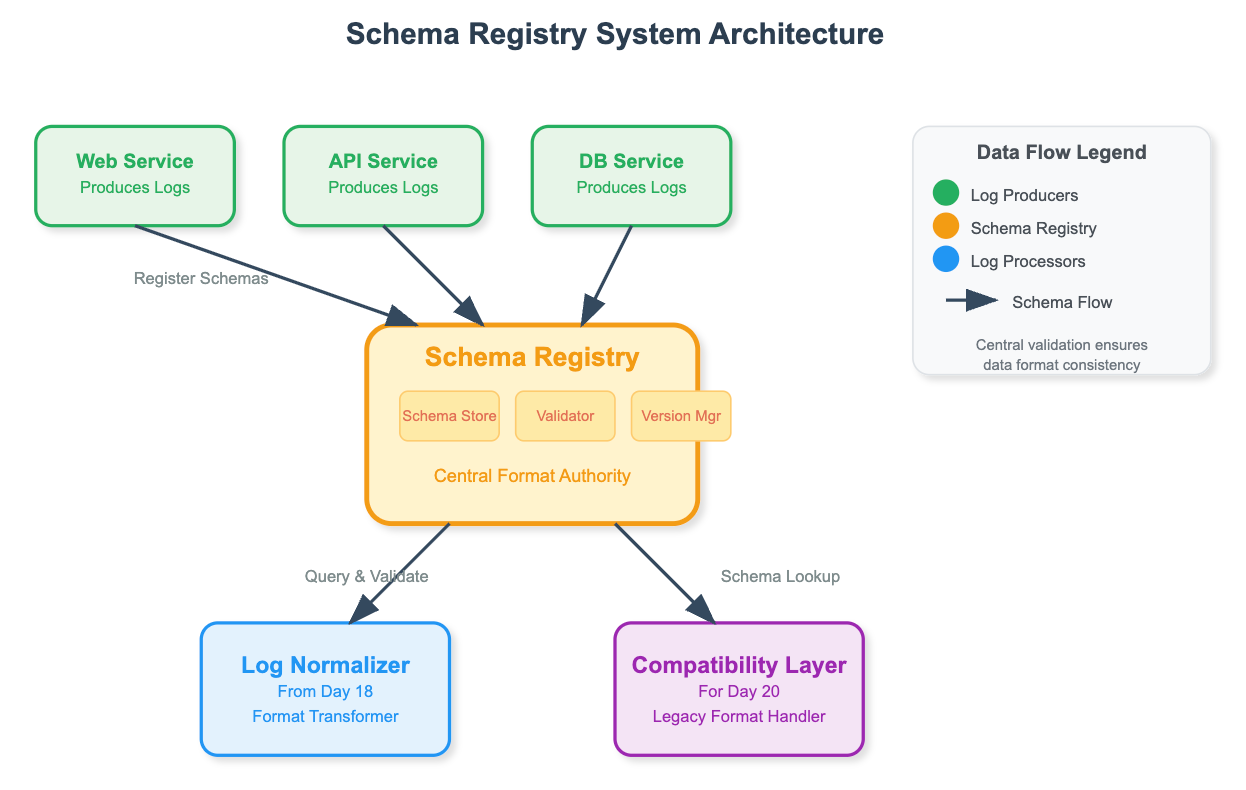
After yesterday's log normalization service, you now have a system that can transform between formats. But how does the normalizer know what format to expect? How do downstream services know what they're receiving? This is where our schema registry shines.
The schema registry sits at the heart of your system, serving as the single source of truth for all log formats. Every service registers its schemas here, and every log processor validates against these schemas before processing.
Component Architecture Deep Dive
Our schema registry follows a simple but powerful architecture:
Control Flow:
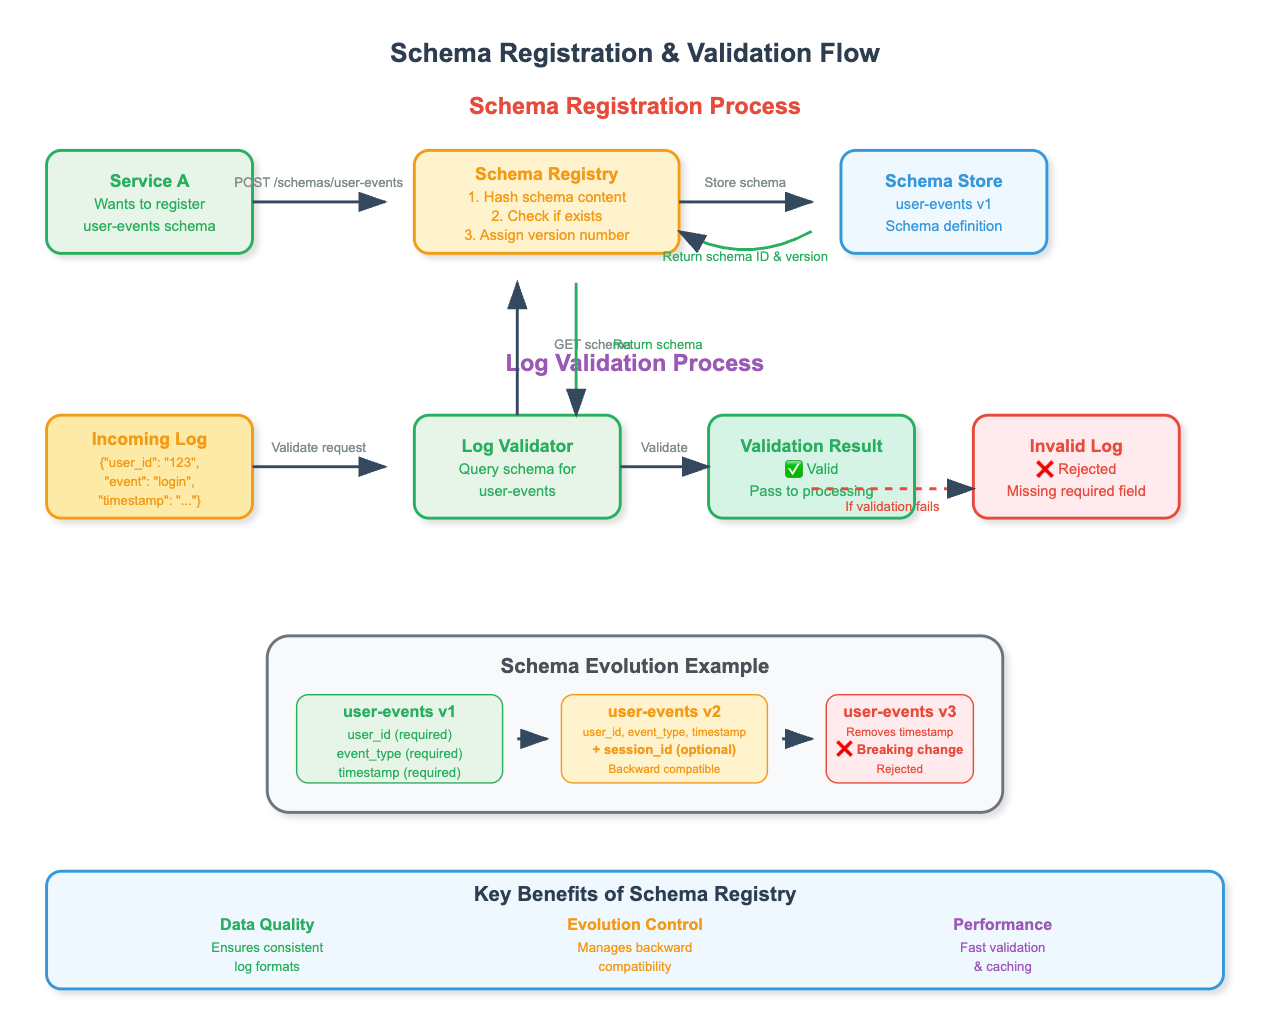
Services register their log schemas with versioning
Log processors query for schemas before processing
Validation happens at ingestion points
Schema evolution is managed centrally
Data Flow:
Schema definitions flow from services to registry
Validation rules flow from registry to processors
Format metadata flows between all components
Version compatibility information guides transformations
The registry maintains three critical data structures: the schema store (actual schema definitions), the version tracker (schema evolution history), and the compatibility checker (validation rules between versions).