
Yesterday, we built an A/B test analysis framework that compares experiment cohorts statistically. Today we shift perspective entirely — instead of comparing groups, we watch individual user journeys unfold through log data and surface the friction points that silently drive customers away.
What We’re Building Today
Parse raw application logs into structured user sessions
Compute CX metrics: page load time, error encounter rate, session abandonment, funnel completion
Build a Python 3.11 FastAPI backend that aggregates these metrics in real-time
React dashboard showing live CX health at a glance
Integrate cleanly into the log pipeline built across prior weeks
Why This Problem Is Hard
When Shopify’s checkout page added 300ms of latency during Black Friday 2021, it cost merchants millions before anyone noticed — because no single error fired. The signal was buried in the aggregate pattern of user sessions quietly abandoning mid-funnel. Standard error-rate monitoring saw nothing. Customer experience monitoring would have caught it in minutes.
Logs tell you what happened. CX monitoring tells you what the user experienced.
Core Concepts
Session Stitching — Log lines arrive with user IDs and timestamps but no session boundaries. We detect sessions by grouping events per user with a 30-minute inactivity timeout. This mirrors how Google Analytics and Amplitude define sessions.
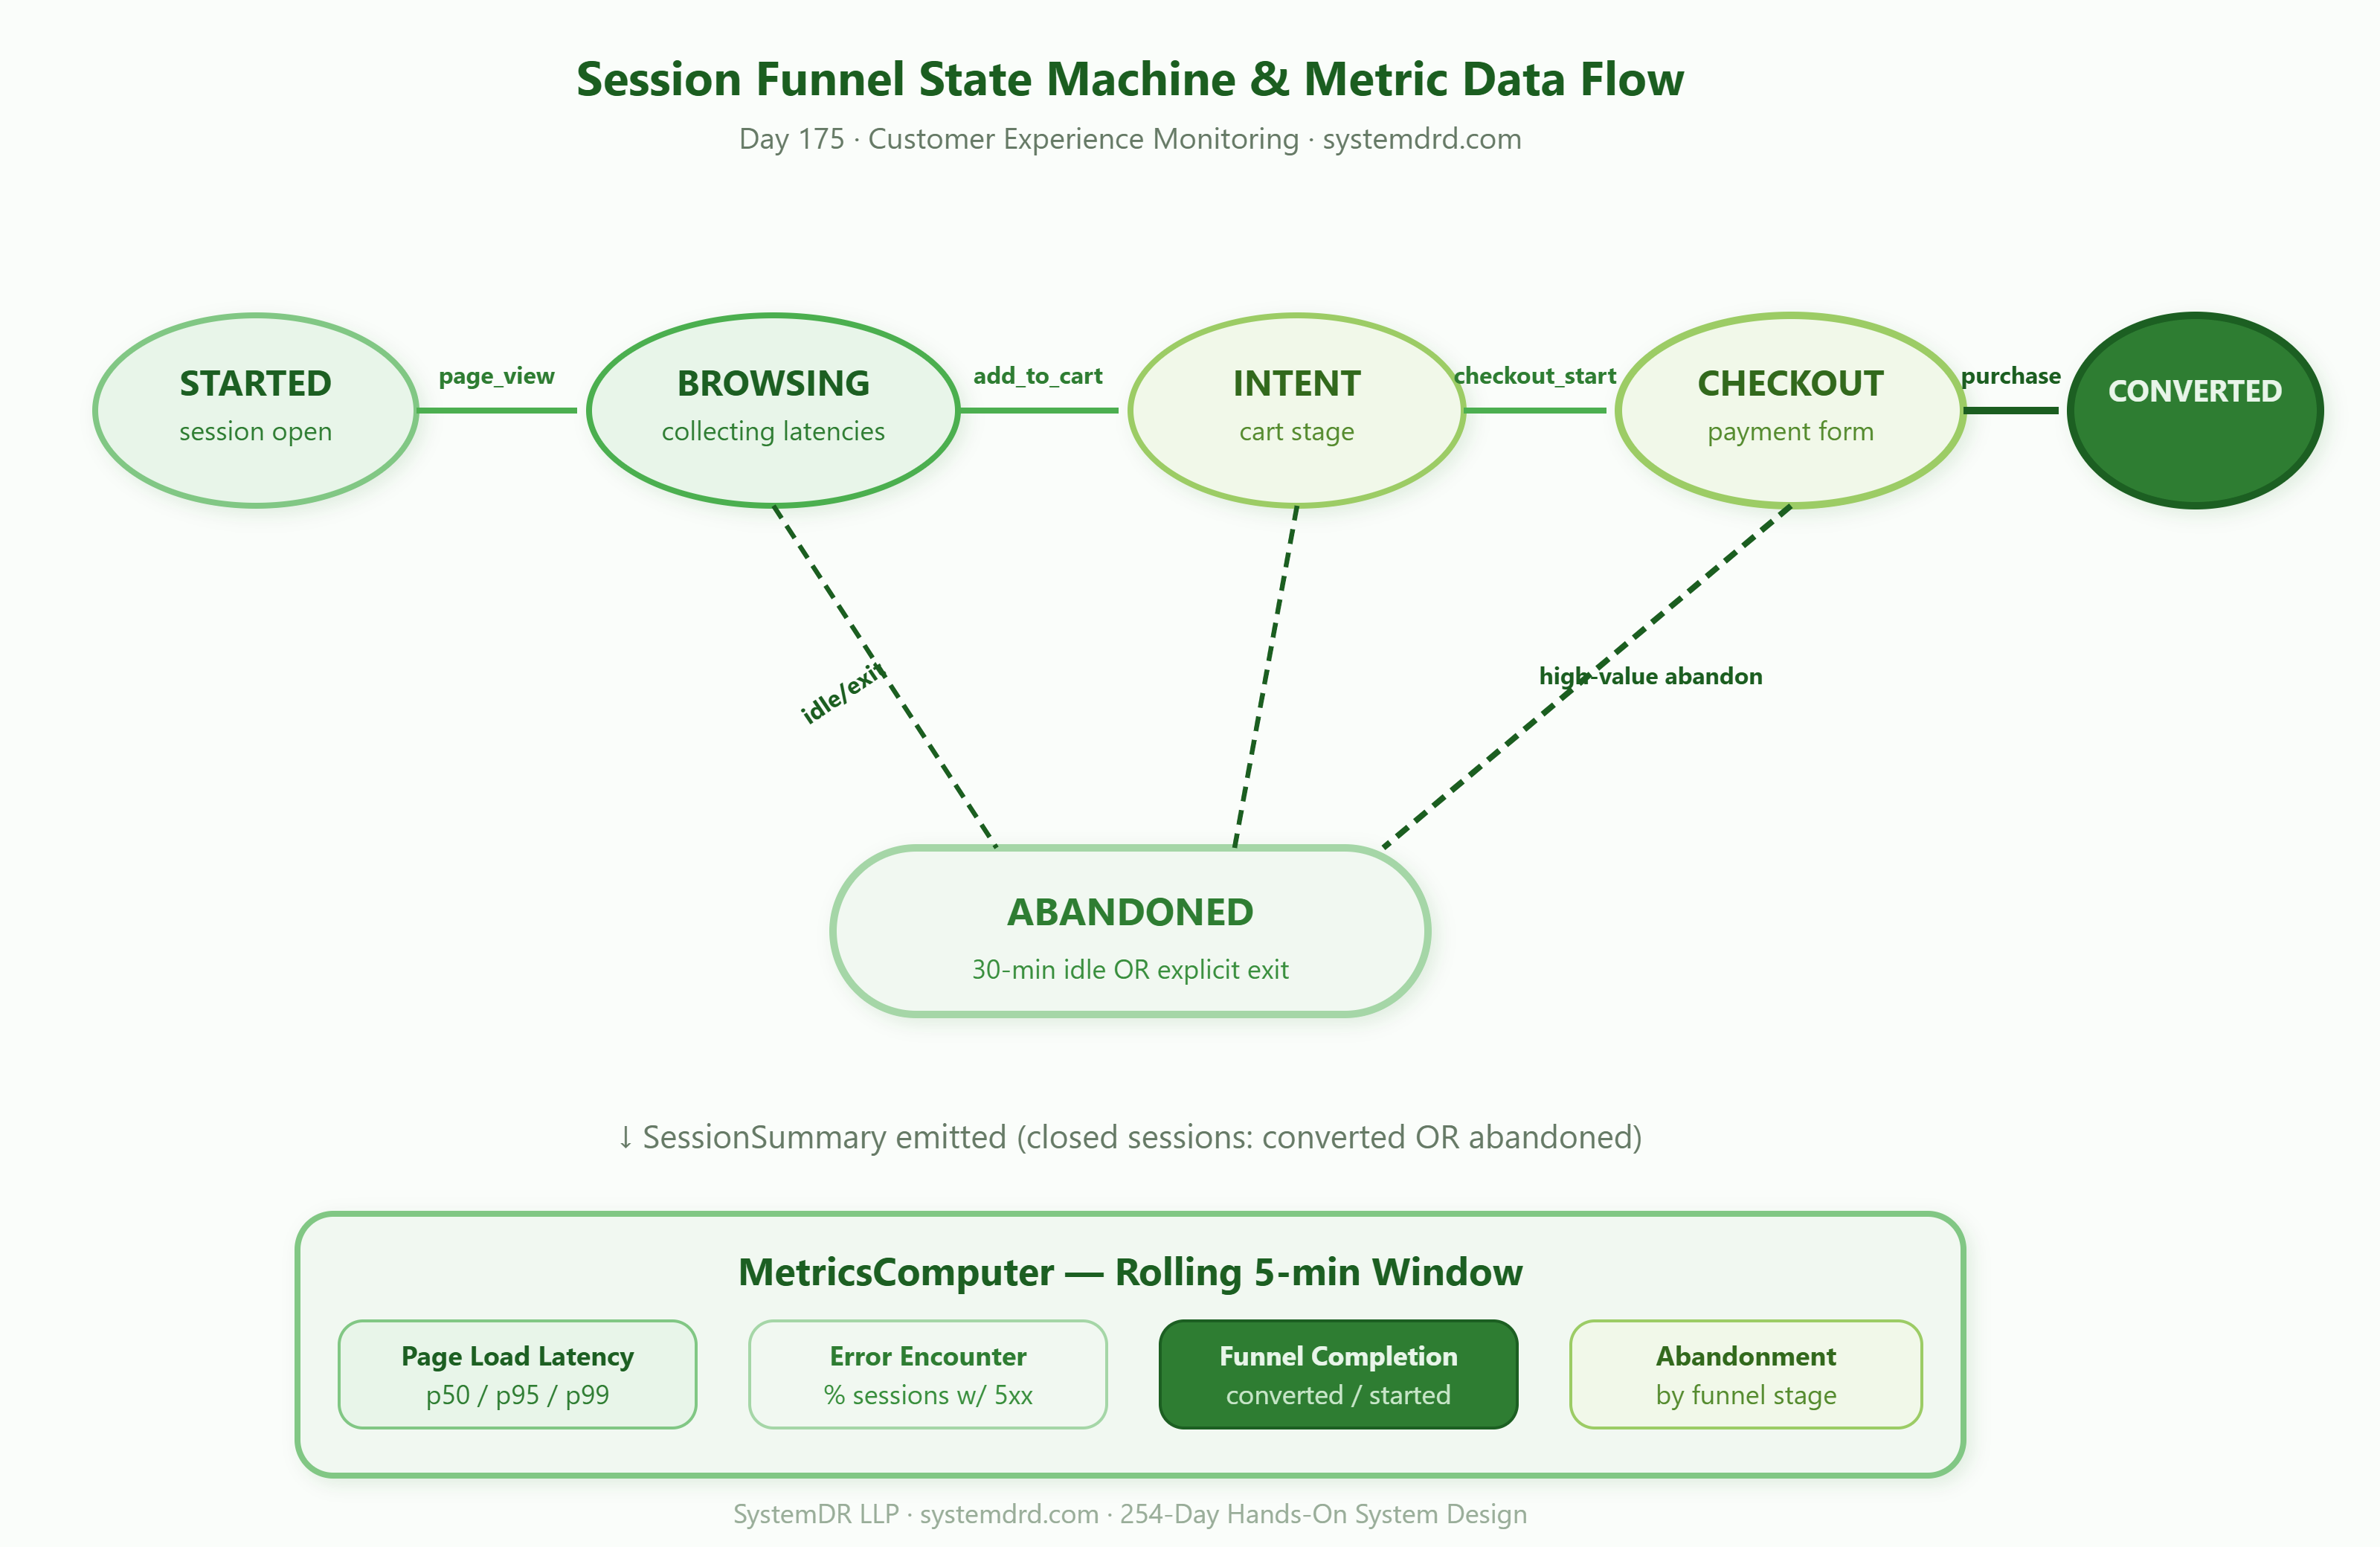
Funnel State Machine — Every product has a conversion funnel (e.g., landing → product_view → cart → checkout → purchase). We model this as a state machine where each log event advances or exits a session’s state. Abandoned sessions are those that entered but never exited through purchase.
Percentile Latency, Not Averages — Average page load time hides the 5% of users on slow connections who see 8-second loads. We compute p50, p90, p95, p99 — the same metrics Stripe and Cloudflare publish in their status pages.
Error Encounter Rate — The fraction of sessions that hit at least one 5xx or client-reported JS error. A healthy system keeps this under 0.5%. Amplitude’s engineering team found that users who encounter even one error have 3× the churn rate.
Architecture
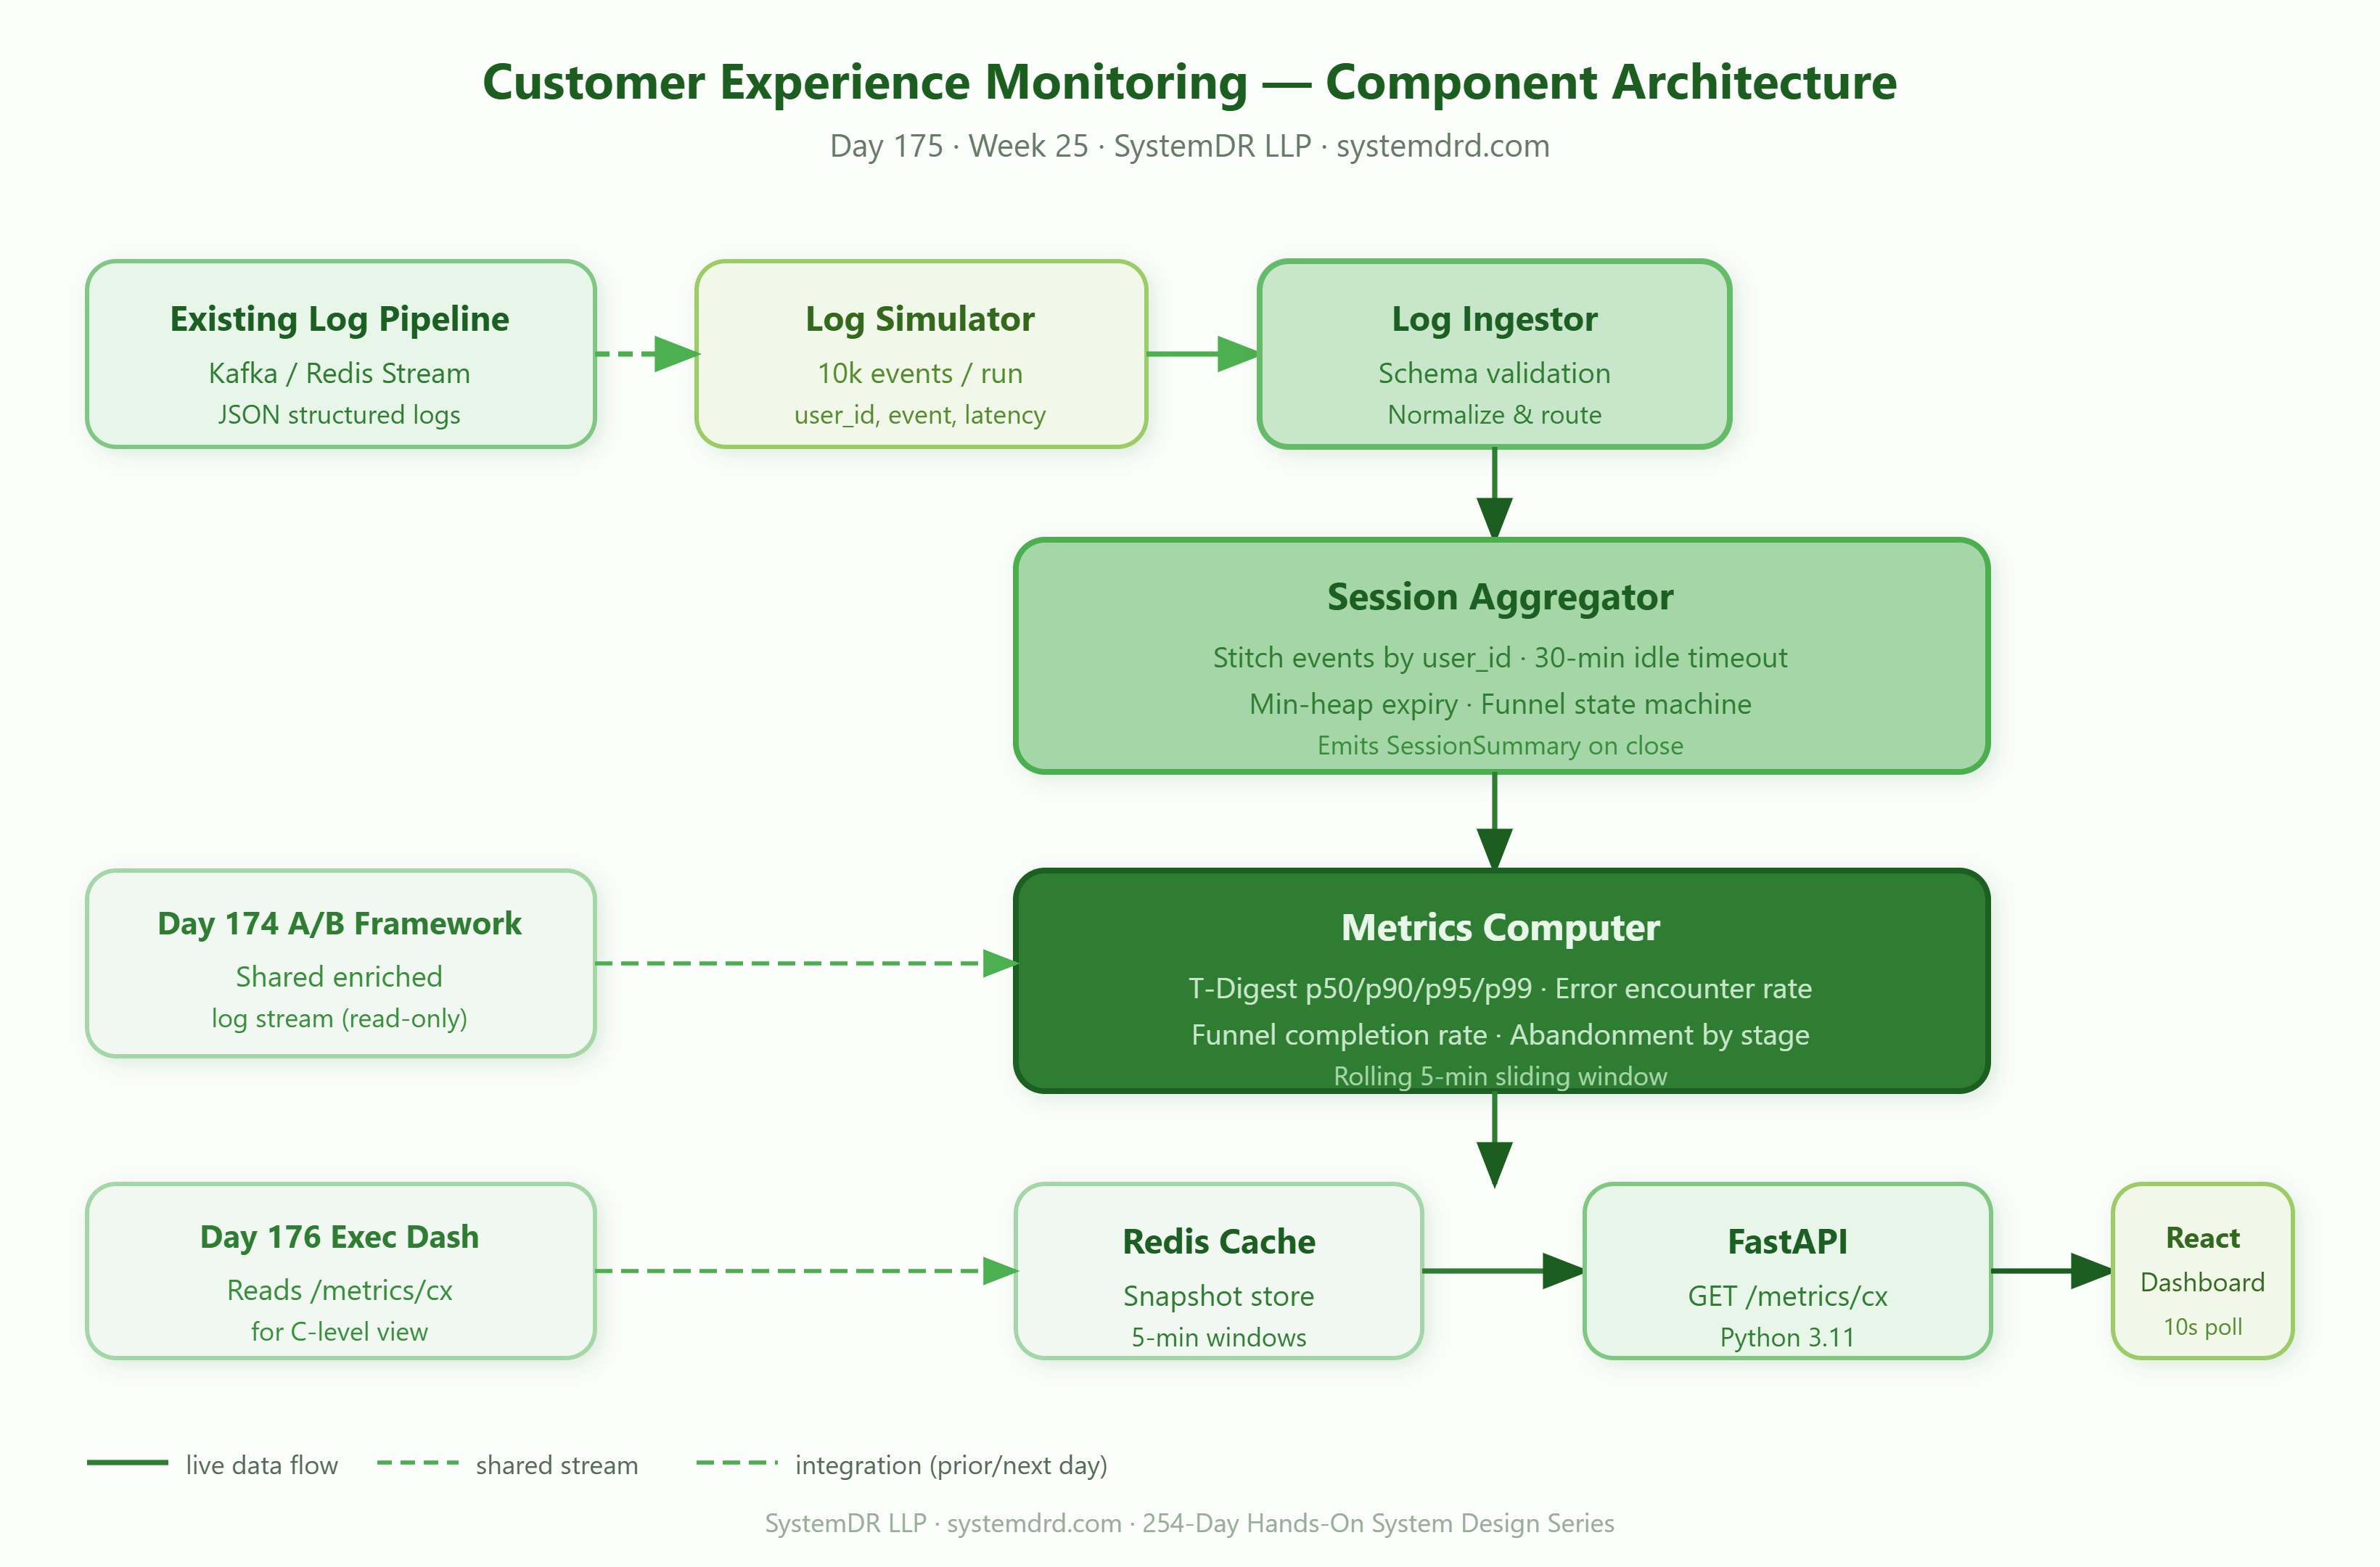
The system has three layers:
Ingestion Layer — A LogIngestor reads structured JSON logs from your existing pipeline (the Kafka/Redis stream from Week 5). Each log line carries: user_id, session_id, event_type, page, latency_ms, status_code, timestamp.
Computation Layer — A SessionAggregator maintains in-memory session windows per user. When a session closes (timeout or purchase), it emits a SessionSummary object. A MetricsComputer consumes summaries and updates rolling percentile buckets using a T-Digest algorithm — O(1) memory regardless of data volume.
Serving Layer — FastAPI exposes /metrics/cx returning the current CX health snapshot. React polls every 10 seconds and renders a dashboard with trend sparklines.
Data Flow
Raw Log Line
    → SessionAggregator (stitch by user_id + 30-min gap)
        → SessionSummary (funnel_stage, errors_seen, load_times[], completed)
            → MetricsComputer (rolling p50/p95/p99, error_rate, abandonment_rate)
                → Redis (5-min sliding window snapshots)
                    → FastAPI → React Dashboard
State transitions per session: STARTED → BROWSING → INTENT (cart) → CHECKOUT → CONVERTED or → ABANDONED at any stage.
Key Implementation Pieces
Session Aggregator — Keyed on user_id, emits session on 30-min idle or explicit session_end event. Uses a min-heap of expiry times to efficiently close stale sessions without scanning all active ones.
# Pseudo-code
class SessionAggregator:
    def ingest(self, log_line: dict) -> SessionSummary | None:
        session = self.active[log_line['user_id']]
        session.update(log_line)
        if session.is_expired() or log_line['event'] == 'session_end':
            return self.close(session)
T-Digest Percentile Tracker — A lightweight implementation of the T-Digest algorithm gives accurate percentile estimates with ~1KB of memory per metric. No need for heavy libraries.
Funnel Abandonment Detection — Each session carries its highest funnel stage reached. At close time, sessions that reached INTENT or CHECKOUT but not CONVERTED are flagged as high-value abandonments — the metric product teams care most about.
What the Dashboard Shows
Four metric cards: p95 Page Load, Error Encounter Rate, Funnel Completion Rate, Abandonment by Stage. A time-series sparkline for each updates every 10 seconds. Color thresholds turn cards amber/red when metrics breach SLO bounds — the same pattern Datadog uses for its SLO widgets.
Real-World Grounding
Amazon’s CX team famously measured that 100ms of added latency reduced revenue by 1%. Their monitoring pipeline is exactly this: session stitching from distributed logs → funnel analysis → real-time dashboards — all derived from logs, not from invasive client-side tracking that users block.
Integration with Week 25
This module consumes the same enriched log stream the A/B framework (Day 174) reads from. Tomorrow (Day 176), your executive dashboard will pull directly from the /metrics/cx endpoint you build today — giving C-level stakeholders a one-pager built on the same underlying data.
Github Link:
https://github.com/sysdr/course-p/tree/main/day175/day175_cx_monitoring
Implementation Guide Step-to-Step
Prerequisites
Python 3.10+ (
python3orpython3.11).pipinside a virtual environment (recommended).
Optional:
Docker and Docker Compose Plugin for containerized runs.
Install and run (local)
From this directory (day175_cx_monitoring/):
python3 -m venv .venv
source .venv/bin/activate
pip install -r requirements.txt
Start the API and dashboard:
uvicorn src.api.server:app --host 0.0.0.0 --port 8175Or use helpers (creates venv if needed, installs deps, runs tests, starts server):
chmod +x start.sh stop.sh cleanup.sh   # once
./start.sh
Stop:
./stop.sh
URLs:
Dashboard and API root:
http://localhost:8175/
Metrics JSON: http://localhost:8175/metrics/cx
Health: http://localhost:8175/health
Tests
source .venv/bin/activate
python -m pytest tests/ -v --tb=short
Dependencies for tests (pytest, pytest-asyncio, httpx) are listed in requirements.txt.
Docker
From docker/ (Compose build context is the project root):
cd docker
docker compose up --build
The service listens on host port 8175 mapped to container port 8175.
Tear down and Docker cleanup
./cleanup.shThis stops the local HTTP service, brings down this project’s Compose stack (removes local images built for cx-monitor), and runs non-destructive docker ... prune -f cleanups.
To also remove all unused Docker images globally (including non-dangling):
DOCKER_PRUNE_ALL_UNUSED_IMAGES=1 ./cleanup.shRemove local Python/ephemeral artefacts yourself when needed (rm -rf .venv .pytest_cache, delete *.pyc / __pycache__); see .gitignore for what should stay out of version control.
Success Criteria
By end of day, your system should:
Correctly stitch 10,000 simulated log events into sessions
Compute p95 load time within 2% of true value
Show abandonment rate broken down by funnel stage in the React dashboard
Handle new log lines with < 5ms processing latency per event
Your mission: build the monitoring layer that turns a wall of log lines into the user story your product team actually needs to make decisions.
Working Code Demo:
Next: Day 176 — Building executive dashboards that surface these CX metrics alongside infrastructure health for C-level views