
Lesson Agenda
What you will build by the end of today:
A Revenue Impact Analyzer that ingests system-event logs and transaction logs in parallel
A Correlation Engine that maps error spikes, latency surges, and downtime windows to revenue drops
A Statistical Significance Layer that separates real causation signals from noise using Pearson correlation
A React Dashboard showing dual timelines, a correlation heatmap, impact score cards, and a 7-day incident history table
How this lesson fits: Day 171 built the conversion funnel visualizer that shows where users drop off. Today you wire system health directly to money — turning that same log stream into a revenue early-warning system. Day 173 uses this same pipeline foundation to track feature adoption rates.
Lesson flow:
Why this matters and what the real-world problem looks like
Core concept — Temporal Correlation Analysis (three stages)
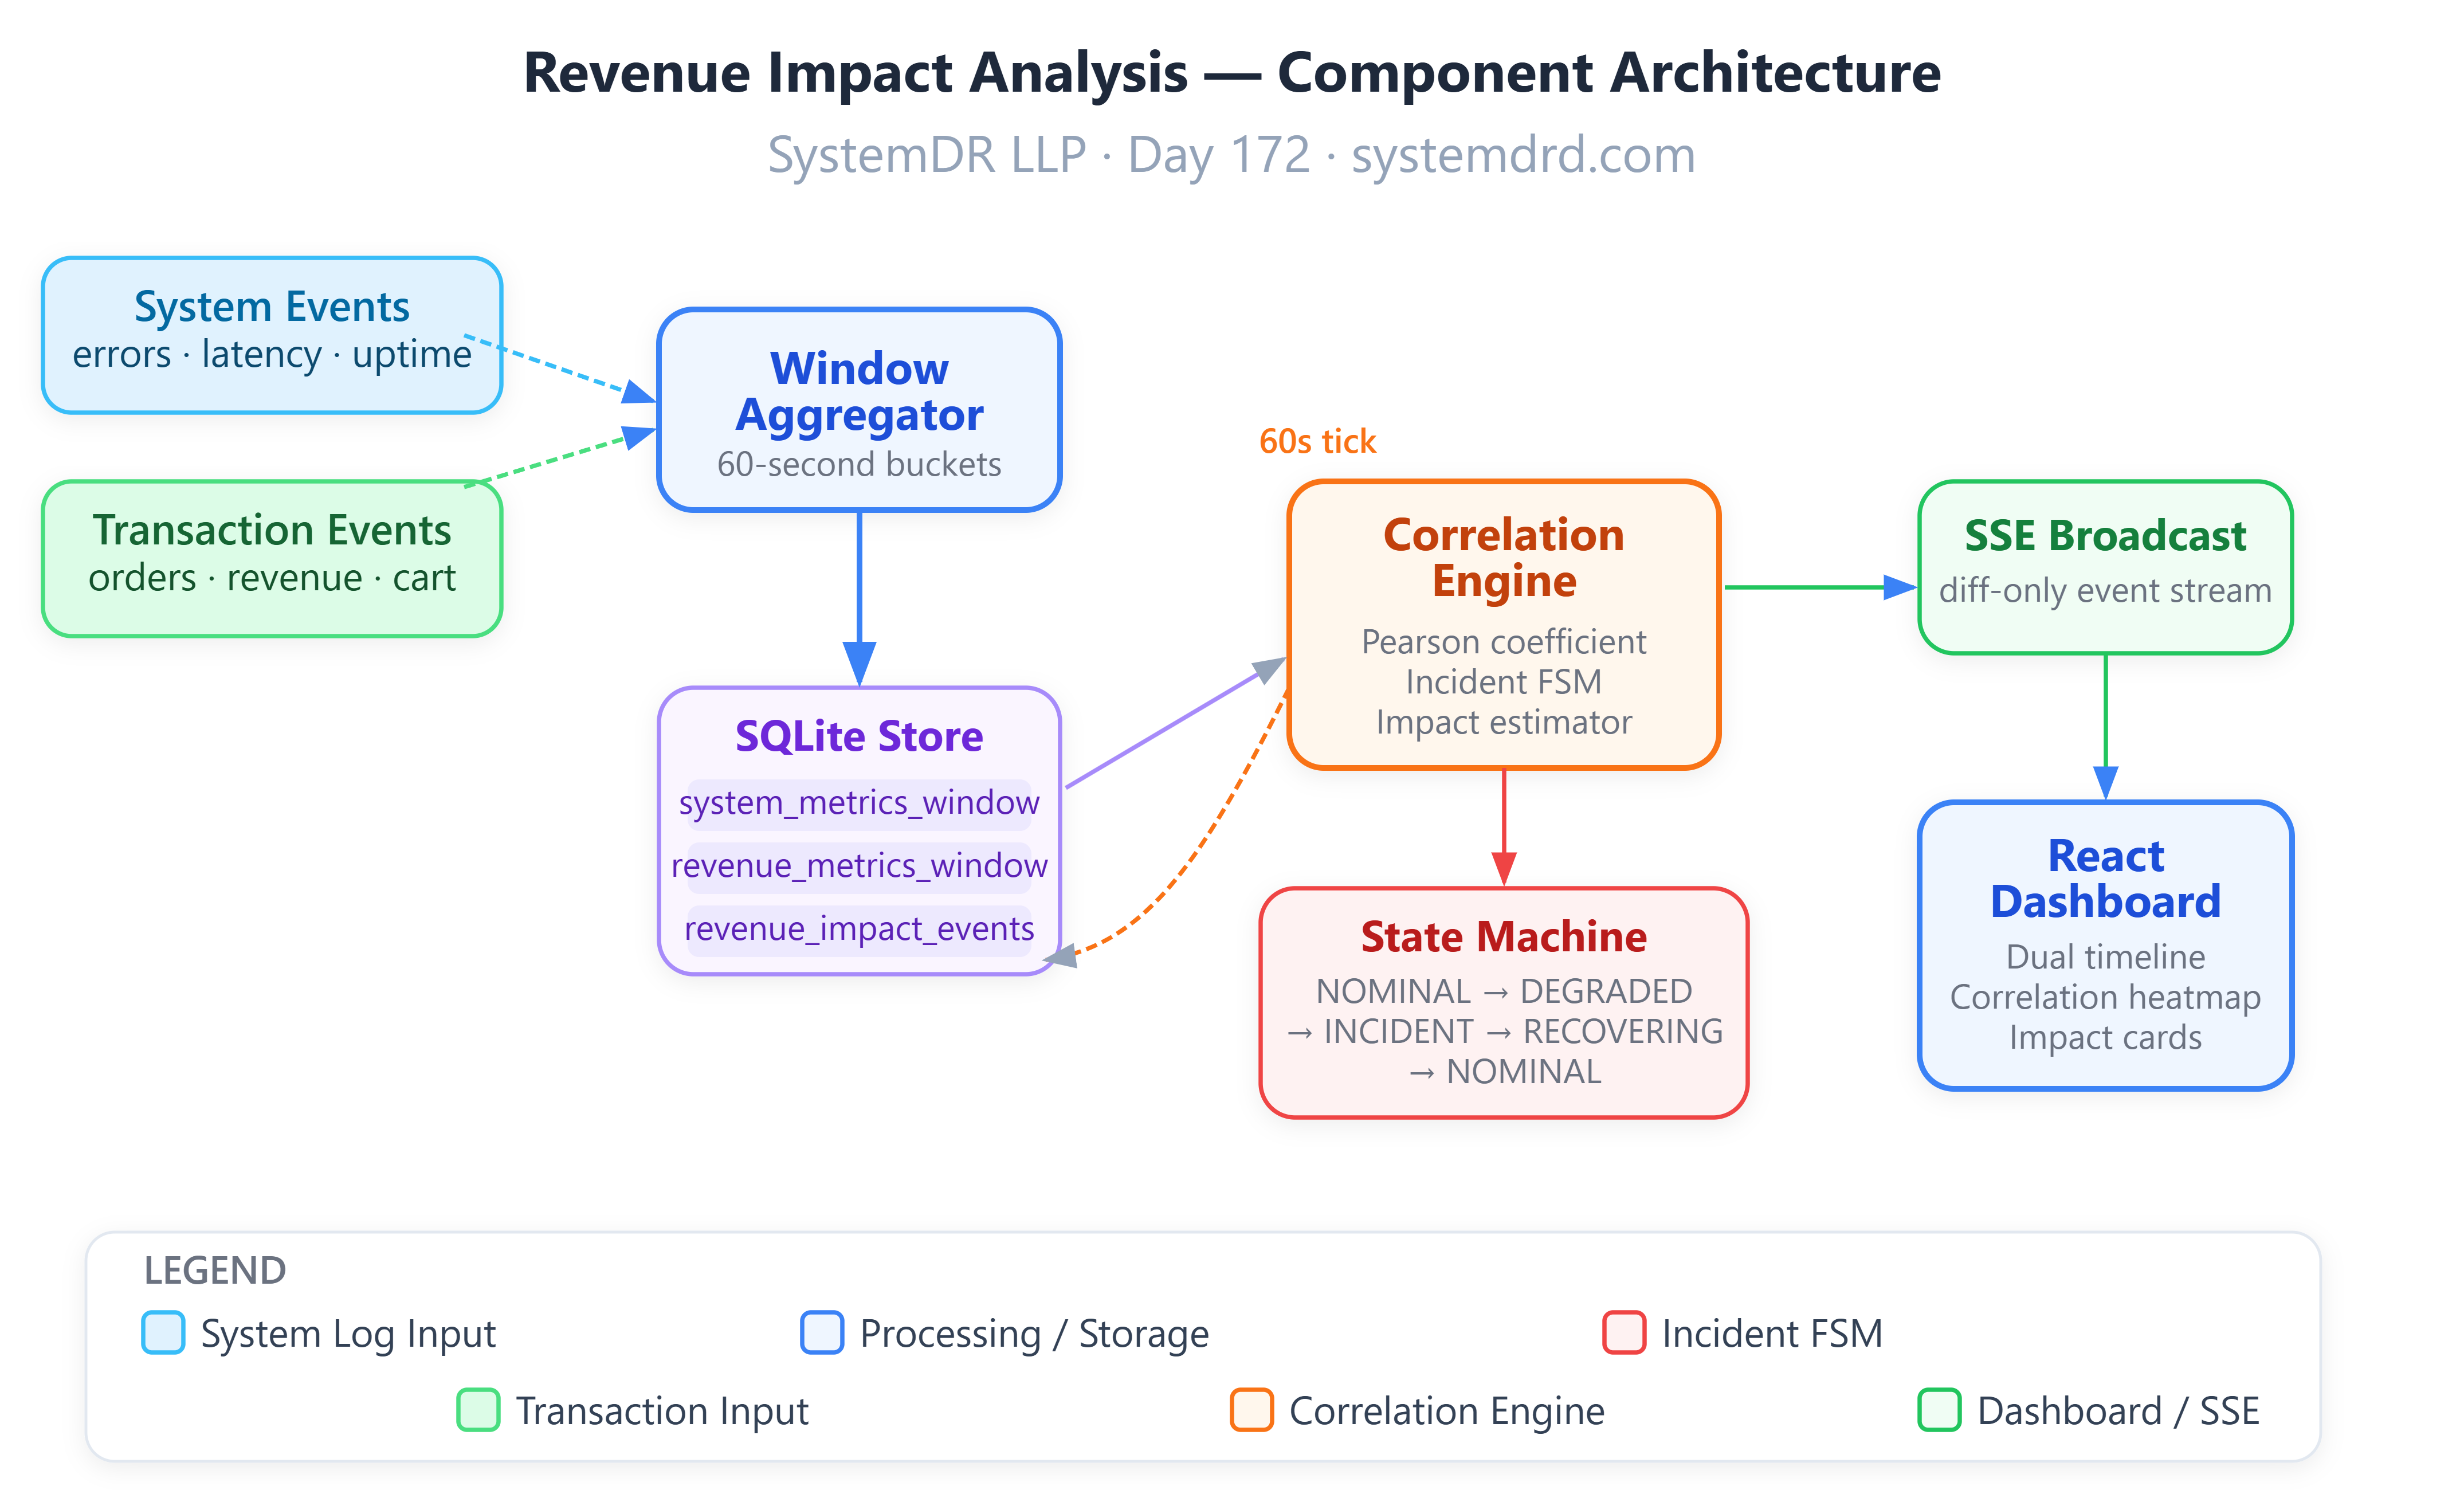
Component architecture and data flow
Key implementation details — what makes this production-grade
Project setup and environment
Building each component step by step
Running unit tests
Demo walkthrough — triggering an incident and watching the dashboard respond
Verification checklist
Assignment — multi-service cascade detection
Why This Matters
Most teams discover revenue damage hours after an incident closes — when the finance team runs the next-day report. Stripe’s reliability engineering revealed that a single 500ms added to checkout latency costs measurable conversion points at their transaction volumes. Shopify found that during their 2021 Black Friday incidents, correlating error logs to order-creation failures in near real-time allowed them to prioritize incident response by dollar impact rather than by engineering intuition.
The insight that unlocks this: your distributed log stream already contains both signals. System errors and transaction events flow through the same pipeline. You just haven’t joined them yet.
Real-World Reference
Amazon documented the 100ms latency = 1% sales drop relationship — this is now the foundation of every latency SLO tied to business outcomes. Netflix weights incident escalation by estimated subscriber impact, not raw error counts. Cloudflare’s on-call playbook ranks alerts by revenue-correlation score, not error volume.
Core Concept: Temporal Correlation Analysis
The system works in three stages. Each stage builds on the previous one, so understand stage one before moving to stage two.
Stage 1 — Event Segmentation
Logs are bucketed into fixed 60-second windows. Each bucket accumulates error counts, P95 latency, and service availability per microservice. Transaction logs contribute order counts, revenue totals, and cart abandonment events into the same window. The 60-second window is deliberately short — short enough to detect incidents fast, long enough to avoid one-off spikes creating false alarms.
Stage 2 — Pearson Correlation
For each system metric — for example, payment-service error rate — the system calculates its Pearson correlation coefficient against revenue rate across a rolling 24-hour window. Here is what the score means:
Below −0.6 — Strong signal. When this metric worsens, revenue reliably drops.
Between −0.3 and −0.6 — Moderate signal. Flag for investigation.
Above −0.3 — Noise. Not actionable on its own.
Pearson correlation is computed with Python’s built-in statistics.correlation(), which ships with the standard library since Python 3.10. No NumPy, no SciPy, no external packages. The system requires at least 10 aligned data points before emitting a score, which prevents false readings on sparse windows.
Stage 3 — Impact Scoring
When an incident window is detected (error rate above threshold for two or more consecutive buckets), the engine compares revenue-per-minute during the incident against the baseline. Baseline is the same hour of day over the past 7 days, averaged. This handles time-of-day and day-of-week seasonality automatically — no ML model needed. The difference becomes the estimated revenue impact.
Architecture
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
