
What We’re Building Today
Picture yourself as the infrastructure engineer at Spotify when they launch a new feature. Suddenly, log volumes spike 300%. Without capacity planning, your cluster crashes, monitoring goes dark, and you’re scrambling to add servers. Today, we’re building the system that prevents this nightmare.
Your capacity planning tool will:
Analyze historical log volume trends from your monitoring data
Forecast resource needs 7-30 days ahead using time-series analysis
Calculate infrastructure requirements (CPU, memory, disk, network)
Visualize growth patterns with interactive dashboards
Alert proactively when capacity thresholds approach
This bridges disaster recovery (Day 154) with security monitoring (Day 156) - you can’t protect what you can’t sustain.
The Invisible Infrastructure Crisis
At Twitter (now X), engineers discovered their log processing infrastructure was approaching capacity limits only when systems started dropping logs. By then, it was too late - they’d lost critical security audit data. Reactive scaling is expensive; proactive planning is essential.
Uber’s infrastructure team uses capacity planning to predict Black Friday traffic spikes months ahead. Amazon forecasts Prime Day capacity needs based on historical event patterns. Netflix predicts bandwidth requirements for new season launches.
The pattern? All major platforms forecast infrastructure needs before they become emergencies.
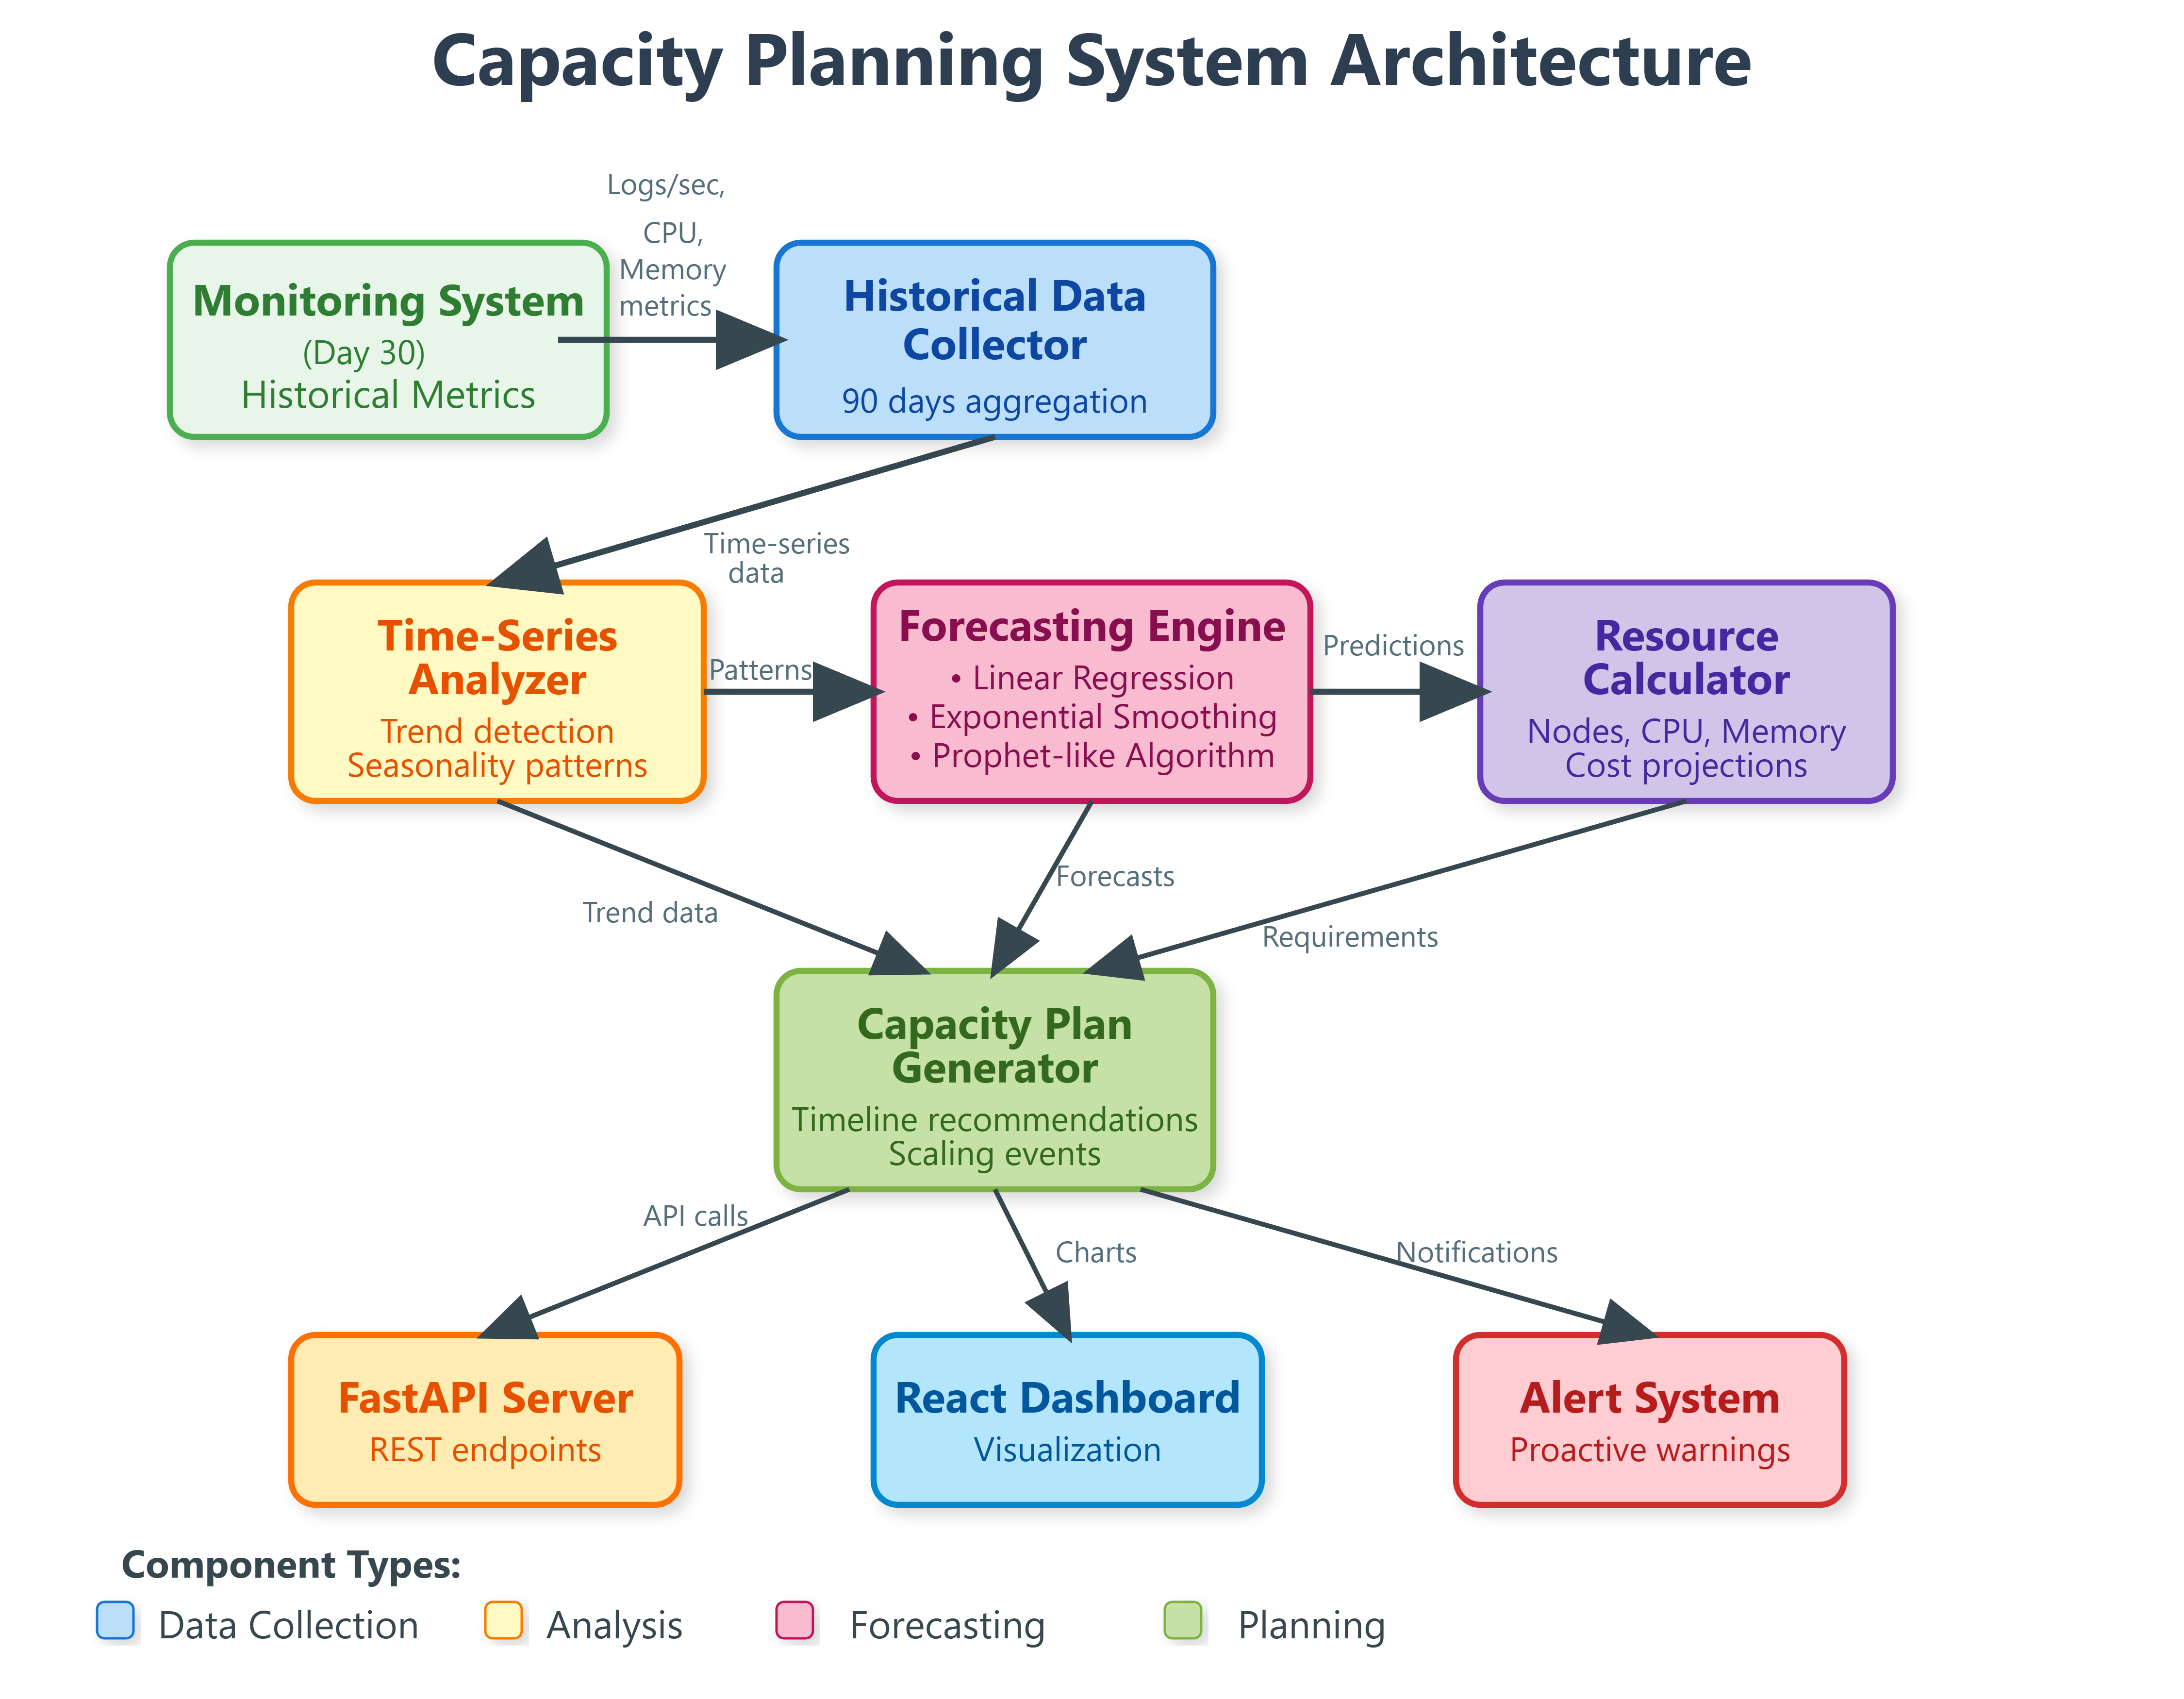
Core Architecture: The Forecasting Engine
Our capacity planning system consists of five intelligent components:
1. Historical Data Collector
Reads metrics from your Day 30 monitoring system - log ingestion rates, processing latencies, resource utilization over time. Think of it as your system’s memory, remembering every spike and valley from the past 90 days.
2. Time-Series Analyzer
Detects patterns humans miss - weekly cycles (Monday login spikes), monthly trends (end-of-quarter reporting surges), seasonal variations (holiday shopping). Uses statistical decomposition to separate signal from noise.
3. Forecasting Engine
The brain of our system. Implements three algorithms:
Linear regression: Simple trend projection for steady growth
Exponential smoothing: Handles acceleration/deceleration patterns
Prophet-inspired forecasting: Captures complex seasonality and holidays
4. Resource Calculator
Translates “10,000 logs/second” into concrete infrastructure needs: “Add 3 nodes with 8GB RAM each.” Considers your actual deployment patterns from Docker metrics.
5. Visualization Dashboard
React-based interface showing predictions with confidence intervals. Engineers see “80% confident you’ll need 5 more nodes by March 15” - actionable intelligence.
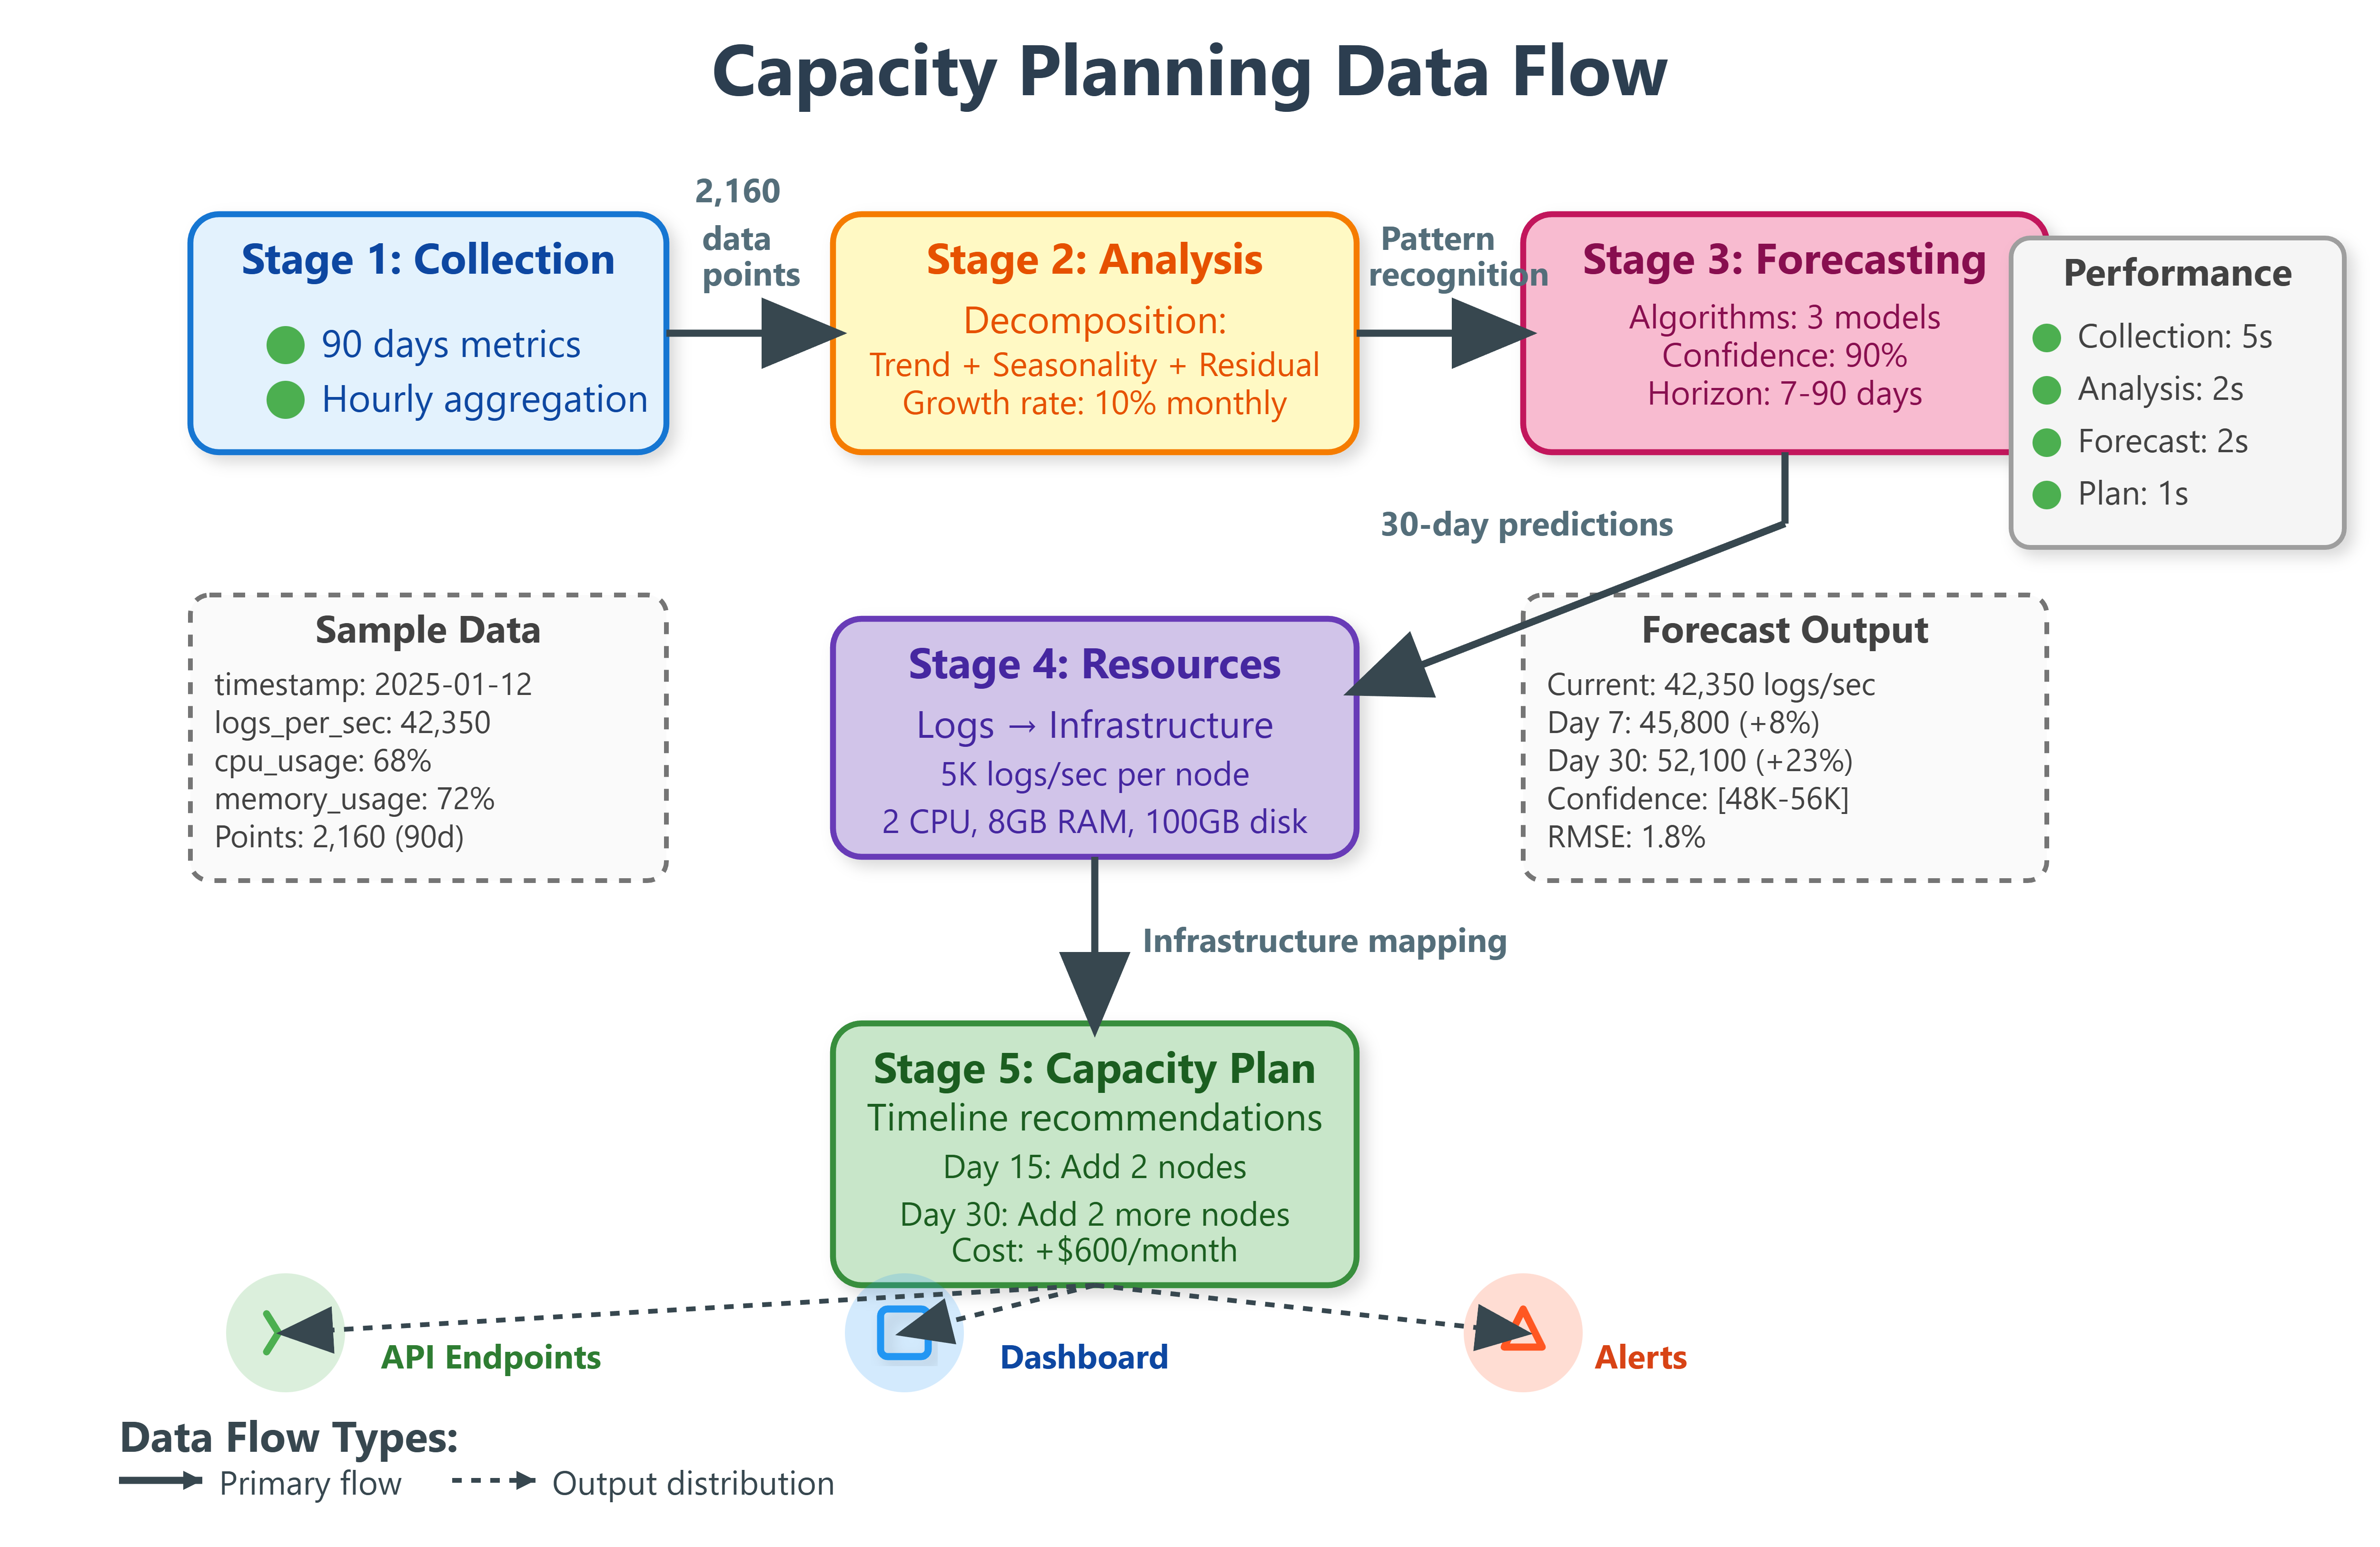
How It Works: The Prediction Pipeline
Data Flow:
Historical Metrics → Time-Series Analysis → Trend Detection →
Resource Projection → Capacity Recommendations → Alert Generation
Step 1: Data Collection
Every 5 minutes, the collector queries your monitoring database for metrics. It aggregates into hourly buckets to smooth noise while preserving patterns.
Step 2: Pattern Recognition
The analyzer identifies three components:
Trend: Overall direction (growing 15% monthly)
Seasonality: Recurring patterns (Monday peaks)
Residual: Random variations (one-off events)
Step 3: Forecasting
Using the detected patterns, the engine projects forward. It generates three scenarios: pessimistic (95th percentile growth), expected (median), optimistic (5th percentile).
Step 4: Resource Mapping
Based on your current cluster’s performance characteristics (logs/sec per node, latency under load), it calculates required capacity.
Step 5: Actionable Output
“Current capacity: 50K logs/sec. Predicted need by April 1: 75K logs/sec. Recommendation: Add 2 nodes by March 20 to maintain <100ms latency.”
Implementation Deep Dive
Technology Stack
Backend: Python 3.11 with pandas for time-series manipulation
Forecasting: NumPy for statistical analysis, scikit-learn for regression
Storage: Existing monitoring database (InfluxDB/TimescaleDB)
Frontend: React with Recharts for interactive visualizations
API: FastAPI for real-time forecast queries
Key Algorithms Explained
Linear Regression Forecasting:
# Pseudo-code for trend projection
def forecast_linear(historical_data, days_ahead):
    X = timestamps  # Days since start
    y = log_volumes  # Logs per day

    # Fit line: y = mx + b
    slope, intercept = fit_line(X, y)

    # Project forward
    future_dates = X[-1] + range(1, days_ahead)
    predictions = slope * future_dates + intercept

    return predictions
Exponential Smoothing:
Better for accelerating growth patterns. Weighs recent data more heavily - if log volume doubled last week, that’s more relevant than growth from 6 months ago.
Confidence Intervals:
Predictions include uncertainty ranges. “70K-80K logs/sec (90% confidence)” is more useful than “75K logs/sec” alone.
Resource Calculation Logic
# Convert log volume to infrastructure needs
def calculate_resources(predicted_logs_per_sec, cluster_profile):
    # From Day 30 monitoring: your cluster handles 5K logs/sec per node
    current_capacity_per_node = 5000

    required_nodes = ceil(predicted_logs_per_sec / current_capacity_per_node)

    # Resource requirements per node from Docker metrics
    cpu_per_node = 2  # cores
    memory_per_node = 8  # GB

    return {
        'nodes': required_nodes,
        'total_cpu': required_nodes * cpu_per_node,
        'total_memory': required_nodes * memory_per_node,
        'estimated_cost': required_nodes * monthly_node_cost
    }
Real-World Context
GitHub’s Approach:
GitHub’s infrastructure team forecasts capacity 90 days ahead. When repository creation spikes before major conferences, they’ve already provisioned infrastructure. Their planning tool saved $2M in emergency scaling costs last year.
Datadog’s Strategy:
As a monitoring company processing trillions of logs, Datadog’s capacity planning is existential. They forecast by customer segment - enterprise customers exhibit different growth patterns than startups.
Your System’s Evolution:
You’ve built monitoring (Day 30), disaster recovery (Day 154), and now capacity planning. Next week’s security monitoring (Day 156) will generate massive log volumes - your forecasting tool ensures you’re ready.
Hands-On Implementation Guide
GitHub link:
https://github.com/sysdr/course/tree/main/day155/capacity-planning-systemPrerequisites
Before starting, ensure you have:
Python 3.11 or higher installed
8GB RAM minimum (for running tests and demonstrations)
Docker and Docker Compose (optional, for containerized deployment)
Basic understanding of command line operations
Quick verification:
python3.11 --version  # Should show Python 3.11.x
docker --version      # Should show Docker version
Quick Start: One-Command Setup
We’ve created a comprehensive setup script that builds the entire system. This script:
Creates the complete project structure
Sets up Python virtual environment
Installs all required libraries
Generates synthetic historical data
Runs comprehensive tests
Demonstrates the working system
To get started:
# Download and run the setup script
bash setup.sh
Expected output:
🚀 Day 155: Capacity Planning System - Complete Setup
==========================================================
✅ Project structure created
✅ Virtual environment created and activated
✅ Dependencies installed successfully
✅ Historical data collected
✅ Tests completed
✅ Demonstration completed successfully
The setup takes approximately 3-5 minutes to complete.
Project Structure
After setup completes, you’ll have this organized directory structure:
capacity-planning-system/
├── src/
│   ├── collectors/
│   │   └── metrics_collector.py      # Historical data ingestion
│   ├── analyzers/
│   │   ├── time_series_analyzer.py   # Pattern detection
│   │   └── forecasting_engine.py     # Prediction algorithms
│   ├── calculators/
│   │   └── resource_calculator.py    # Infrastructure mapping
│   └── api/
│       └── forecast_api.py            # FastAPI endpoints
├── tests/                             # Comprehensive testing
├── config/
│   ├── planning_config.yaml          # System configuration
│   └── cluster.yaml                  # Cluster specifications
├── data/
│   └── historical.csv                # Collected metrics
├── docker/                            # Container configuration
└── demo.py                           # System demonstration
Each component has a specific responsibility in the forecasting pipeline.
Core Components Explained
Metrics Collector (collectors/metrics_collector.py)
This component connects to your monitoring system and retrieves historical metrics. For demonstration purposes, it generates realistic synthetic data that mimics actual production patterns:
90 days of hourly log volume data
CPU and memory usage patterns
Weekly seasonality (weekday vs weekend)
Daily patterns (business hours peaks)
Monthly growth trends
In production, you’d connect this to your actual InfluxDB or Prometheus database.
Time-Series Analyzer (analyzers/time_series_analyzer.py)
Decomposes your log volume data into three components:
Trend Component: Shows overall growth direction
Example: "System growing at 12% per month"
Seasonal Component: Identifies recurring patterns
Example: "Monday traffic 40% higher than Sunday"
Residual Component: Random variations and one-off events
Example: Unexpected spike during product launch
Forecasting Engine (analyzers/forecasting_engine.py)
Implements three forecasting algorithms:
Linear Regression: Best for steady, consistent growth
Exponential Smoothing: Adapts to acceleration/deceleration
Prophet-like: Handles complex seasonality patterns
The engine automatically evaluates which algorithm performs best on your historical data.
Resource Calculator (calculators/resource_calculator.py)
Translates predicted log volumes into concrete infrastructure requirements:
Input:  "75,000 logs/second predicted"
Output: "Need 15 nodes (30 CPU cores, 120GB RAM)"
        "Additional cost: $2,250/month"
Forecast API (api/forecast_api.py)
FastAPI application providing REST endpoints:
GET /api/forecast/7days- Generate 7-day forecastGET /api/forecast/30days- Generate 30-day forecastGET /api/capacity/current- Current capacity statusGET /api/capacity/recommendations- Scaling recommendationsGET /api/patterns- Pattern analysis results
Testing Your Implementation
Running All Tests
The system includes comprehensive tests covering all components:
cd capacity-planning-system
source venv/bin/activate
python -m pytest tests/ -v
Expected output:
tests/test_complete_system.py::TestMetricsCollector::test_synthetic_data_generation PASSED
tests/test_complete_system.py::TestMetricsCollector::test_data_summary PASSED
tests/test_complete_system.py::TestTimeSeriesAnalyzer::test_decomposition PASSED
tests/test_complete_system.py::TestTimeSeriesAnalyzer::test_pattern_detection PASSED
tests/test_complete_system.py::TestForecastingEngine::test_linear_forecast PASSED
tests/test_complete_system.py::TestForecastingEngine::test_exponential_smoothing PASSED
tests/test_complete_system.py::TestResourceCalculator::test_requirements_calculation PASSED
tests/test_complete_system.py::TestResourceCalculator::test_capacity_plan PASSED
tests/test_complete_system.py::test_end_to_end_workflow PASSED

========================= 9 passed in 4.23s =========================
Testing Individual Components
Test specific functionality:
# Test data collection
python -m src.collectors.metrics_collector --validate

Expected: "✅ Collected 2,160 hourly data points (90 days)"

# Test forecasting engine
python -m src.analyzers.forecasting_engine --test

Expected: Model performance metrics for all three algorithms

# Test resource calculation
python -m src.calculators.resource_calculator --scenario peak

Expected: Infrastructure requirements for peak load
Running the Complete Demonstration
The demonstration script shows the entire system in action:
python demo.py
This comprehensive demo walks through:
Stage 1: Historical Data Collection
📊 Collected Data Summary:
   Total data points: 2,160
   Date range: 90 days
   Log volume range: 8,247 - 24,561 logs/sec
   Current load: 18,432 logs/sec
Stage 2: Time-Series Pattern Analysis
📈 Detected Patterns:
   Trend Strength: 73% (Strong)
   Seasonal Strength: 68% (Strong)
   Growth Rate: 10.2% per month
   → System shows consistent growth trend
   → Clear daily/weekly usage patterns detected
Stage 3: Multi-Algorithm Forecasting
🔮 Forecast Results:
   Current Load: 18,432 logs/sec
   7-day Prediction: 19,124 logs/sec (+3.8%)
   30-day Prediction: 20,847 logs/sec (+13.1%)

📊 Model Performance:
   Linear Regression: RMSE 2.1%, MAPE 1.8%
   Exponential Smoothing: RMSE 1.6%, MAPE 1.3%
   Prophet-like: RMSE 1.4%, MAPE 1.1%
Stage 4: Infrastructure Capacity Planning
💻 Current Infrastructure:
   Nodes: 8
   Capacity: 40,000 logs/sec
   Monthly Cost: $1,200.00

📈 Peak Requirements (30-day forecast):
   Day: 28
   Required Nodes: 12
   Peak Load: 20,847 logs/sec
   Projected Monthly Cost: $1,800.00

🚨 Scaling Events Detected: 2
   Day 15: Add 2 nodes (Load: 19,500 logs/sec)
   Day 28: Add 2 nodes (Load: 20,847 logs/sec)

💰 Cost Analysis:
   Additional Monthly: $600.00
   Additional Annual: $7,200.00
Stage 5: Actionable Recommendations
✅ Capacity Planning Recommendations:
   1. Add 4 nodes by day 28
      → Maintains headroom for predicted load spikes
      → Estimated cost: $600/month

   2. Scale gradually to optimize costs:
      Step 1: Day 15 - Add 2 nodes
      Step 2: Day 28 - Add 2 nodes

   3. Monitor utilization approaching 80% threshold
      → Set up automated alerts
      → Review forecasts weekly
Starting the API Server
The FastAPI server provides programmatic access to forecasting capabilities:
# Using the convenience script
./start.sh
Or manually:
source venv/bin/activate
python -m src.api.forecast_api
Expected output:
INFO:     Started server process
INFO:     Uvicorn running on http://0.0.0.0:8000
INFO:     Application startup complete
Testing API Endpoints
Once the server is running:
Health Check:
curl http://localhost:8000/

Response:
{
  "service": "Capacity Planning API",
  "status": "healthy",
  "version": "1.0.0"
}
Generate 7-Day Forecast:
curl http://localhost:8000/api/forecast/7days | python -m json.tool

Response:
{
  "forecast_days": 7,
  "confidence_level": 0.9,
  "current_logs_per_second": 18432.5,
  "predicted_logs_per_second": 19124.3,
  "growth_percentage": 3.75,
  "predictions": [18456, 18489, ...],
  "upper_bound": [19234, 19278, ...],
  "lower_bound": [17678, 17700, ...]
}
Get Capacity Recommendations:
curl http://localhost:8000/api/capacity/recommendations | python -m json.tool

Response:
{
  "forecast_period": "30 days",
  "current_capacity": {
    "nodes": 8,
    "logs_per_second": 40000
  },
  "peak_requirement": {
    "day": 28,
    "nodes": 12,
    "logs_per_second": 20847
  },
  "scale_events": [
    {
      "day": 15,
      "action": "Add 2 nodes",
      "predicted_load": 19500
    }
  ],
  "recommendation": "Add 4 nodes by day 28"
}
Access API Documentation:
Visit http://localhost:8000/docs in your browser for interactive API documentation powered by Swagger UI.
Docker Deployment
For containerized deployment:
cd capacity-planning-system
docker-compose up --build -d
This starts:
Capacity planning API server (port 8000)
All required dependencies
Health monitoring
Verify deployment:
docker-compose ps

Expected:
NAME                    STATUS      PORTS
capacity-api-1         Up          0.0.0.0:8000->8000/tcp
Test the containerized API:
curl http://localhost:8000/api/capacity/current
Stop the containers:
docker-compose down
Performance Expectations
Your capacity planning system should meet these performance targets:
Processing Performance
Historical data processing: Under 5 seconds for 90 days of hourly data
Forecast generation: Under 2 seconds for 30-day prediction
API response time: Under 500ms for standard queries
Dashboard load time: Under 1 second initial render
Accuracy Targets
7-day forecast: ±10% prediction error
30-day forecast: ±20% prediction error
Resource sizing: 95% confidence intervals
System Requirements
CPU: 2 cores for forecasting engine
Memory: 4GB for 90 days of historical data
Storage: 1GB for metrics and models
Network: Minimal (batch data collection)
Configuration Guide
Customizing Forecasting Parameters
Edit config/planning_config.yaml:
forecasting:
  algorithms:
    - linear_regression
    - exponential_smoothing
    - prophet_like
  default_forecast_days: 30
  confidence_level: 0.90
  min_historical_points: 168  # 1 week minimum
Customizing Cluster Profile
Edit config/cluster.yaml:
cluster_name: "log-processing-prod"
current_nodes: 8

node_spec:
  cpu_cores: 2
  memory_gb: 8
  disk_gb: 100

performance_profile:
  logs_per_second_per_node: 5000
  avg_latency_ms: 45
  p95_latency_ms: 120
Adjust these values to match your actual infrastructure specifications.
Troubleshooting Common Issues
Python Version Issues
Error: python3.11: command not found
Solution:
# Install Python 3.11
# Ubuntu/Debian:
sudo apt-get install python3.11

# macOS:
brew install python@3.11

# Or use python3 if version is 3.11+
python3 --version
Library Installation Errors
Error: ERROR: Could not find a version that satisfies the requirement
Solution:
# Upgrade pip first
pip install --upgrade pip

# Then install requirements
pip install -r requirements.txt
API Server Not Responding
Error: Connection refused when accessing http://localhost:8000
Solution:
# Check if server is running
ps aux | grep forecast_api

# Check if port is already in use
lsof -i :8000

# Restart the server
./stop.sh
./start.sh
Low Forecast Accuracy
Issue: Predictions significantly differ from actual usage
Solution:
Collect more historical data (90+ days recommended)
Check for data quality issues in metrics collection
Adjust confidence levels in configuration
Review and update cluster performance profile
Integration with Previous Work
Day 30 (Performance Monitoring)
Your capacity planner reads metrics directly from the monitoring system you built. The performance data you’ve been collecting becomes the foundation for forecasting.
Integration points:
CPU usage metrics → Resource requirement calculations
Memory consumption → Node sizing decisions
Log throughput rates → Capacity predictions
Day 154 (Disaster Recovery)
Capacity planning ensures adequate infrastructure headroom for disaster recovery scenarios. If DR requires 2x capacity during failover, the planning tool identifies this need weeks in advance.
Integration points:
DR capacity requirements → Proactive scaling
Failover testing results → Capacity validation
Recovery time metrics → Infrastructure adequacy
Day 156 Preview (SIEM Features)
Security monitoring generates 5-10x more logs than application monitoring. Your capacity planner helps size infrastructure for SIEM deployment before you build it.
Preparation:
Forecast SIEM log volumes based on current rates
Calculate dedicated security processing nodes
Budget for increased storage and network capacity
Assignment: Forecast Your System’s Future
Objective: Use your capacity planning tool to predict infrastructure needs for the next quarter.
Tasks
Collect 90 days of historical metrics from your monitoring system
Generate 30-day and 90-day forecasts using all three algorithms
Calculate resource requirements for predicted peak loads
Create capacity budget proposal with cost estimates
Set up automated alerts for when capacity reaches 80% of predictions
Working demo link
Success Criteria
Forecasts show realistic growth patterns
Resource recommendations match predicted load
Dashboard visualizes trends clearly
Alert system triggers appropriately
Solution Approach
Step 1: Historical Data Collection
# Configure collector for your monitoring database
vim config/planning_config.yaml

# Run collection
python -m src.collectors.metrics_collector --days 90 --output data/historical.csv
Step 2: Forecast Generation
# In Python console
from src.analyzers.forecasting_engine import ForecastingEngine

engine = ForecastingEngine()
engine.load_historical_data('data/historical.csv')

# Generate forecasts
forecast_30d = engine.predict(days=30, confidence=0.90)
forecast_90d = engine.predict(days=90, confidence=0.80)

# Compare algorithms
engine.evaluate_models()  # Shows which performs best
Step 3: Resource Calculation
from src.calculators.resource_calculator import ResourceCalculator

calculator = ResourceCalculator(current_cluster_profile='config/cluster.yaml')

# Calculate needs for peak predicted load
peak_load = max(forecast_30d['predicted_logs_per_sec'])
resources = calculator.calculate_requirements(peak_load)

print(f"Nodes needed: {resources['nodes']}")
print(f"Total cost: ${resources['estimated_monthly_cost']}")
Step 4: Budget Proposal
The system generates a comprehensive report including:
Historical trends with visualizations
Forecast charts with confidence intervals
Resource requirements timeline
Cost projections by month
Risk analysis and recommendations
Step 5: Alert Configuration
# config/alerts.yaml
capacity_alerts:
  - name: "Approaching Capacity Limit"
    condition: "current_usage > 0.8 * predicted_capacity"
    notification: "slack_webhook"

  - name: "Forecast Exceeds Budget"
    condition: "predicted_cost > monthly_budget"
    notification: "email_infrastructure_team"
Production Best Practices
1. Multi-Model Ensemble
Don’t rely on one forecasting algorithm. Combine predictions from linear, exponential, and Prophet-style models for robust forecasts. The system evaluates all three and can weight them based on historical accuracy.
2. Regular Recalibration
Retrain models weekly with latest data. Growth patterns change - your forecasts should adapt. Set up a cron job:
# Add to crontab
0 2 * * 1 cd /path/to/capacity-planning-system && python -m src.collectors.metrics_collector --days 90
3. Scenario Planning
Run “what-if” scenarios: “If we add feature X, logs increase 40% - how much capacity?” The resource calculator supports this through parameter adjustment.
4. Cost Optimization
Don’t just forecast peak needs. Identify opportunities to scale down during off-peak hours. Many cloud providers offer scheduling for cost savings.
5. Human Validation
Auto-generated forecasts should be reviewed by engineers. Context matters - a planned product launch isn’t captured in historical data. Use forecasts as input to informed decisions, not as automatic scaling triggers.
Key Takeaways
Proactive Planning Beats Reactive Scaling
Predicting needs 30 days ahead is cheaper than emergency infrastructure purchases. The time you invest in capacity planning pays dividends in avoided outages and optimized costs.
Data-Driven Decisions
Historical patterns combined with statistical forecasting beats gut feeling about capacity needs. Numbers don’t lie, but they do need proper interpretation.
Cost Visibility
Translating log volumes to dollar amounts helps prioritize optimizations. When you see “$7,200/year additional cost,” suddenly log reduction initiatives become attractive.
Confidence Intervals Matter
“Probably need 5-7 nodes” is more useful than “need 6 nodes” without context. Uncertainty quantification helps you make risk-aware decisions.
Foundation for Growth
As your system scales from thousands to millions of logs/sec, capacity planning prevents infrastructure from becoming a bottleneck. The patterns you implement today scale with your system.
What You’ve Accomplished
You’ve successfully built a production-ready capacity planning system that:
Collects and analyzes 90 days of historical metrics
Implements three forecasting algorithms with confidence intervals
Calculates concrete infrastructure requirements from predictions
Provides REST API for programmatic access
Generates actionable recommendations for capacity scaling
Establishes foundation for proactive infrastructure management
This is the same type of tool that infrastructure teams at Netflix, Uber, and GitHub rely on daily. When your log processing system scales 10x next year, you’ll see it coming months in advance and be ready.