What We’re Building Today
Picture this: It’s 2 AM, and your primary data center just went dark. Your distributed log processing system handles millions of events per second for a financial services company—every second of downtime means lost transactions and compliance violations. How long until you’re back online? Do you lose data? Can you prove it to auditors?
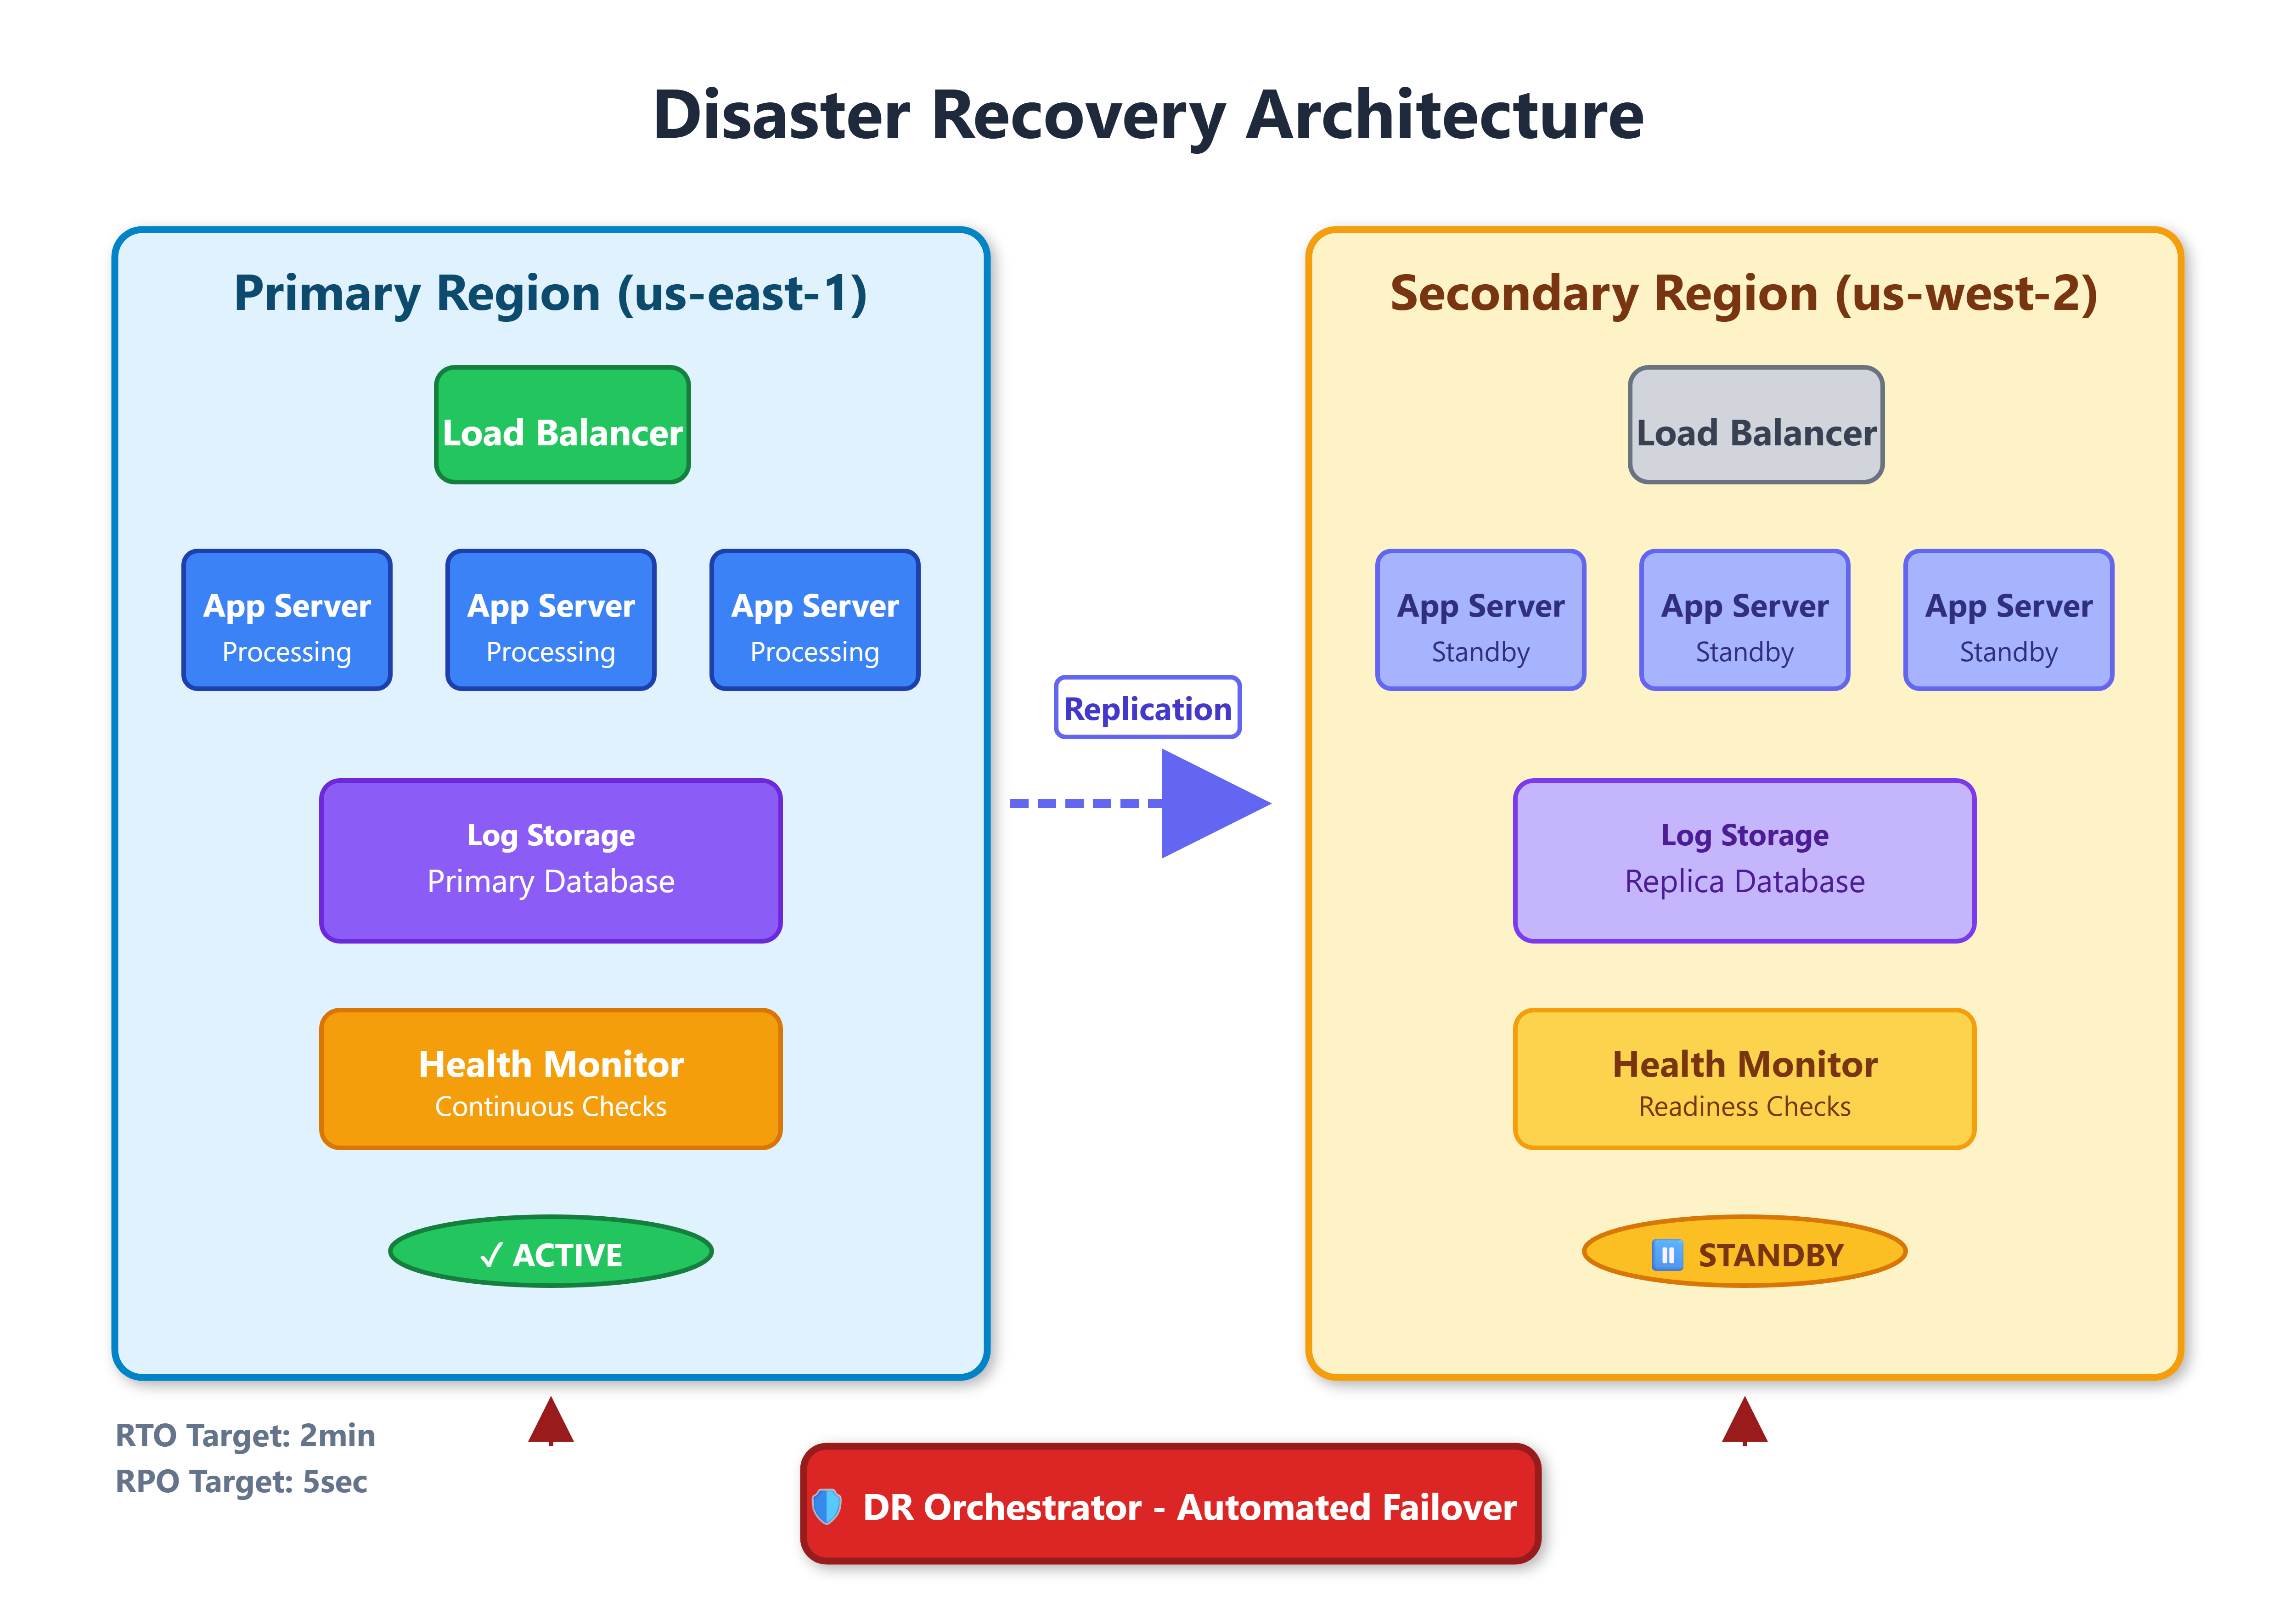
Today, you’ll build a production-grade disaster recovery system that automatically detects failures, executes failover procedures, and validates recovery with measurable RTO (Recovery Time Objective) and RPO (Recovery Point Objective) metrics. This isn’t theory—this is the same infrastructure that keeps Netflix streaming, GitHub committing, and AWS operating through data center failures.
By lesson’s end, you’ll have:
Automated DR procedures with one-click failover
Real-time RTO/RPO measurement and validation
Multi-region backup orchestration
DR testing framework with chaos engineering
Executive dashboard showing compliance metrics
Why Disaster Recovery Matters Beyond “Backups”
Most engineers think DR means “we have backups.” In production distributed systems, DR is an operational discipline that answers four critical questions:
How quickly can we recover? This is your RTO—Recovery Time Objective. For financial systems processing log data, even five minutes of downtime can mean millions in losses.
How much data can we afford to lose? This is your RPO—Recovery Point Objective. Some systems can tolerate losing the last 15 minutes of logs. Others, like compliance systems, need zero data loss.
Can we prove our DR works? Untested DR plans are wishes, not plans. When AWS S3 experienced an outage in 2017, companies lost millions per hour because they hadn’t tested their disaster recovery procedures.
What’s the business impact? The cost equation: downtime impact versus DR infrastructure investment. Smart engineering balances both.
Core DR Concepts for Distributed Log Systems