
Nothing teaches better than “Code in Action”.
System Design Course - Everyday code : Join Python Or Java based implementation
Learn AI Agents : Join the AI agent courses before your competition does.
Explore more hands-on courses on portal — Lifetime Access : 4 hands on cour
The Translation Layer Problem
Your distributed log processing system now captures millions of events, extracts metrics, and stores time series data. But here’s the challenge: data engineers speak SQL, executives speak charts, and your logs speak JSON over message queues. BI tools bridge this gap, transforming technical metrics into business intelligence that drives decisions.
Companies like Airbnb use BI integrations to turn booking logs into revenue forecasts. Spotify converts streaming logs into artist performance dashboards. The pattern is consistent: operational logs become strategic insights through proper BI integration.
Architecture: The Three Connection Patterns
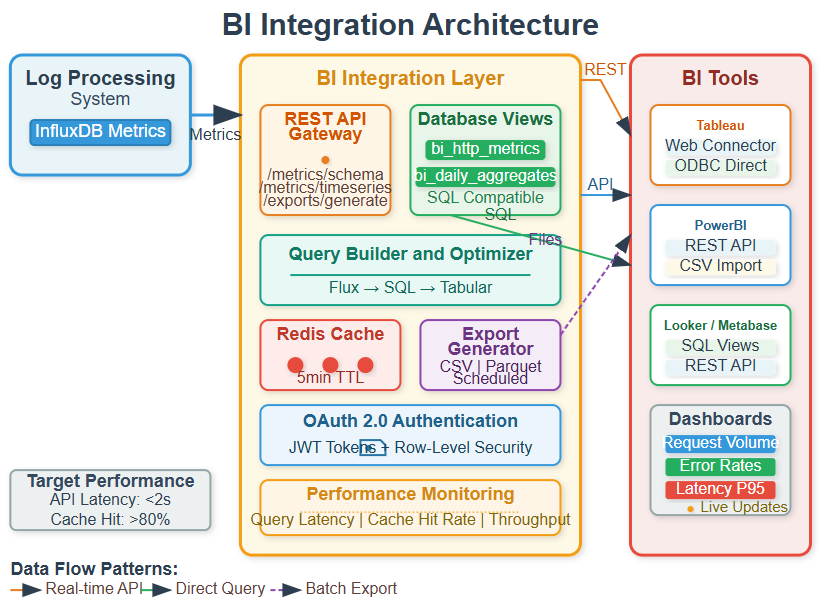
REST API Gateway Pattern
BI tools like Tableau can consume data through REST APIs. Your system exposes HTTP endpoints that serve aggregated metrics in formats BI tools expect - JSON with specific schemas, CSV for bulk exports, or custom formats matching tool requirements.
Direct Database Connection Pattern
PowerBI and similar tools excel at connecting directly to databases. Your integration layer maintains SQL-compatible views over your time series data, letting BI tools query as if reading from traditional data warehouses.
File-Based Export Pattern
Some organizations prefer scheduled data exports. Your system generates CSV, Parquet, or JSON files that BI tools import on schedules - hourly for operational dashboards, daily for executive reports.
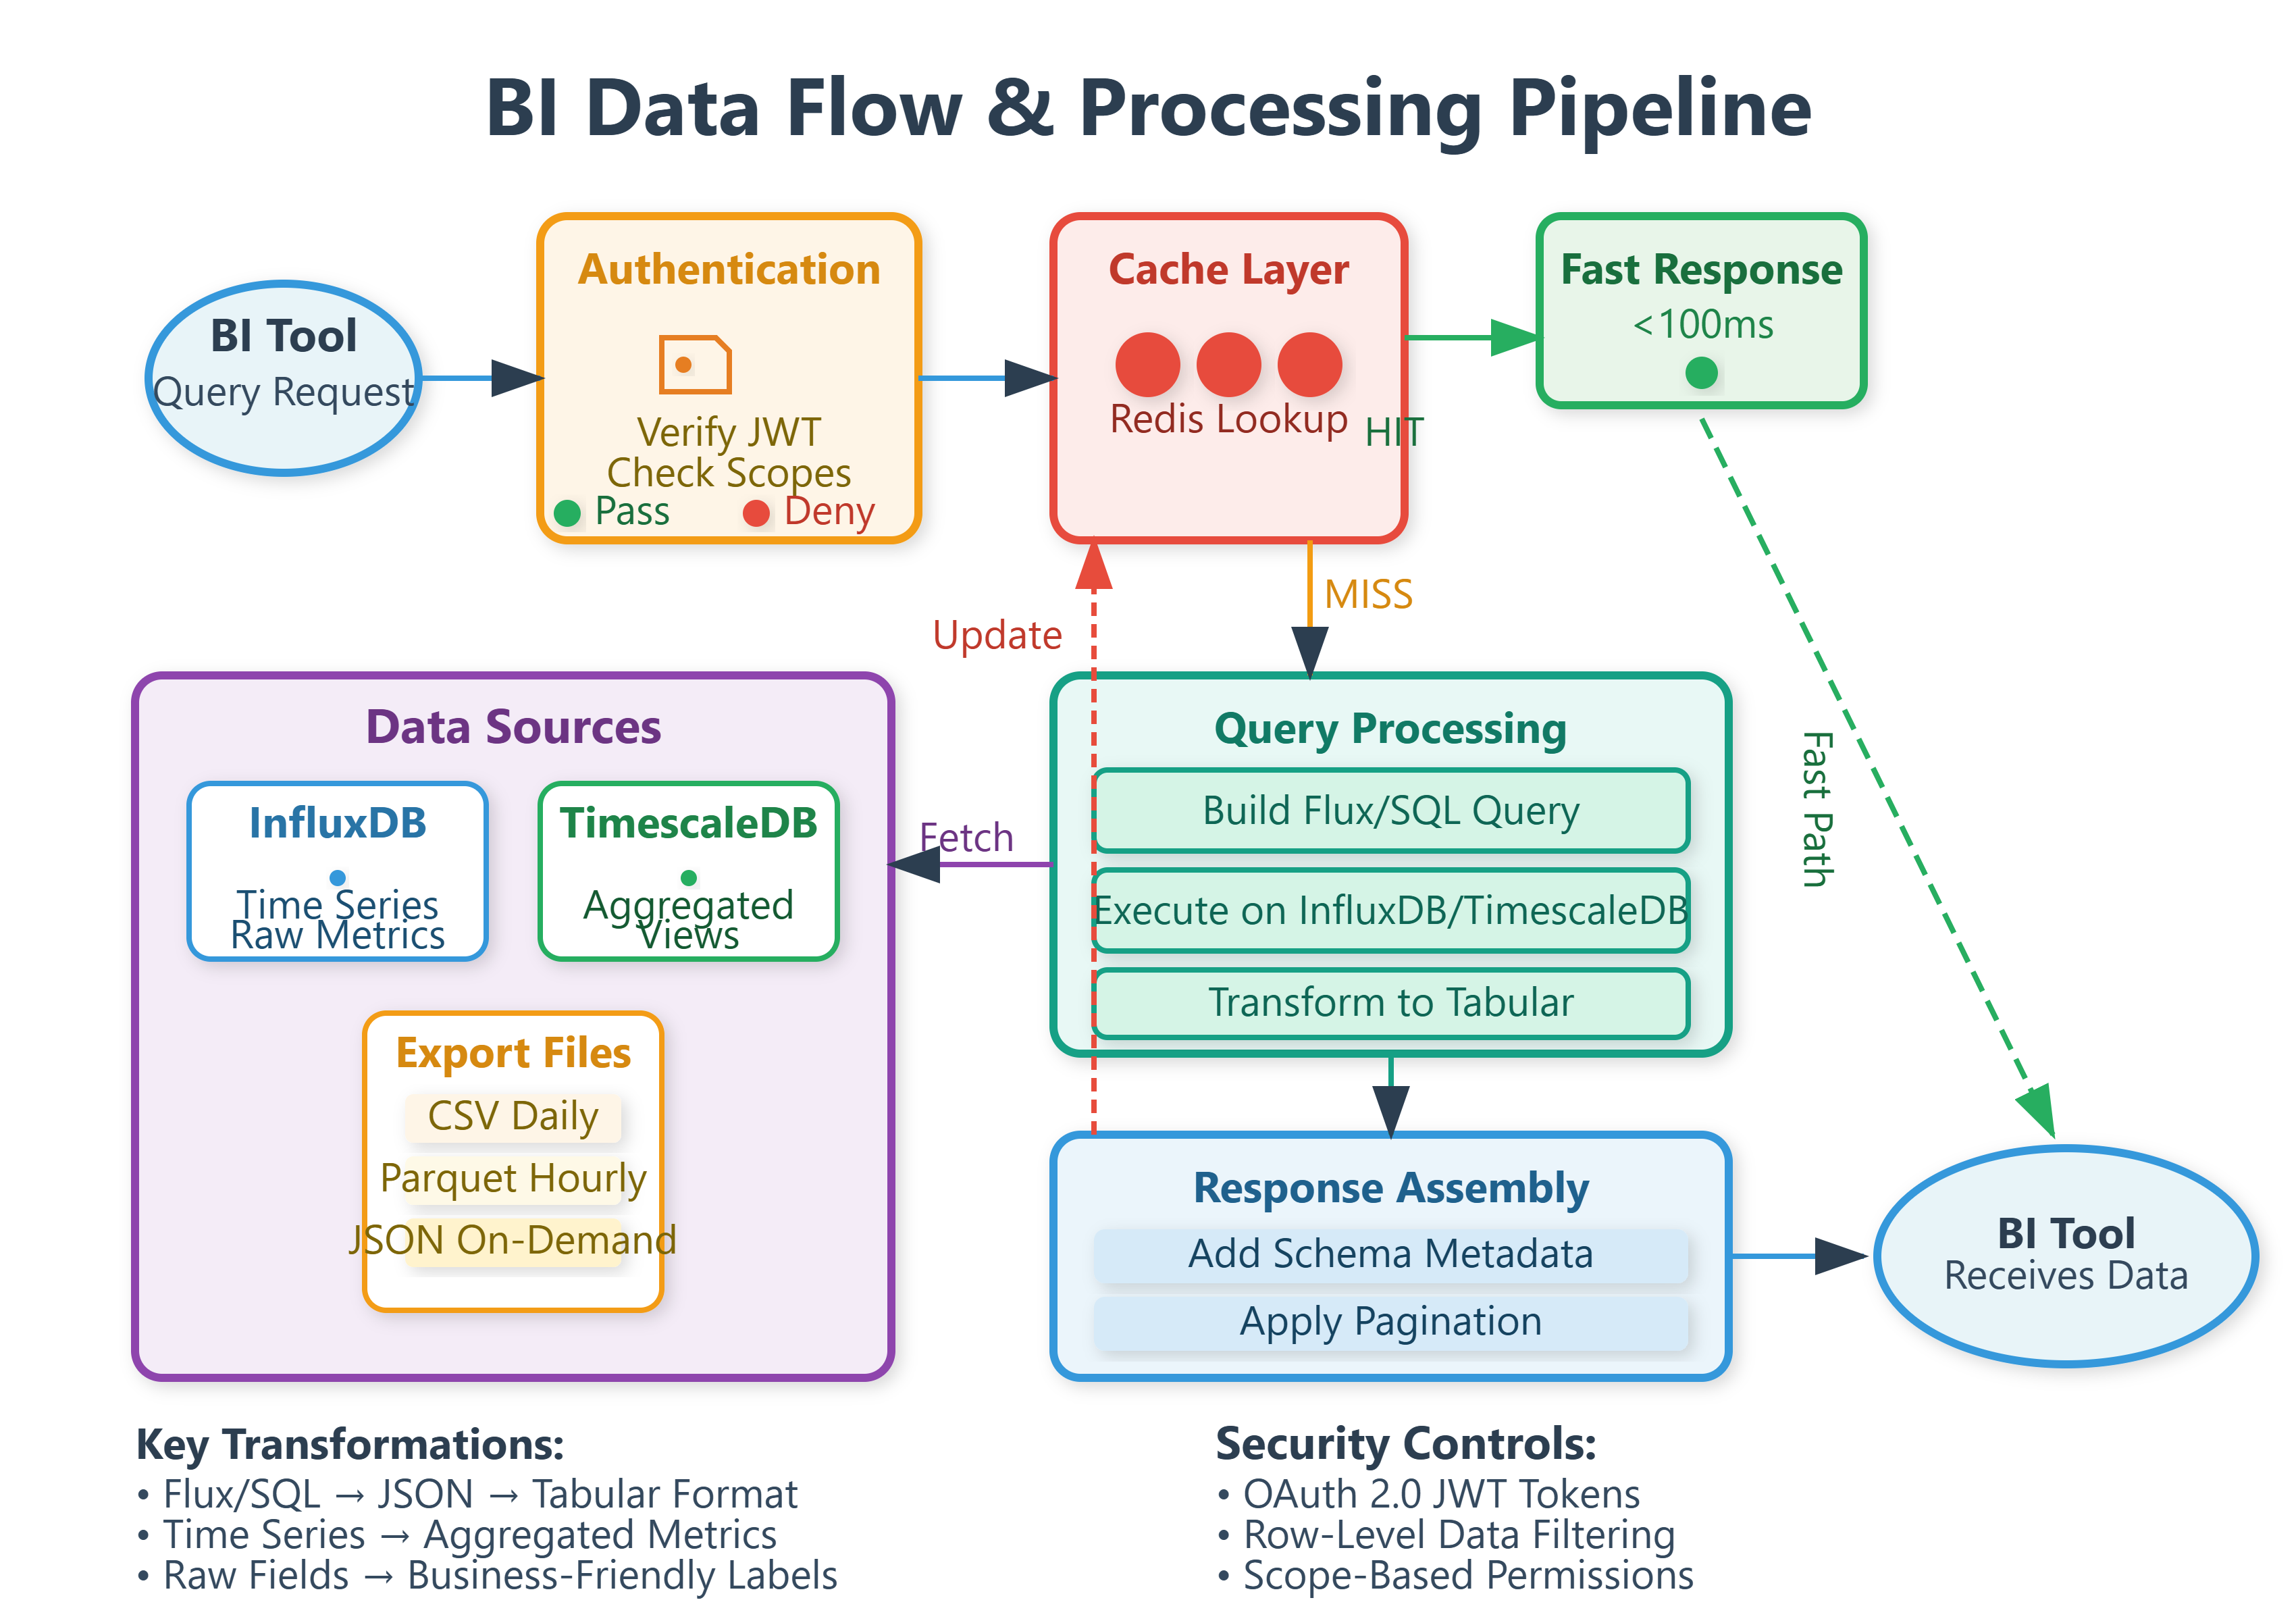
Real-Time vs Batch: The Integration Decision
Netflix’s recommendation dashboards need real-time data as users stream content. Their BI integration queries live data through APIs. Meanwhile, quarterly business reviews use batch exports - snapshot data that won’t change during presentations.
Your implementation supports both. REST APIs serve real-time queries with millisecond latency. Scheduled exports create point-in-time snapshots for historical analysis and reproducible reports.
Data Transformation Pipeline
Raw log metrics need transformation before BI consumption. Your pipeline aggregates per-minute metrics into hourly summaries, joins application logs with infrastructure metrics, and enriches data with business context like customer segments or product categories.
This transformation layer prevents BI tools from crushing your operational databases with complex queries. Pre-aggregation means dashboards render in seconds, not minutes.
Authentication & Security Boundaries
BI tools access sensitive operational data. Your integration implements OAuth 2.0 for API authentication, row-level security that filters data by user permissions, and audit logging tracking who accessed which metrics when.
PowerBI service accounts get read-only database credentials with restricted views. Tableau users authenticate through your API gateway, receiving JWT tokens scoped to their department’s data.
Performance Optimization Patterns
BI queries follow predictable patterns - time-based aggregations, filtering by service or endpoint, grouping by status codes. Your system maintains materialized views for common queries, reducing dashboard load times from 30 seconds to 2 seconds.
Caching layers store recent aggregations. When executives open dashboards showing “last 24 hours”, your cache serves pre-computed results instead of scanning millions of log entries.
Handling Schema Evolution
Log formats change as applications evolve. Your BI integration uses schema versioning to maintain compatibility. When adding new fields, old dashboards continue working while new dashboards access enhanced data.
Backward-compatible transformations ensure that adding “response_time_p99” metric doesn’t break existing “response_time_avg” visualizations in deployed dashboards.
Implementation Guide
Progressive Implementation
Github Link:
https://github.com/sysdr/course/tree/main/day147/day147-bi-integrationPhase 1: Foundation - Data Access Layer
Understanding the Data Model
Your time series database (InfluxDB from Day 146) stores metrics with this structure:
measurement: http_requests
tags: service, endpoint, status_code
fields: count, avg_response_time, p95_response_time
timestamp: nanosecond precision
BI tools expect tabular data with clear dimensions and measures. Your access layer transforms time series to relational format.
Core Data Structures
python
# Pseudo-code showing key concepts
@dataclass
class MetricQuery:
    measurement: str
    time_range: TimeRange
    aggregation_window: str  # “1h”, “1d”
    filters: Dict[str, List[str]]
    metrics: List[str]

@dataclass
class BIDataResponse:
    schema: Dict[str, str]  # column_name -> data_type
    data: List[Dict]  # rows of data
    metadata: QueryMetadata
Query Builder Implementation
The query builder translates BI requests into InfluxDB queries:
python
# Concept: Building optimized time series queries
class InfluxQueryBuilder:
    def build_aggregation_query(self, query: MetricQuery):
        # 1. Select relevant measurement and time range
        # 2. Apply tag filters for dimensions
        # 3. Group by aggregation window
        # 4. Calculate requested metrics (avg, sum, count)
        # 5. Format results as tabular data
        pass
Key Insight: BI tools expect consistent column names. Your builder maintains a mapping from internal metric names to business-friendly labels: avg_response_time → “Average Response Time (ms)”.
Phase 2: REST API Endpoints
Endpoint Design Philosophy
BI tools make predictable query patterns. Design endpoints matching these patterns:
Time Series Endpoint: /api/v1/metrics/timeseries
Returns metrics aggregated by time windows
Supports filtering by service, endpoint, status codes
Includes pagination for large result sets
Aggregation Endpoint: /api/v1/metrics/aggregate
Pre-computed summaries (daily totals, weekly averages)
Faster than raw time series for dashboard cards
Caches results for 5-minute windows
Metadata Endpoint: /api/v1/metrics/schema
Returns available metrics, dimensions, and their types
Helps BI tools build field lists and validation
Request/Response Flow
python
# Concept: Processing a BI tool query
async def handle_timeseries_request(request: BIRequest):
    # 1. Validate authentication token
    # 2. Parse query parameters (time range, filters)
    # 3. Check cache for recent results
    # 4. If cache miss, query InfluxDB
    # 5. Transform to BI-friendly format
    # 6. Cache result with TTL
    # 7. Return with proper CORS headers
Performance Pattern: Dashboards often query multiple metrics simultaneously. Your API supports batch requests to reduce network overhead from 10 requests to 1.
Phase 3: Database Views for Direct Connection
View Design Strategy
PowerBI and Tableau can connect directly to PostgreSQL-compatible databases. Your system maintains TimescaleDB views exposing time series data through SQL:
sql
-- Concept: Creating a BI-friendly view
CREATE VIEW bi_http_metrics AS
SELECT
    time_bucket(’1 hour’, timestamp) AS hour,
    service,
    endpoint,
    status_code_group,  -- 2xx, 4xx, 5xx
    COUNT(*) as request_count,
    AVG(response_time) as avg_response_time,
    PERCENTILE_CONT(0.95) WITHIN GROUP (ORDER BY response_time) as p95_response_time
FROM http_request_logs
GROUP BY hour, service, endpoint, status_code_group;
Optimization Key: Pre-aggregating to hourly buckets reduces query scan from millions of rows to thousands, making dashboard queries instant.
Row-Level Security
Different teams should see different data:
python
# Concept: Implementing data filtering by user
class RowLevelSecurityFilter:
    def apply_user_filter(self, user: User, query: str):
        # 1. Lookup user’s allowed services from auth system
        # 2. Inject WHERE clause restricting to allowed services
        # 3. Return modified query that enforces permissions
Phase 4: File Export Pipeline
Export Scheduling Architecture
Executive dashboards use point-in-time data snapshots. Your pipeline generates exports on schedule:
python
# Concept: Scheduled export generation
class ExportPipeline:
    async def generate_daily_export(self, date: datetime):
        # 1. Query previous day’s aggregated metrics
        # 2. Join with dimension tables (service names, categories)
        # 3. Calculate business KPIs (error rate %, latency SLO compliance)
        # 4. Write to Parquet with partitioning (year/month/day)
        # 5. Update export manifest for BI tools
Format Choice:
CSV: Universal compatibility, human-readable, larger file size
Parquet: Columnar storage, 10x smaller, faster BI imports, requires special handling
Export Manifest Pattern
BI tools need to discover available exports:
json
{
  “exports”: [
    {
      “date”: “2025-06-16”,
      “format”: “parquet”,
      “url”: “/exports/metrics/2025/06/16/data.parquet”,
      “row_count”: 125430,
      “columns”: [”timestamp”, “service”, “request_count”, “error_rate”]
    }
  ]
}
Phase 5: Authentication & Authorization
OAuth 2.0 Flow for BI Tools
Tableau and PowerBI support OAuth for secure API access:
python
# Concept: OAuth token validation
class BIAuthMiddleware:
    async def validate_token(self, token: str):
        # 1. Verify JWT signature using public key
        # 2. Check token expiration
        # 3. Extract user permissions (scopes)
        # 4. Load user’s allowed data domains
        # 5. Attach to request context for authorization
Security Pattern: Service accounts for BI tools get long-lived refresh tokens with restricted scopes. Individual users authenticate through SSO with time-limited access tokens.
Phase 6: Performance Optimization
Caching Strategy
BI dashboards refresh every 5-15 minutes. Cache prevents redundant queries:
python
# Concept: Multi-level cache
class BICacheLayer:
    def get_or_compute(self, query: MetricQuery):
        # L1: In-memory cache for last 100 queries (millisecond latency)
        # L2: Redis cache for last hour’s queries (single-digit ms latency)
        # L3: Compute from database (100-2000ms latency)
Cache Key Design: Include query parameters + user permissions in cache key to prevent unauthorized data leakage between users.
Query Optimization Patterns
Pattern 1: Materialized View Refresh Pre-compute common aggregations overnight when system load is low:
python
# Daily aggregation refresh at 2 AM
UPDATE bi_daily_metrics SET
    computed_at = NOW(),
    metrics = compute_previous_day_metrics();
Pattern 2: Query Pushdown Move filtering and aggregation to database layer instead of application layer - databases are optimized for these operations.
Pattern 3: Connection Pooling BI tools make many concurrent requests. Connection pools prevent overwhelming your database:
python
# Limit concurrent database connections from BI layer
db_pool = create_pool(min_size=10, max_size=50)
Build & Test Process
Environment Setup
bash
# Create project structure
mkdir -p day147-bi-integration/{src,tests,config,exports,static}
cd day147-bi-integration

# Python virtual environment with 3.11
python3.11 -m venv venv
source venv/bin/activate

# Install dependencies
pip install fastapi==0.110.0 uvicorn==0.28.0 \
    influxdb-client==1.40.0 psycopg2-binary==2.9.9 \
    pyarrow==15.0.0 pandas==2.2.0 \
    pyjwt==2.8.0 redis==5.0.3 \
    pytest==8.1.0 httpx==0.27.0
Testing Strategy
Unit Tests
Verify individual components work correctly:
bash
# Test query builder
python -m pytest tests/test_query_builder.py -v

# Test authentication middleware
python -m pytest tests/test_auth.py -v

# Test export generation
python -m pytest tests/test_exports.py -v
Expected Results: All tests pass, verifying query translation, token validation, and file generation.
Integration Tests
Test complete data flow from API request to response:
bash
# Start test containers (InfluxDB, Redis, TimescaleDB)
docker-compose up -d

# Run integration tests
python -m pytest tests/integration/ -v

# Expected: API returns proper data format, caching works, permissions enforced
Load Testing
Verify performance under dashboard refresh load:
bash
# Simulate 100 concurrent BI dashboard refreshes
python tests/load_test_bi_queries.py

# Target metrics:
# - p50 latency < 100ms for cached queries
# - p95 latency < 2s for complex aggregations
# - 0% error rate under load
Verification Steps
Step 1: Start BI Integration Server
bash
uvicorn src.main:app --host 0.0.0.0 --port 8000 --reload

# Expected output:
# INFO: Uvicorn running on http://0.0.0.0:8000
# INFO: Database connections initialized
# INFO: Cache layer ready
Step 2: Verify API Endpoints
bash
# Get available metrics metadata
curl http://localhost:8000/api/v1/metrics/schema | jq

# Expected: JSON showing available metrics, dimensions, data types

# Query time series data
curl “http://localhost:8000/api/v1/metrics/timeseries?service=api&start=2025-06-15T00:00:00Z&end=2025-06-16T00:00:00Z” \
  -H “Authorization: Bearer test_token” | jq

# Expected: JSON array with hourly aggregated metrics
Step 3: Test Database Views
bash
# Connect to TimescaleDB and verify views exist
docker exec -it timescaledb psql -U postgres -d metrics

# Run sample query that BI tools would execute
SELECT hour, service, SUM(request_count)
FROM bi_http_metrics
WHERE hour >= NOW() - INTERVAL ‘24 hours’
GROUP BY hour, service
ORDER BY hour DESC
LIMIT 10;

# Expected: Results in under 2 seconds with proper aggregations
Step 4: Verify File Exports
bash
# Trigger manual export generation
curl -X POST http://localhost:8000/api/v1/exports/generate \
  -H “Authorization: Bearer admin_token” \
  -d ‘{”date”: “2025-06-15”, “format”: “parquet”}’

# Check export manifest
curl http://localhost:8000/api/v1/exports/manifest | jq

# Download and verify export file
curl -O http://localhost:8000/exports/metrics/2025/06/15/data.parquet

# Inspect Parquet contents
python -c “import pandas as pd; print(pd.read_parquet(’data.parquet’).head())”

# Expected: Tabular data with proper columns and data types
Step 5: Test Authentication Flow
bash
# Get OAuth token (simulated)
curl -X POST http://localhost:8000/oauth/token \
  -d “grant_type=client_credentials&client_id=tableau&client_secret=secret”

# Expected: JSON with access_token and expires_in

# Use token to access protected endpoint
TOKEN=$(curl -X POST http://localhost:8000/oauth/token \
  -d “grant_type=client_credentials&client_id=tableau&client_secret=secret” | jq -r .access_token)

curl http://localhost:8000/api/v1/metrics/timeseries \
  -H “Authorization: Bearer $TOKEN”

# Expected: Success with data, not 401 Unauthorized
Working Code Demo:
Connecting Real BI Tools
Tableau Connection
Using Web Data Connector:
Open Tableau Desktop
Select “Web Data Connector” as data source
Enter URL:
http://localhost:8000/tableau/wdcAuthenticate with OAuth
Select metrics and time ranges
Build dashboard with drag-drop interface
Expected Behavior: Data refreshes every 5 minutes, visualizations render in under 3 seconds.
PowerBI Connection
Using REST API:
Open PowerBI Desktop
Get Data → Web
Advanced: URL =
http://localhost:8000/api/v1/metrics/timeseries?service=api&start=...Add authentication header
Transform data in Power Query
Create visualizations
Expected Behavior: Manual refresh or scheduled refresh in PowerBI Service works without errors.
Direct Database Connection
Using ODBC:
Install PostgreSQL ODBC driver
Create DSN pointing to TimescaleDB:
localhost:5432Connect from Tableau/PowerBI using PostgreSQL connector
Select from
bi_http_metricsviewBuild dashboards with full SQL query capability
Expected Behavior: Complex joins and calculations execute in database, not BI tool.
Performance Benchmarks
Target Metrics
API Response Time: p50 < 100ms, p95 < 2s, p99 < 5s
Cache Hit Rate: > 80% during business hours
Database View Query Time: < 3s for typical dashboard
Export Generation: < 60s for daily export with 1M rows
Concurrent Users: Support 50+ simultaneous dashboard refreshes
Optimization Checklist
Materialized views created for common aggregations
Indexes on frequently filtered columns (service, timestamp)
Redis cache configured with 1GB memory, LRU eviction
Database connection pool sized appropriately (10-50 connections)
API responses use gzip compression for large payloads
Query timeouts prevent long-running requests from blocking others
Troubleshooting Common Issues
Issue: Slow Dashboard Loads
Diagnosis: Check query execution time in database logs Solution: Add covering indexes, increase cache TTL, pre-aggregate more data
Issue: Authentication Failures
Diagnosis: Verify JWT signature and expiration Solution: Ensure public key matches token issuer, check system clock sync
Issue: Missing Data in BI Tool
Diagnosis: Check if data exists in database but not appearing Solution: Verify row-level security filters, check time zone handling
Issue: Export Generation Fails
Diagnosis: Review export pipeline logs for errors Solution: Ensure sufficient disk space, verify database connectivity, check Parquet library version
Assignment: Build Your BI Integration
Objective: Connect Tableau or PowerBI to your log system and create an operational dashboard.
Requirements:
Expose REST API with at least 3 endpoints (schema, timeseries, aggregate)
Implement OAuth 2.0 token authentication
Create TimescaleDB view with hourly aggregations
Generate daily CSV export with previous day’s metrics
Build Tableau/PowerBI dashboard showing:
Request volume over time (line chart)
Error rate percentage (KPI card)
Top 10 slowest endpoints (bar chart)
Service comparison (grouped bar chart)
Success Criteria:
Dashboard loads in under 5 seconds
Data refreshes without errors
Multiple users can access simultaneously
Exports generated on schedule (simulated with manual trigger)
Solution Steps:
API Implementation: Create FastAPI application with three endpoints, each querying InfluxDB and caching results
Authentication: Use PyJWT library to generate and validate tokens, store public key in config
Database Views: Write SQL creating
bi_http_metricsview in TimescaleDB with hourly aggregationExport Pipeline: Use Pandas to query database, aggregate, and write CSV with proper date partitioning
BI Connection: Follow tool-specific connection guides above, using your API or database view
Dashboard: Drag metrics onto canvas, configure time filters, add calculations for error rates
Key Insights
Multiple connection patterns serve different use cases - APIs for real-time, views for complex analysis, exports for compliance
Caching strategy is critical - BI tools repeatedly query the same data, cache prevents database overload
Security boundaries must protect sensitive data - implement proper authentication and row-level security
Performance optimization makes or breaks user experience - slow dashboards get abandoned
Schema versioning maintains backward compatibility as your log formats evolve
The patterns you’ve implemented mirror production BI integrations at data-driven companies, turning operational logs into strategic business intelligence.
Tomorrow’s Preview: Natural Language Queries
Next, we’ll add an NLP layer that lets users ask questions in plain English: “What caused the spike in errors yesterday afternoon?” Your system will parse natural language, translate to database queries, and return insights - making log data accessible to non-technical stakeholders.
The BI integration you build today provides the data foundation for tomorrow’s conversational analytics.