
The Metrics Mountain You’re Climbing
Your distributed log processing system now handles millions of messages—routed through exchanges, processed by Flink streams, and safely delivered with acknowledgments. But here’s the challenge: when your CEO asks “What was our API latency at 3 AM last Tuesday?” you’re stuck grep-ing through gigabytes of logs. That’s like searching for a specific grain of sand on a beach.
Time series databases solve this elegantly. They transform your flowing log stream into structured, queryable metrics that answer “how much, when, and why” questions instantly. Today you’ll extract metrics from logs and store them in purpose-built databases that make time-based analysis trivial.
Why Regular Databases Fail at Metrics
Traditional databases excel at CRUD operations—create a user, update an order, delete a comment. But metrics are different. You’re not updating yesterday’s API latency; you’re continuously appending new measurements. Regular databases struggle because they’re optimized for random access and updates, not for massive sequential writes of timestamped data.
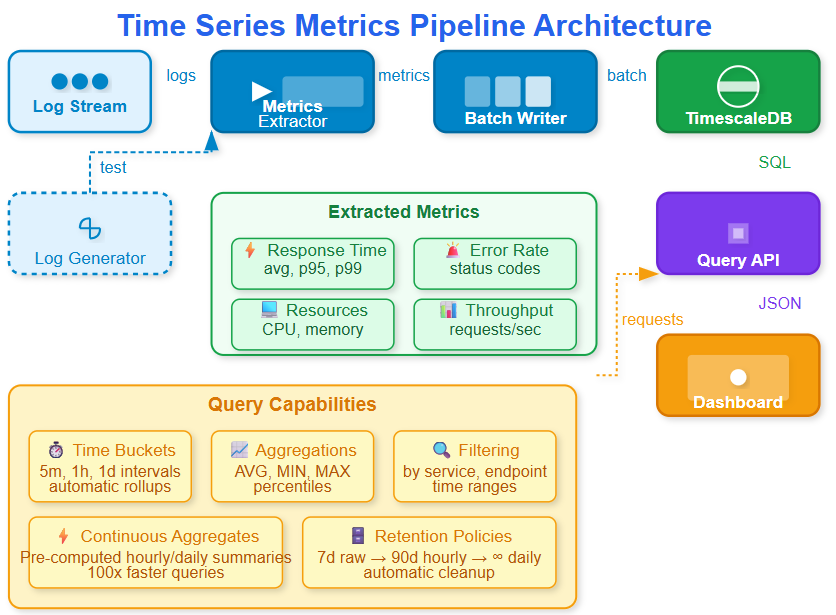
Time series databases like InfluxDB and TimescaleDB are engineered specifically for this pattern. They compress timestamps efficiently (storing “every 5 seconds” instead of repeating full timestamps), partition data by time automatically, and optimize queries that ask “show me all values between X and Y timestamps.” When Netflix analyzes streaming quality metrics across 200 million subscribers, time series databases make the impossible routine.
