The Intelligence Layer Your Logs Deserve
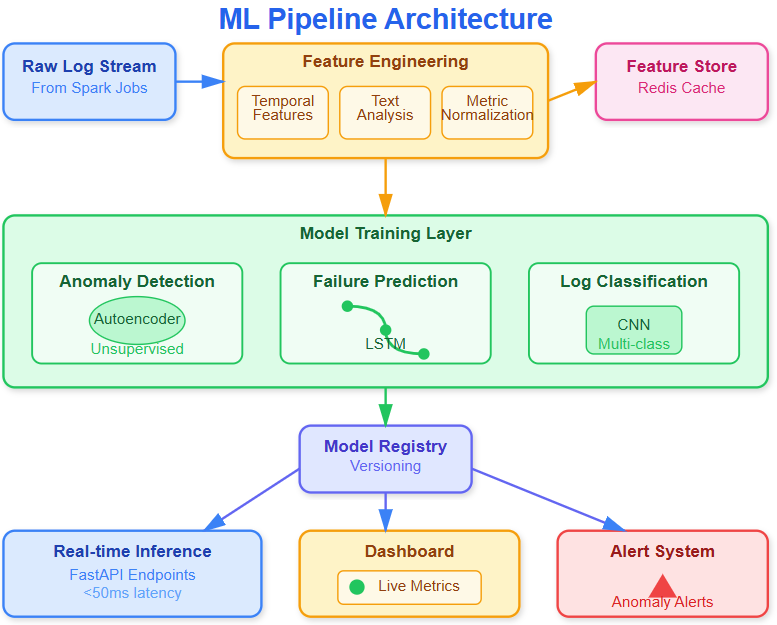
Yesterday you processed terabytes of log data with Spark, extracting patterns at scale. Today we’re adding something transformative: machine learning models that predict failures before they happen, detect anomalies in real-time, and classify log severity automatically.
Think of this as teaching your log processing system to learn from experience. Just like experienced engineers develop intuition for spotting problems, your ML pipeline will develop pattern recognition that works 24/7 across millions of log entries.
Why ML on Log Data Changes Everything
At Google, ML models analyzing system logs predict 70% of infrastructure failures hours before they occur. Netflix’s chaos engineering relies on ML-trained anomaly detection to identify unusual behavior patterns. Amazon uses log-based ML to automatically classify and route issues, reducing mean time to resolution by 60%.
Your system processes logs reactively—ML makes it predictive and intelligent. A sudden spike in error rates? ML predicts if it’s normal traffic variation or impending failure. Unusual API response times? ML distinguishes between expected load patterns and actual degradation.