The Hidden Power of Observable Systems
Your distributed log processing system handles millions of messages daily, but without proper metrics export, you’re flying blind. Twitter’s engineering team processes 400 million tweets daily while maintaining 99.99% uptime—their secret isn’t perfect code, it’s comprehensive observability through metrics exported to monitoring systems.
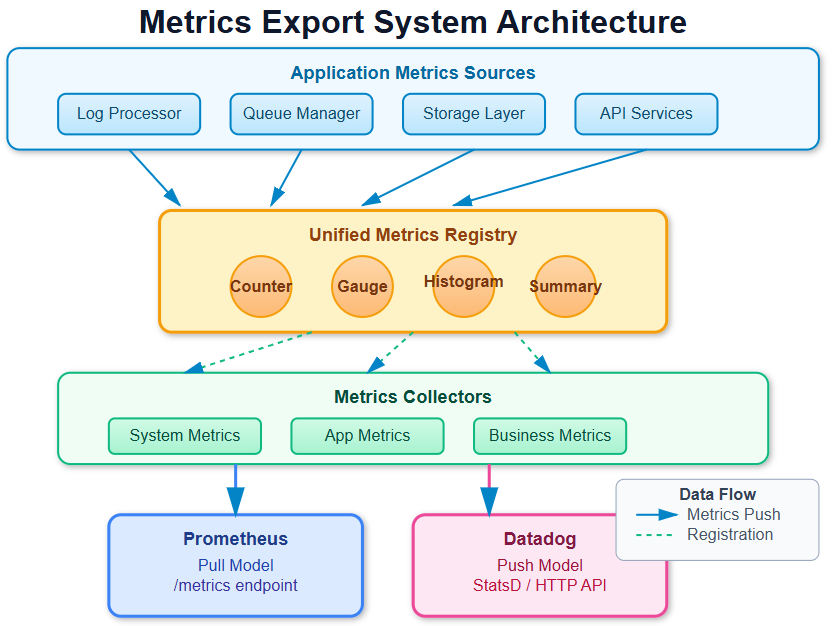
Today you’ll implement production-grade metrics export that sends telemetry data to Prometheus and Datadog, giving operations teams the visibility they need to prevent incidents before they impact users.
Why Metrics Export Transforms Operations
LinkedIn’s Site Reliability Engineering team reduced mean time to detection (MTTD) from 15 minutes to 45 seconds by implementing comprehensive metrics export. When your log processing cluster experiences performance degradation, exported metrics trigger automated remediation before users notice slowdowns.
The difference between reactive and proactive operations lies in metrics export architecture. Systems that push telemetry to centralized monitoring platforms enable cross-team visibility, automated alerting, and historical trend analysis that prevents future incidents.
Core Architecture Components