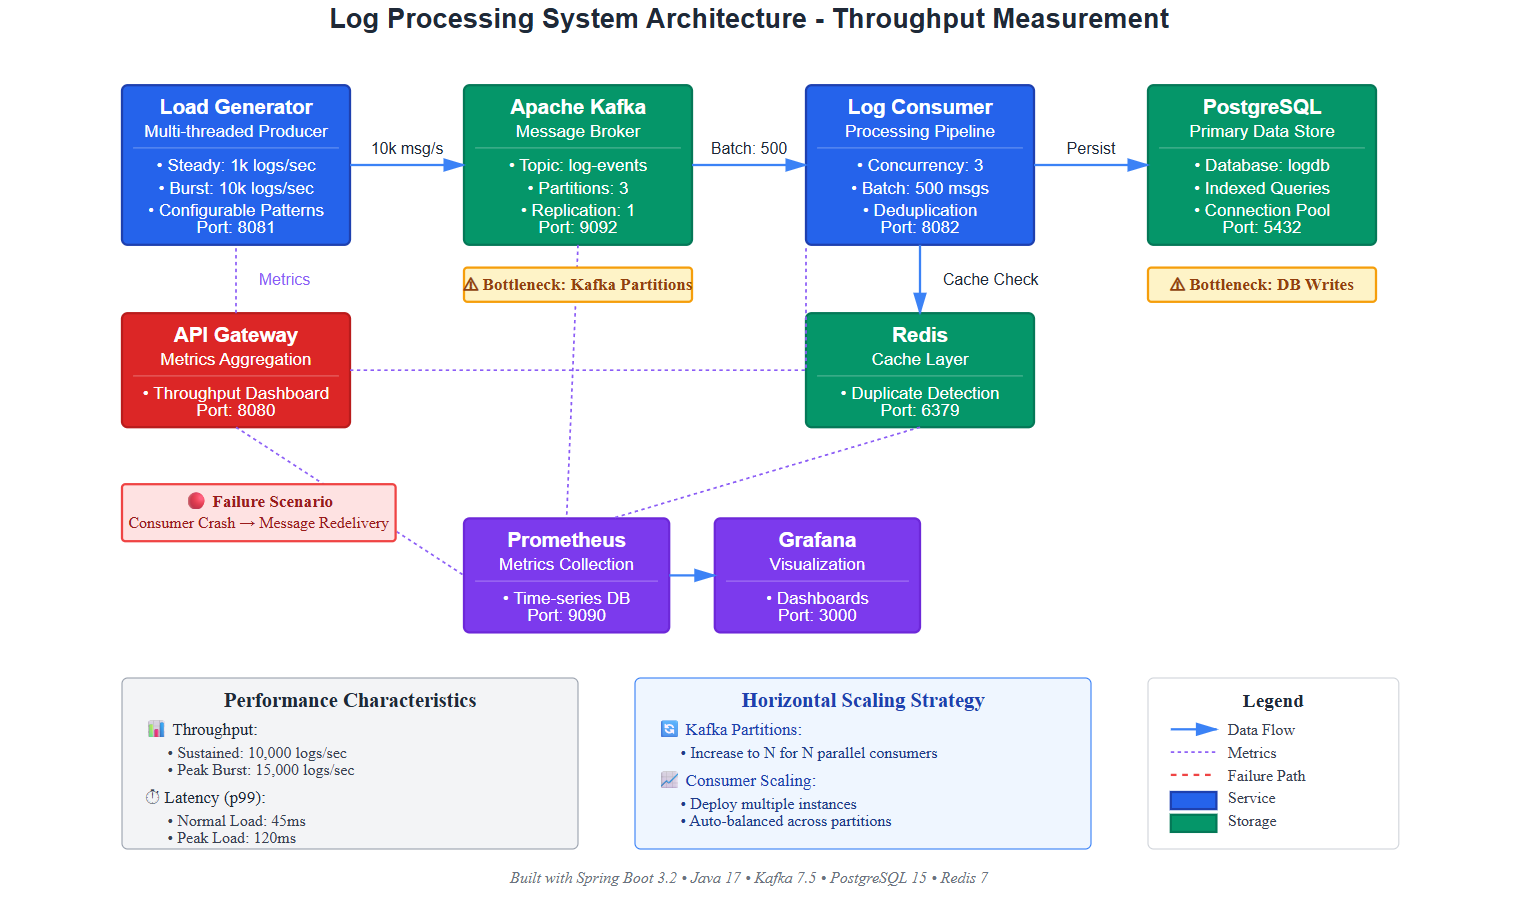
What We’re Building Today
Today you’ll build four critical components:
Multi-threaded load generator capable of producing 10,000+ logs per second with configurable patterns
Comprehensive benchmarking framework measuring end-to-end latency, throughput, and resource utilization
Real-time metrics dashboard tracking system performance under varying load conditions
Automated performance regression testing to validate system scalability improvements
Why This Matters: The Cost of Guessing at Scale
Twitter’s 2010 World Cup crash happened because they didn’t properly load test their timeline infrastructure. When Japan scored against Cameroon, 2,940 tweets per second overwhelmed their Ruby-on-Rails monolith, causing cascading failures across the platform. The incident cost millions in revenue and user trust.
Load testing isn’t about finding the breaking point—it’s about understanding your system’s performance characteristics before production traffic does. At Netflix, every service change goes through automated load testing that simulates peak viewing hours. This practice caught a memory leak in their recommendation engine that would have degraded the experience for 100+ million subscribers during a major release.
The difference between systems that scale and systems that collapse under load comes down to one thing: knowing your numbers. Throughput, latency percentiles, resource saturation points—these aren’t vanity metrics, they’re the foundation of capacity planning and architectural decision-making.
System Design Deep Dive: The Architecture of Performance Measurement
Pattern 1: Producer-Consumer Throughput Modeling
Most distributed systems follow a producer-consumer pattern, and understanding this bottleneck is critical. The throughput ceiling isn’t determined by your fastest component—it’s determined by the slowest link in the chain multiplied by the number of parallel paths.
Key Trade-off: Batching vs. Latency
Small batches (10 messages): Lower latency (5ms p99), but throughput caps at ~2,000 msg/sec
Large batches (1000 messages): Higher latency (150ms p99), but throughput reaches 50,000+ msg/sec
Optimal batch size depends on your SLA: real-time alerts need small batches, analytics pipelines need large ones
Architectural Decision: We implement configurable batch sizes with separate producer pools for different traffic classes. High-priority logs bypass batching, while bulk analytics logs use aggressive batching. This is how Kafka achieves both low-latency replication and high-throughput data ingestion.
Pattern 2: Backpressure and Flow Control
When your producer outpaces your consumer, messages accumulate in queues. Without proper backpressure, this leads to memory exhaustion and eventual system collapse.
Three Backpressure Strategies:
Drop-oldest: Discard old messages when buffer fills (Twitter’s timeline approach)
Block-producer: Slow down message generation (Kafka’s default for critical data)
Expand-buffer: Dynamic memory allocation with circuit breaker (Netflix’s approach)
Trade-off Analysis: Drop-oldest sacrifices data completeness for system availability—acceptable for social media feeds, catastrophic for financial transactions. Block-producer guarantees delivery but can cascade upstream, potentially freezing user-facing APIs. Expand-buffer with limits provides the best of both worlds but requires sophisticated monitoring.
Our Implementation: We use a hybrid approach with three-tier prioritization. Critical logs (auth failures, payment errors) get guaranteed delivery with blocked producers. Standard application logs use bounded buffers with drop-oldest. Verbose debug logs use best-effort delivery with aggressive dropping.
Pattern 3: Coordinated Omission in Performance Testing
This is the most common load testing mistake that makes systems appear faster than they are. When your load generator waits for a response before sending the next request, you’re not measuring real-world behavior—you’re measuring the system’s performance when it’s never actually saturated.
Example: Your load generator sends 1,000 req/sec, each request takes 10ms on average. Looks great! But in production, 1,000 concurrent users hit your system simultaneously, and now each request takes 5 seconds because you never tested actual queuing behavior.
Solution: Use closed-loop (fixed concurrency) and open-loop (fixed rate) testing modes. Closed-loop tests saturation scenarios, open-loop tests normal operating conditions. Netflix runs both continuously—closed-loop catches capacity limits, open-loop catches latency regressions.
Pattern 4: Percentile Metrics vs. Averages
Averages are lies at scale. Your average latency might be 50ms, but if p99 is 10 seconds, 1% of your users are having a terrible experience. At 1 million requests per hour, that’s 10,000 angry customers.
Metric Selection:
p50 (median): Typical user experience
p95: Good user experience threshold
p99: SLA boundary—what users will complain about
p99.9: Tail latency—indicates infrastructure problems
Anti-pattern: Optimizing for average latency by adding caching. This might improve p50 from 100ms to 50ms, but if cache misses cause p99 to spike from 500ms to 5 seconds, you’ve made the system worse for your most engaged users.
Pattern 5: Resource Saturation Metrics
Throughput testing reveals which resource becomes the bottleneck first. In distributed systems, bottlenecks cascade:
CPU saturation → increased latency → queue buildup → memory pressure → garbage collection pauses → more latency
Network saturation → packet loss → TCP retransmissions → connection timeouts → circuit breakers open → cascading failures
Monitoring Strategy: Track utilization across all resources simultaneously:
CPU: Keep under 70% for headroom during traffic spikes
Memory: Heap usage should stabilize; continuous growth indicates leaks
Network: Monitor both bandwidth and connection count
Disk I/O: Queue depth matters more than IOPS for log systems
Implementation Walkthrough