What You’ll Build Today
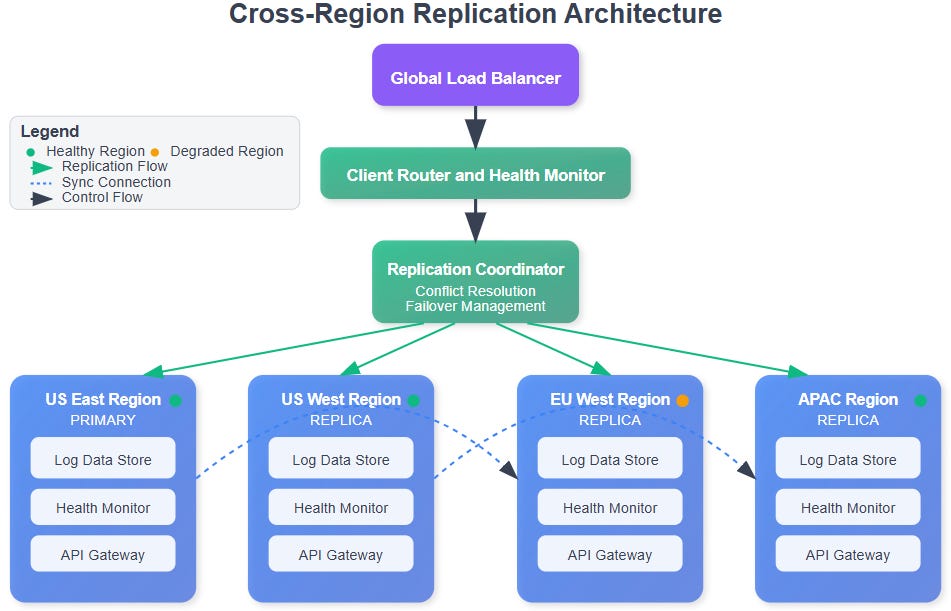
Today’s lesson tackles one of the most critical challenges in distributed systems: keeping your data safe even when entire data centers fail. You’ll implement a cross-region replication system that automatically synchronizes log data across multiple geographic locations, detects failures, and switches operations to healthy regions without manual intervention.
Core Components You’ll Create:
Multi-region replication coordinator with intelligent conflict resolution
Automated failover detection and orchestration system
Real-time synchronization monitoring dashboard
Region-aware client routing with health checks
By the end of this lesson, you’ll have built the same infrastructure that keeps services like Netflix streaming during regional outages.
Why This Matters: Learning from Real-World Failures
When AWS’s us-east-1 region experienced a major outage in 2021, companies with single-region architectures faced complete service disruption. Netflix, however, continued streaming because their cross-region replication ensured instant failover to healthy regions.
Consider what happens when a natural disaster hits a data center, or when network infrastructure fails across an entire region. Without geographic redundancy, your log processing system becomes a single point of failure. A manufacturing company loses production logs, a bank loses transaction records, or a hospital loses patient data.
Modern enterprises can’t afford these risks. Cross-region replication solves this by distributing data across multiple geographic locations, ensuring availability even during catastrophic failures.
Understanding the Core Concepts
Geographic Redundancy Architecture