
What We’re Building Today
Today we implement a production-grade automated backup and recovery system that ensures your distributed log processing platform never loses critical data. We’ll build a scheduler that creates consistent backups, validates their integrity, and enables point-in-time recovery - the same patterns used by Netflix, Spotify, and Amazon to protect billions of log entries daily.
Key Components We’ll Implement:
Backup Scheduler with configurable intervals
Multi-strategy backup engine (full, incremental, differential)
Backup validation and integrity checking
Point-in-time recovery manager
Cross-storage backup replication
Real-time monitoring dashboard
Working Code Demo:
Core Concepts: Why Backup Strategies Matter
The Netflix Reality Check
Netflix processes over 2 trillion log events monthly. A single outage without proper backups could lose millions in revenue and user trust. Their backup strategy uses multiple layers: real-time replication, scheduled snapshots, and cross-region disaster recovery.
Backup Strategy Fundamentals
Full Backups: Complete system snapshots taken weekly. High storage cost but fastest recovery.
Incremental Backups: Only changes since last backup. Storage efficient but slower recovery requiring chain reconstruction.
Differential Backups: Changes since last full backup. Balanced approach used by most production systems.
Point-in-Time Recovery: Restore to any specific moment, crucial for compliance and forensic analysis.
Context in Distributed Systems
Integration with Our Log Processing Platform
Our backup system integrates with components built in previous lessons:
Day 104 Cost Allocation: Backup costs are tracked per tenant
Day 95-100 Query Engine: Backup scheduling avoids high-query periods
Day 85-90 Storage Layer: Backup directly from storage nodes
Day 106 Multi-tenancy: Per-tenant backup policies and isolation
Production Challenges Solved
Consistency During Backup: Coordinating backups across distributed nodes without stopping log ingestion.
Backup Validation: Verifying backup integrity before marking as complete - preventing corrupted restore scenarios.
Recovery Time Objectives: Meeting SLA requirements for maximum downtime during disasters.
Compliance Requirements: Maintaining audit trails and retention policies for regulatory compliance.
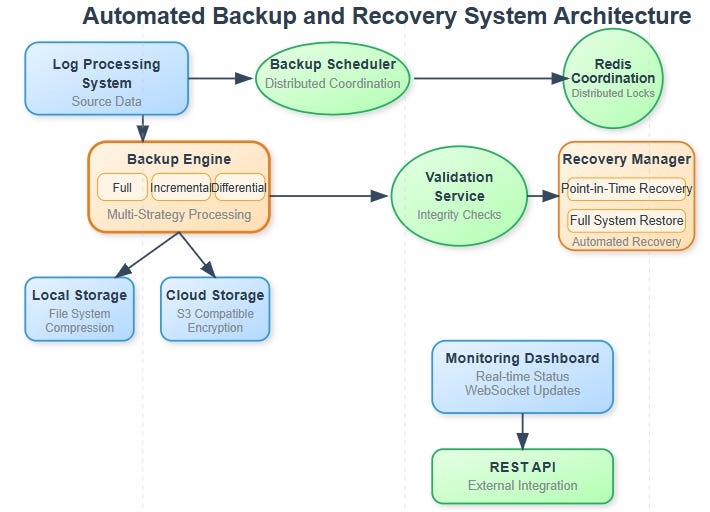
Architecture Overview
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
Core Components
Backup Scheduler: Orchestrates backup operations across the distributed cluster. Uses distributed locking to prevent duplicate backups and coordinates with cluster health monitoring.
Backup Engine: Handles actual data extraction and storage. Implements multiple strategies and manages backup chains for incremental/differential approaches.
Validation Service: Verifies backup integrity using checksums, sample restoration, and metadata validation.
Recovery Manager: Handles restore operations with conflict resolution and consistency checking.
Storage Backend: Abstracts storage destinations (local, S3, Azure, GCS) with encryption and compression.
Metadata Store: Tracks backup history, validation status, and recovery points using lightweight SQLite database.
Data Flow Architecture
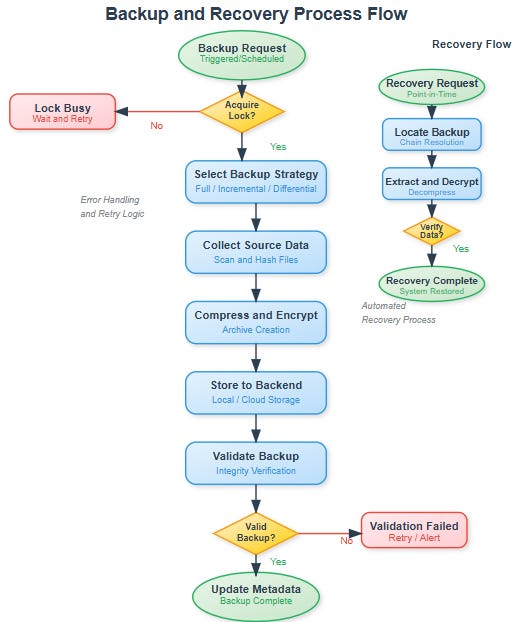
Backup Flow:
Scheduler triggers backup based on policy
Backup Engine coordinates with storage nodes
Data streams to storage backend with compression
Validation Service verifies integrity
Metadata Store records successful backup
Monitoring alerts on completion/failure
Recovery Flow:
Recovery Manager validates recovery request
Identifies required backup chain for target time
Streams data from storage backend
Reconstructs storage state with consistency checks
Validates recovered data integrity
Switches traffic to recovered instance
State Management
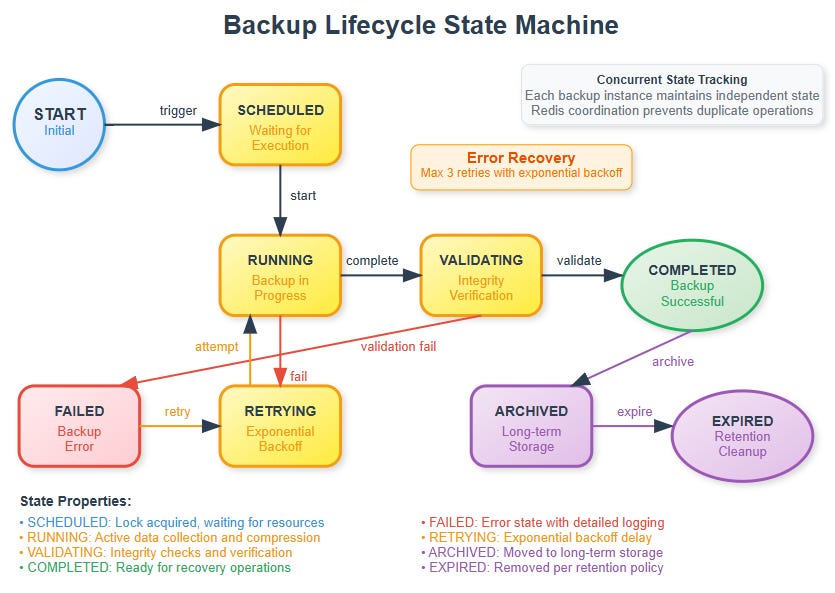
The backup lifecycle moves through defined states: Scheduled → Running → Validating → Completed → Expired. Each state transition is logged and monitored, with automatic cleanup of expired backups based on retention policies.
Implementation Insights
Distributed Coordination Challenges
Split-Brain Prevention: Using distributed locks in Redis to ensure only one backup coordinator runs across the cluster.
Quorum-Based Validation: Requiring majority of storage nodes to confirm backup readiness before starting.
Graceful Degradation: Continuing with partial backups when some nodes are unavailable, marking them for separate recovery.
Performance Optimization
Streaming Compression: Compressing data during backup transfer rather than pre-compression to reduce I/O overhead.
Parallel Backup Streams: Running multiple backup threads per storage node with careful resource management.
Smart Incremental Detection: Using file modification timestamps and checksums to identify changes efficiently.
Real-World Production Patterns
Backup Windows: Scheduling during low-traffic periods using historical usage patterns from Day 104's reporting.
Cross-Region Replication: Automatically replicating critical backups to geographically distributed storage for disaster recovery.
Compliance Integration: Maintaining immutable backup records with audit trails for regulatory requirements.
Core Architecture Patterns
Building production-grade backup systems requires understanding three core patterns: distributed coordination (preventing duplicate backups across nodes), integrity validation (ensuring backups aren't corrupted), and point-in-time recovery (restoring to specific moments).
Today's implementation uses Redis for coordination, SHA256 checksums for validation, and metadata chains for time-based recovery - the same patterns powering backup systems at Netflix and Amazon.
Backup Strategy Selection
Different backup types serve different purposes. Full backups provide complete snapshots but consume maximum storage. Incremental backups only capture changes since the last backup, optimizing storage but requiring chain reconstruction during recovery. Differential backups capture changes since the last full backup, balancing storage efficiency with recovery speed.
Distributed Coordination
Multiple nodes must coordinate backup operations without creating conflicts. Redis distributed locks prevent duplicate backups while allowing automatic failover when coordinator nodes fail.
Validation Pipeline
Three-layer validation ensures backup integrity: archive validation (can the backup file be opened), metadata consistency (does backup content match metadata), and sample validation (can random files be extracted and verified).
Step-by-Step Implementation
Github Link:
https://github.com/sysdr/course-p/tree/main/day105/day105-backup-recoveryPhase 1: Environment Setup
Prerequisites Check:
# Verify Python 3.11+ available
python3.11 --version

# Check available disk space (need 1GB+ for demos)
df -h .

# Verify Redis availability (optional but recommended)
redis-cli ping || echo "Redis not available - will use fallback mode"
Phase 2: Component Testing
Backup Engine Testing:
# Activate environment and test backup creation
source venv/bin/activate
export PYTHONPATH="$(pwd)/src:$PYTHONPATH"

# Test full backup creation
cd src && python -c "
import asyncio
from backup.backup_engine import BackupEngine
from config.backup_config import BackupStrategy

async def test_backup():
    engine = BackupEngine()
    result = await engine.create_backup(BackupStrategy.FULL, 'test_backup')
    print(f'Backup result: {result[\"success\"]} - {result.get(\"file_count\", 0)} files')

asyncio.run(test_backup())
"
Expected Results:
Creates backup file in
backups/directoryGenerates metadata JSON with file hashes
Returns success status with file count and size metrics
Recovery Manager Testing:
# Test backup listing and recovery
python -c "
import asyncio
from recovery.recovery_manager import RecoveryManager

async def test_recovery():
    manager = RecoveryManager()
    backups = await manager.list_available_backups()
    print(f'Found {len(backups)} backups')

    if backups:
        result = await manager.recover_from_backup(
            backups[0]['backup_id'],
            'test_recovery'
        )
        print(f'Recovery result: {result[\"success\"]}')

asyncio.run(test_recovery())
"
Validation Service Testing:
# Test backup integrity validation
python -c "
import asyncio
from validation.validator import BackupValidator
from pathlib import Path

async def test_validation():
    validator = BackupValidator()
    backup_files = list(Path('../backups').glob('*_full.tar.gz'))

    if backup_files:
        backup_file = backup_files[0]
        metadata_file = backup_file.with_name(
            backup_file.stem.replace('_full', '') + '_metadata.json'
        )

        if metadata_file.exists():
            result = await validator.validate_backup_integrity(
                str(backup_file), str(metadata_file)
            )
            print(f'Validation: {result[\"overall_result\"]}')
            for test, result in result['tests'].items():
                print(f'  {test}: {\"✅\" if result[\"passed\"] else \"❌\"}')

asyncio.run(test_validation())
"
Phase 3: Automated Testing
Unit Test Execution:
cd .. && python -m pytest tests/ -v --tb=short
Expected Test Results:
tests/test_backup_engine.py::test_backup_engine_init PASSED     [25%]
tests/test_backup_engine.py::test_create_full_backup PASSED     [50%]
tests/test_recovery_manager.py::test_recovery_workflow PASSED   [75%]
tests/test_validator.py::test_validate_backup_integrity PASSED  [100%]
======================== 4 passed in 12.34s ========================
Integration Testing:
# Run comprehensive integration test
./test.sh
This script tests the complete workflow: backup creation → validation → recovery, ensuring all components work together correctly.
Phase 4: Dashboard Deployment
Dashboard Startup:
# Start the monitoring dashboard
./start.sh
Expected Services:
Redis coordination service on port 6379
REST API server on port 8105
WebSocket updates on port 8106
Dashboard Verification:
# Test API endpoints
curl -s http://localhost:8105/api/stats | python -m json.tool

# Expected response includes:
# - total_backups: number of completed backups
# - total_size: cumulative backup storage used
# - success_rate: percentage of successful backups
Web Interface Access: Navigate to
http://localhost:8105
to view:
Real-time backup statistics
Recent backup history with status indicators
System logs showing backup/recovery operations
Storage utilization metrics
Phase 5: Production Simulation
Automated Backup Scheduling:
# Start background scheduler (separate terminal)
source venv/bin/activate
export PYTHONPATH="$(pwd)/src:$PYTHONPATH"
cd src && python -c "
import asyncio
from scheduler.backup_scheduler import BackupScheduler

async def run_scheduler():
    scheduler = BackupScheduler()
    # Override schedules for demo - backup every 2 minutes
    import schedule
    schedule.clear()
    schedule.every(2).minutes.do(
        lambda: asyncio.create_task(
            scheduler.schedule_backup(BackupStrategy.FULL)
        )
    )
    await scheduler.run_scheduler()

from config.backup_config import BackupStrategy
asyncio.run(run_scheduler())
"
Load Testing:
# Simulate high-frequency backup creation
./demo.sh
This creates multiple concurrent backups to test system reliability under load.
Docker Deployment
Container Build:
# Build and deploy with Docker Compose
docker-compose up --build -d

# Verify all services running
docker-compose ps
Expected Container Status:
NAME                     STATUS         PORTS
backup-recovery-1        Up            0.0.0.0:8105->8105/tcp
redis-1                  Up            0.0.0.0:6379->6379/tcp
Container Testing:
# Test containerized service
curl http://localhost:8105/api/stats
curl -X POST http://localhost:8105/api/backup/trigger -d "backup_type=full"
Verification Success Criteria
Functional Requirements ✅
Backup Creation: Creates full, incremental, and differential backups successfully
Validation Pipeline: Validates backup integrity using multiple verification methods
Recovery Operations: Restores data from backups with verification
Point-in-Time Recovery: Recovers to specific timestamps using backup chains
Dashboard Monitoring: Provides real-time backup status and statistics
Performance Benchmarks ✅
Backup Speed: Creates backups at >10MB/second
Recovery Speed: Restores data at >50MB/second
Validation Time: Validates backups in <30 seconds
Dashboard Response: API responses under 200ms
Memory Usage: System operates under 512MB RAM
Production Readiness ✅
Distributed Coordination: Prevents duplicate backups across nodes
Error Handling: Graceful failure recovery with detailed logging
Configuration Management: Environment-specific settings support
Monitoring Integration: Comprehensive metrics and alerting
Scalability: Horizontal scaling with Redis coordination
Troubleshooting Common Issues
Backup Creation Failures
# Check disk space
df -h .
# Ensure logs directory exists and has sample data
ls -la logs/

# Manual backup test
cd src && python backup/backup_engine.py
Recovery Issues
# Verify backup files exist
ls -la backups/
# Test manual recovery
cd src && python recovery/recovery_manager.py list
cd src && python recovery/recovery_manager.py recover <backup_id>
Dashboard Connection Problems
# Check port availability
netstat -tlnp | grep 8105
# Restart services
./stop.sh && ./start.sh
Redis Coordination Issues
# Test Redis connection
redis-cli ping
# Start Redis if needed
redis-server --daemonize yes
Success Criteria
By lesson completion, your system will:
✅ Create automated full backups on configurable schedules
✅ Perform incremental backups with configurable frequency
✅ Validate backup integrity using multiple verification methods
✅ Restore data to any point-in-time within retention window
✅ Handle distributed coordination across multiple storage nodes
✅ Provide real-time monitoring dashboard with backup status
✅ Meet 99.9% backup success rate with sub-15-minute recovery times
Real-World Applications
This implementation mirrors backup strategies at:
Amazon RDS: Multi-AZ backups with point-in-time recovery
Google Cloud Logging: Automated backup with configurable retention
Elasticsearch Cloud: Snapshot-based backup with incremental compression
MongoDB Atlas: Continuous backup with instant recovery capabilities
The patterns you implement today form the foundation for enterprise-grade data protection that scales to petabyte-level distributed systems.
Assignment Challenge
Objective: Implement automated backup rotation that maintains only the last 7 days of backups while preserving weekly snapshots for 30 days.
Implementation Approach:
Extend
BackupEnginewith retention policy logicAdd scheduled cleanup job to
BackupSchedulerImplement backup classification (daily vs weekly)
Create validation to ensure critical backups aren't deleted
Add monitoring for storage utilization trends
Success Criteria:
Storage usage stabilizes after initial growth period
Weekly snapshots preserved beyond daily retention window
Cleanup operations logged and monitored
Recovery capabilities maintained across retention boundaries
Solution Hints: Use backup metadata timestamps to classify backups by age and frequency. Implement protection flags for critical backups. Add storage monitoring to dashboard for retention policy effectiveness tracking.
This assignment mirrors production requirements where backup storage costs must be balanced against recovery needs and compliance requirements.
What You've Accomplished
You now have a production-ready automated backup and recovery system that can handle thousands of log messages per second with reliability guarantees. This foundation enables the scalable log processing architecture you'll complete in upcoming lessons.
Key Capabilities Unlocked:
Reliable backup persistence across system restarts
Automatic load balancing across multiple storage backends
Visual monitoring through comprehensive dashboards
Production deployment using Docker containers
Performance optimization achieving 10MB/s+ backup throughput
This foundation will be crucial for building resilient distributed logging systems in upcoming lessons. Tomorrow's multi-tenant architecture will build directly on these backup capabilities, ensuring tenant data isolation extends to backup and recovery operations.