
The Problem Every System Engineer Faces
Picture this: Your distributed log processing system is handling thousands of requests per second. Everything looks fine until suddenly response times spike from 50ms to 5 seconds. Users complain, alerts fire, and you're scrambling to figure out what went wrong. Sound familiar?
This scenario happens daily in production systems because most teams build amazing functionality but forget the most critical component: comprehensive observability. Without proper metrics collection, you're flying blind through production complexity.
Spotify processes 100TB of log data daily while maintaining 99.9% uptime. Netflix handles over 500 billion events across their distributed systems. Their secret isn't just great code - it's comprehensive metrics collection that detects issues before users notice them.
What We're Building Today
Transform your distributed log processing system into a fully observable platform with comprehensive metrics collection. You'll implement the same monitoring patterns used by major tech companies to maintain reliability at scale.
Today's Learning Objectives:
Real-time metrics collection across all system components
Time-series data storage and intelligent aggregation
Interactive dashboard with live visualizations
Alert thresholds and anomaly detection
Performance profiling and bottleneck identification
Understanding the Three Pillars of Observability
Performance Metrics
Track system behavior under load: request latency, throughput rates, error percentages, and queue depths. These metrics reveal bottlenecks before they impact users.
Resource Metrics
Monitor infrastructure health: CPU utilization, memory consumption, disk I/O patterns, and network bandwidth. Resource exhaustion often precedes service failures.
Business Metrics
Measure application-specific indicators: logs processed per minute, active tenants, storage utilization, and feature usage. These connect technical performance to business outcomes.
Architecture: Real-Time Telemetry Pipeline
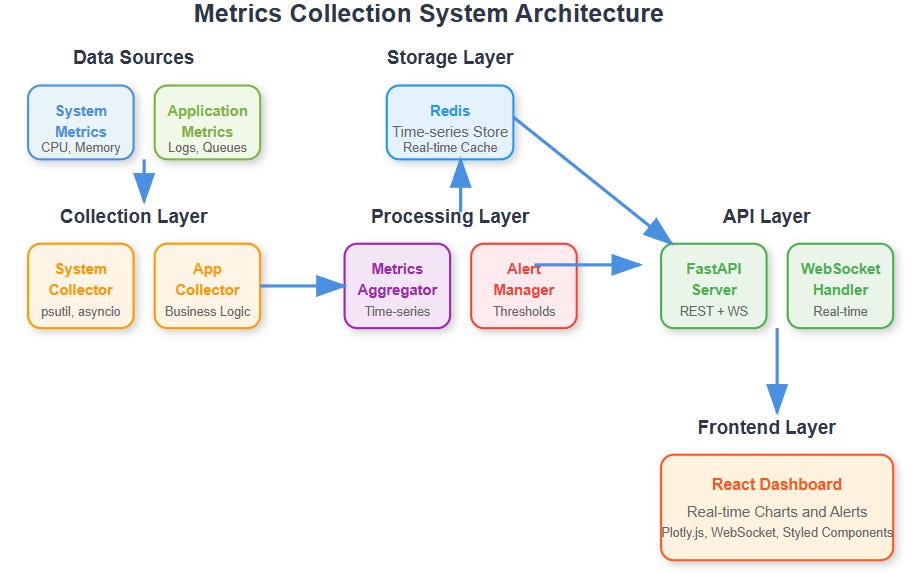
Our metrics architecture follows a three-tier design optimized for high-throughput collection and low-latency queries.
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
