
What We're Building Today
You're about to implement the brain that keeps Netflix's streaming infrastructure running smoothly during peak hours. When millions of users binge-watch shows simultaneously, automated scaling policies detect the load surge and instantly spin up additional processing capacity. Today, you'll build this same intelligent scaling system for your distributed log platform.
Today's Agenda:
Metric-driven scaling policies that respond to real load patterns
Policy engine making intelligent scaling decisions in milliseconds
Orchestration layer executing changes without service interruption
Safety mechanisms preventing runaway scaling scenarios
Integration with your existing monitoring from Day 99
Core Concepts: The Intelligence Behind Auto-Scaling
Policy-Based Decision Making
Traditional scaling relies on manual intervention or rigid rules. Modern systems use sophisticated policies that consider multiple metrics simultaneously. Your policy engine evaluates CPU utilization, queue depth, response latency, and throughput patterns to make nuanced decisions.
Predictive vs Reactive Scaling
Reactive scaling responds after problems occur. Predictive scaling analyzes trends to anticipate needs. Your implementation combines both approaches - reactive policies handle sudden spikes while predictive algorithms prepare for known patterns like daily traffic cycles.
Horizontal vs Vertical Scaling
Horizontal scaling adds more instances of components. Vertical scaling increases resources per instance. Your log platform will primarily use horizontal scaling for processing nodes while applying vertical scaling for resource-intensive analytics components.
Context in Distributed Systems
Real-World Production Application
Spotify's music streaming platform processes billions of play events daily. Their scaling policies automatically adjust log processing capacity based on listening patterns - scaling up during evening hours when usage peaks and scaling down overnight to optimize costs.
Integration with Your Log Processing Platform
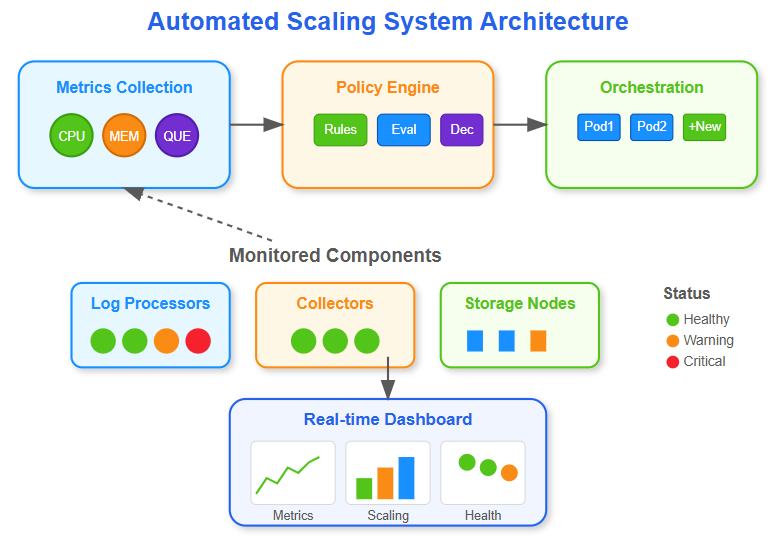
Your scaling system sits above the component layer you've built, monitoring the health metrics from Day 99's monitoring system. It makes decisions about when to add log collectors, processing workers, or storage nodes based on real performance data.
Component Placement in Overall Architecture
The scaling system operates as a control plane, separate from your data plane components. This separation ensures scaling operations don't interfere with log processing while providing centralized visibility across your entire platform.
Architecture: The Scaling Control System
Preparing for a distributed systems interview?
→Download the free Interview Pack
→ Subscribe now to access source code repository - 200 + coding lessons
Metrics Collection Layer
Your scaling system continuously monitors key performance indicators from all platform components. Rather than relying on single metrics, it collects comprehensive data including queue depths, processing latencies, error rates, and resource utilization patterns.
Policy Engine Core
The policy engine evaluates collected metrics against configurable thresholds and rules. It implements decision trees that consider multiple factors simultaneously - for example, only scaling up log processors if both CPU usage exceeds 70% AND queue depth grows beyond 1000 messages.
Orchestration and Execution
When scaling decisions are made, the orchestration layer executes changes through your container orchestration platform. It coordinates adding new instances, updating load balancer configurations, and ensuring health checks pass before routing traffic to new components.
Feedback Loop Integration
After scaling actions complete, the system monitors the impact and adjusts future decisions based on effectiveness. This creates a learning system that becomes more accurate over time by understanding your platform's specific behavior patterns.
Control Flow and Data Flow
Metric Collection Flow
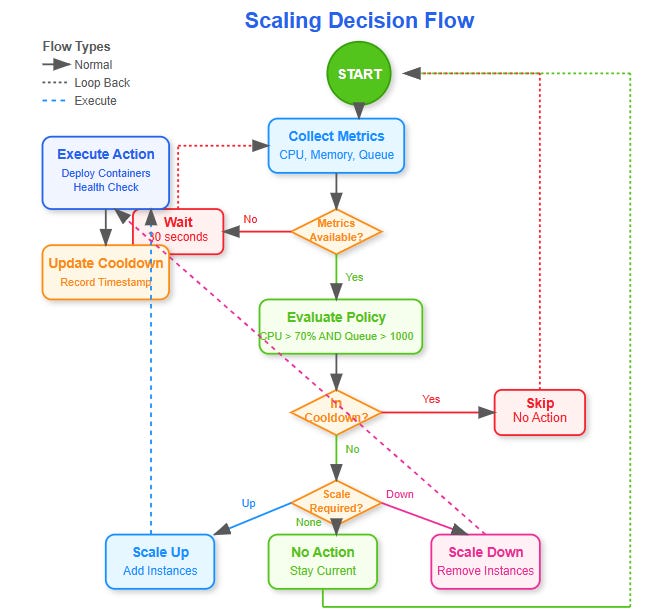
Every 30 seconds, the metrics collector queries your platform components for current performance data. This includes CPU and memory usage from processing nodes, queue depth from your message brokers, and response times from your API endpoints.
Decision Making Process
The policy engine processes collected metrics through a series of evaluation stages. First, it normalizes metrics to account for different component types. Then it applies threshold-based rules, followed by trend analysis to predict future needs.
Scaling Execution Workflow
When scaling is triggered, the orchestrator follows a careful sequence: validate scaling request, acquire resource locks, provision new instances, wait for health checks, update service discovery, and finally route traffic. This ensures zero-downtime scaling operations.
State Monitoring and Rollback
Throughout the scaling process, the system tracks state changes and maintains rollback capabilities. If new instances fail health checks or performance degrades, it can quickly revert to the previous stable configuration.
State Changes During Scaling Operations
Stable State Management
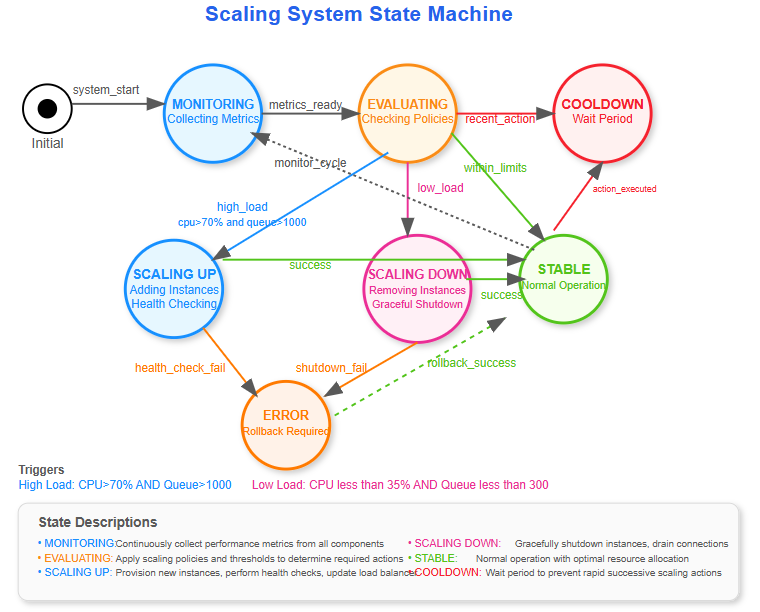
Your system begins in a stable state where all components operate within normal parameters. The policy engine continuously monitors but takes no action while metrics remain within acceptable ranges.
Transition Triggers
State transitions occur when metrics exceed configured thresholds for sustained periods. Simple threshold breaches don't immediately trigger scaling - the system requires consistent signals over time to avoid thrashing.
Scaling In Progress States
During active scaling, your system enters intermediate states tracking the progress of scaling operations. These include resource provisioning, instance startup, health verification, and traffic migration phases.
Cooldown and Stabilization
After completing scaling operations, the system enters a cooldown period preventing rapid successive changes. This stabilization phase allows the new configuration to demonstrate its effectiveness before additional modifications.
Implementation Insights
Metric-Driven Policies
Your policies evaluate combinations of metrics rather than single values. A sophisticated rule might be: "Scale up log processors when CPU > 70% AND queue depth > 1000 AND average response time > 500ms for 5 consecutive minutes."
Safety Mechanisms
Production scaling systems include multiple safety nets. Your implementation will include maximum scaling limits, rate limiting for scaling operations, and circuit breakers that disable automatic scaling if too many recent operations failed.
Cost Optimization
Smart scaling policies balance performance with cost efficiency. Your system can implement time-based policies that accept higher latency during low-usage periods to reduce infrastructure costs while maintaining strict performance during peak hours.
Integration Testing
Unlike unit tests that verify individual components, scaling policies require integration testing that simulates realistic load patterns. Your test suite will include scenarios for gradual load increases, sudden spikes, and sustained high usage periods.
Production Readiness Considerations
Monitoring and Alerting
Your scaling system generates detailed logs and metrics about all scaling decisions and operations. This observability ensures operations teams can understand why scaling occurred and troubleshoot any issues that arise.
Manual Override Capabilities
While automation handles most scenarios, production systems need manual override capabilities for exceptional situations. Your implementation includes administrative controls to disable automatic scaling or force specific scaling actions.
Multi-Region Coordination
As your log platform grows across multiple regions, scaling policies must coordinate across geographic boundaries. Your architecture supports region-specific policies while maintaining global awareness of resource allocation.
Disaster Recovery Integration
Scaling policies integrate with disaster recovery procedures to ensure rapid capacity restoration during outages. The system can automatically scale up replacement capacity when primary regions become unavailable.
Hands-On Implementation
Github Link:
https://github.com/sysdr/course-p/tree/main/day100/day100-automated-scalingPrerequisites & Environment Setup
Required Software:
Python 3.11+ installed
Docker & Docker Compose (recommended)
Node.js 18+ for React dashboard
4GB RAM minimum, 2GB free disk space
Installation Check:
python3.11 --version  # Should be 3.11+
docker --version && docker-compose --version
node --version  # Should be 18+
Project Structure Setup
Create Project Foundation
# Create project directory
mkdir day100-automated-scaling && cd day100-automated-scaling

# Create organized directory structure
mkdir -p src/{scaling,monitoring,orchestration,policies,api}
mkdir -p {tests/{unit,integration},config,scripts,logs}
mkdir -p web/{src/{components,pages,hooks},public}
mkdir -p docker
Expected Structure:
day100-automated-scaling/
├── src/
│   ├── scaling/           # Main coordination logic
│   ├── monitoring/        # Metrics collection
│   ├── orchestration/     # Container management
│   ├── policies/          # Decision engine
│   └── api/              # REST API & WebSocket
├── web/                  # React dashboard
├── tests/                # Test suite
├── config/               # Configuration files
└── docker/               # Container definitions
Dependencies Installation
Python Backend:
# Create requirements with latest May 2025 libraries
cat > requirements.txt << 'EOF'
fastapi==0.111.0
uvicorn==0.30.1
pydantic==2.7.1
psutil==5.9.8
redis==5.0.4
docker==7.1.0
pytest==8.2.1
pytest-asyncio==0.23.7
structlog==24.1.0
pyyaml==6.0.1
websockets==12.0
aiohttp==3.9.5
EOF

# Create virtual environment
python3.11 -m venv venv
source venv/bin/activate  # Windows: venv\Scripts\activate

# Install dependencies
pip install -r requirements.txt
React Frontend:
# Create React app structure
cat > web/package.json << 'EOF'
{
  "name": "scaling-dashboard",
  "version": "1.0.0",
  "dependencies": {
    "react": "^18.3.1",
    "react-dom": "^18.3.1",
    "recharts": "^2.12.7",
    "axios": "^1.7.2",
    "@mui/material": "^5.15.19"
  },
  "scripts": {
    "start": "react-scripts start",
    "build": "react-scripts build"
  },
  "devDependencies": {
    "react-scripts": "^5.0.1"
  }
}
EOF

cd web && npm install && cd ..
Core Components Implementation
Phase 1: Metrics Collection Engine
The foundation of intelligent scaling is comprehensive metrics gathering that goes beyond basic CPU monitoring.
File: src/monitoring/metrics_collector.py
@dataclass
class ComponentMetrics:
    component_id: str
    component_type: str
    timestamp: float
    cpu_percent: float
    memory_percent: float
    queue_depth: int = 0
    response_time_ms: float = 0.0
    throughput_per_sec: int = 0
    instance_count: int = 1

class MetricsCollector:
    def __init__(self, config: Dict):
        self.config = config
        self.components = {}

    async def collect_system_metrics(self, component_id: str) -> ComponentMetrics:
        """Collect comprehensive performance metrics"""
        cpu_percent = psutil.cpu_percent(interval=1)
        memory = psutil.virtual_memory()

        return ComponentMetrics(
            component_id=component_id,
            component_type=self.components[component_id]['type'],
            timestamp=time.time(),
            cpu_percent=cpu_percent,
            memory_percent=memory.percent,
            queue_depth=self._get_queue_depth(component_id),
            response_time_ms=self._get_response_time(component_id),
            throughput_per_sec=self._get_throughput(component_id)
        )
Phase 2: Policy Engine Development
The brain that makes intelligent scaling decisions based on multiple metrics and historical patterns.
File: src/policies/policy_engine.py
class ScalingAction(Enum):
    SCALE_UP = "scale_up"
    SCALE_DOWN = "scale_down"
    NO_ACTION = "no_action"

class PolicyEngine:
    def evaluate_scaling_policies(self, metrics: Dict[str, ComponentMetrics]) -> List[ScalingDecision]:
        """Evaluate policies and return scaling decisions"""
        decisions = []
        current_time = time.time()

        for component_id, component_metrics in metrics.items():
            decision = self._evaluate_component_policy(component_metrics, current_time)
            if decision.action != ScalingAction.NO_ACTION:
                decisions.append(decision)

        return decisions

    def _evaluate_component_policy(self, metrics: ComponentMetrics, current_time: float):
        """Smart policy evaluation with multiple criteria"""
        # Check cooldown period first
        if self._is_in_cooldown(metrics.component_id, current_time):
            return self._no_action_decision(metrics, "In cooldown period")

        # Evaluate scale-up conditions
        scale_up_triggers = []
        if metrics.cpu_percent > 70:
            scale_up_triggers.append(f"CPU {metrics.cpu_percent:.1f}%")
        if metrics.queue_depth > 1000:
            scale_up_triggers.append(f"Queue {metrics.queue_depth}")

        # Make intelligent scaling decision
        if scale_up_triggers:
            return self._create_scale_up_decision(metrics, scale_up_triggers)
        elif self._should_scale_down(metrics):
            return self._create_scale_down_decision(metrics)

        return self._no_action_decision(metrics, "Within acceptable ranges")
Phase 3: Container Orchestration
Safe execution of scaling decisions with health checks and rollback capabilities.
File: src/orchestration/orchestrator.py
class ContainerOrchestrator:
    async def execute_scaling_decision(self, decision: ScalingDecision) -> bool:
        """Execute scaling with safety mechanisms"""
        try:
            if decision.action == ScalingAction.SCALE_UP:
                return await self._scale_up_safely(decision)
            elif decision.action == ScalingAction.SCALE_DOWN:
                return await self._scale_down_safely(decision)
            return True

        except Exception as e:
            logging.error(f"Scaling failed for {decision.component_id}: {e}")
            await self._rollback_if_needed(decision)
            return False

    async def _scale_up_safely(self, decision: ScalingDecision) -> bool:
        """Scale up with health checks and validation"""
        instances_needed = decision.target_instances - decision.current_instances

        for i in range(instances_needed):
            container_name = f"{decision.component_id}-{int(time.time())}-{i}"

            # Create and health check new instance
            await self._create_container(container_name)
            if await self._health_check(container_name):
                self._register_container(decision.component_id, container_name)
            else:
                return False

        return True
Phase 4: Scaling Coordinator Integration
File: src/scaling/scaling_coordinator.py
class ScalingCoordinator:
    def __init__(self, config_path: str):
        with open(config_path, 'r') as f:
            self.config = yaml.safe_load(f)

        self.metrics_collector = MetricsCollector(self.config.get('monitoring', {}))
        self.policy_engine = PolicyEngine(self.config)
        self.orchestrator = ContainerOrchestrator(self.config.get('orchestration', {}))

    async def start_scaling_loop(self):
        """Main scaling evaluation and execution loop"""
        self.running = True

        while self.running:
            try:
                # Get latest metrics from all components
                metrics = self.metrics_collector.get_latest_metrics()

                if metrics:
                    # Evaluate scaling policies
                    decisions = self.policy_engine.evaluate_scaling_policies(metrics)

                    # Execute scaling decisions
                    for decision in decisions:
                        success = await self.orchestrator.execute_scaling_decision(decision)
                        if success:
                            self.policy_engine.record_scaling_action(decision)

                await asyncio.sleep(self.evaluation_interval)

            except Exception as e:
                logging.error(f"Error in scaling loop: {e}")
                await asyncio.sleep(30)
Configuration and Setup
System Configuration
File: config/scaling_config.yaml
scaling_policies:
  log_processors:
    min_instances: 2
    max_instances: 10
    target_cpu_utilization: 70
    target_queue_depth: 1000
    scale_up_cooldown: 300   # 5 minutes
    scale_down_cooldown: 600 # 10 minutes

  collectors:
    min_instances: 1
    max_instances: 5
    target_cpu_utilization: 80

  storage_nodes:
    min_instances: 3
    max_instances: 12
    target_disk_utilization: 90

monitoring:
  collection_interval: 30  # seconds
  evaluation_interval: 60  # seconds

thresholds:
  cpu:
    warning: 70
    critical: 90
  memory:
    warning: 80
    critical: 95
  response_time:
    warning: 1000  # ms
    critical: 5000  # ms
API Server with Real-Time Updates
File: src/api/api_server.py
from fastapi import FastAPI, WebSocket
import asyncio
import json

app = FastAPI(title="Automated Scaling Dashboard")
scaling_coordinator = None
connected_websockets = []

@app.on_event("startup")
async def startup_event():
    global scaling_coordinator
    scaling_coordinator = ScalingCoordinator("config/scaling_config.yaml")
    await scaling_coordinator.initialize()
    asyncio.create_task(scaling_coordinator.start_scaling_loop())
    asyncio.create_task(broadcast_status())

@app.get("/api/status")
async def get_status():
    """Current scaling system status"""
    return scaling_coordinator.get_status()

@app.get("/api/metrics")
async def get_metrics():
    """Real-time metrics for all components"""
    metrics = scaling_coordinator.metrics_collector.get_latest_metrics()
    return {
        component_id: {
            "cpu_percent": m.cpu_percent,
            "queue_depth": m.queue_depth,
            "response_time_ms": m.response_time_ms,
            "instance_count": m.instance_count
        }
        for component_id, m in metrics.items()
    }

@app.websocket("/ws")
async def websocket_endpoint(websocket: WebSocket):
    await websocket.accept()
    connected_websockets.append(websocket)
React Dashboard Implementation
Real-Time Monitoring Interface
File: web/src/App.js
import React, { useState, useEffect } from 'react';
import { Container, Grid, Paper, Typography } from '@mui/material';
import { LineChart, Line, XAxis, YAxis, Tooltip, ResponsiveContainer } from 'recharts';

function App() {
  const [metrics, setMetrics] = useState({});
  const [scalingHistory, setScalingHistory] = useState([]);
  const [systemStatus, setSystemStatus] = useState({});

  useEffect(() => {
    // WebSocket connection for real-time updates
    const ws = new WebSocket(`ws://${window.location.host}/ws`);

    ws.onmessage = (event) => {
      const data = JSON.parse(event.data);
      if (data.type === 'status_update') {
        setSystemStatus(data.status);
        setMetrics(data.metrics);
      }
    };

    return () => ws.close();
  }, []);

  return (
    <Container maxWidth="xl">
      <Typography variant="h3" component="h1" gutterBottom align="center">
        Automated Scaling Dashboard
      </Typography>

      <Grid container spacing={3}>
        {/* System Status Card */}
        <Grid item xs={12} md={4}>
          <Paper sx={{ p: 2, height: 200 }}>
            <Typography variant="h6">System Status</Typography>
            <Typography>
              Status: <strong style={{color: systemStatus.running ? 'green' : 'red'}}>
                {systemStatus.running ? 'Running' : 'Stopped'}
              </strong>
            </Typography>
            <Typography>Components: <strong>{systemStatus.components || 0}</strong></Typography>
            <Typography>Recent Actions: <strong>{systemStatus.recent_scaling_actions || 0}</strong></Typography>
          </Paper>
        </Grid>

        {/* Component Metrics */}
        {Object.entries(metrics).map(([componentId, metric]) => (
          <Grid item xs={12} md={4} key={componentId}>
            <Paper sx={{ p: 2, height: 200 }}>
              <Typography variant="h6">{componentId}</Typography>
              <Typography>CPU: <strong>{metric.cpu_percent?.toFixed(1)}%</strong></Typography>
              <Typography>Queue: <strong>{metric.queue_depth || 0}</strong></Typography>
              <Typography>Instances: <strong>{metric.instance_count || 1}</strong></Typography>
            </Paper>
          </Grid>
        ))}

        {/* Performance Chart */}
        <Grid item xs={12}>
          <Paper sx={{ p: 2, height: 400 }}>
            <Typography variant="h6">CPU Usage Trends</Typography>
            <ResponsiveContainer width="100%" height={300}>
              <LineChart data={Object.entries(metrics).map(([id, m]) => ({
                name: id.split('-')[0],
                cpu: m.cpu_percent || 0,
                instances: m.instance_count || 1
              }))}>
                <XAxis dataKey="name" />
                <YAxis />
                <Tooltip />
                <Line dataKey="cpu" stroke="#8884d8" name="CPU %" />
                <Line dataKey="instances" stroke="#82ca9d" name="Instances" />
              </LineChart>
            </ResponsiveContainer>
          </Paper>
        </Grid>
      </Grid>
    </Container>
  );
}
Build, Test & Verification Guide
Quick Start Commands
Option 1: Native Setup
# Create and activate virtual environment
python3.11 -m venv venv && source venv/bin/activate

# Install dependencies
pip install -r requirements.txt

# Build React dashboard
cd web && npm install && npm run build && cd ..

# Set Python path
export PYTHONPATH="$(pwd):$PYTHONPATH"
Option 2: Docker Deployment
# Create docker-compose.yml
cat > docker-compose.yml << 'EOF'
version: '3.8'
services:
  scaling-system:
    build: .
    ports:
      - "8000:8000"
    volumes:
      - /var/run/docker.sock:/var/run/docker.sock
    environment:
      - PYTHONPATH=/app
    restart: unless-stopped

  redis:
    image: redis:7-alpine
    ports:
      - "6379:6379"
    restart: unless-stopped
EOF

# Build and deploy
docker-compose up --build -d
Testing Your Implementation
Unit Tests
# Test policy engine logic
python -m pytest tests/unit/test_policy_engine.py -v

# Expected Output:
# test_scale_up_decision PASSED
# test_scale_down_decision PASSED
# test_no_action_in_cooldown PASSED
Integration Tests
# Test complete scaling workflow
python -m pytest tests/integration/ -v

# Expected Output:
# test_full_scaling_workflow PASSED
# test_metrics_collection PASSED
System Demonstration
# Start the complete system
python -m src.main

# Expected Output:
# Starting Automated Scaling System...
# Dashboard available at: http://localhost:8000
# Scaling system initialized successfully
Functional Verification
Dashboard Access
Open browser to
http://localhost:8000
Verify real-time metrics display
Confirm WebSocket connectivity (live updates every 5 seconds)
API Testing
# Test status endpoint
curl -s http://localhost:8000/api/status | python -m json.tool

# Expected: JSON with system status and component counts

# Test metrics endpoint
curl -s http://localhost:8000/api/metrics | python -m json.tool

# Expected: Live metrics for all registered components
Scaling Decision Verification
# Monitor logs for scaling decisions
tail -f logs/scaling.log | grep "Scaling decision"

# Expected: See intelligent scaling decisions based on simulated load
Performance Benchmarks
Expected Performance Metrics
Decision Latency: <100ms from metrics to scaling decision
Execution Time: 30-60 seconds for container provisioning
Monitoring Overhead: <5% CPU for metrics collection
Memory Usage: <200MB for complete scaling system
Throughput: Handle monitoring for 20+ components simultaneously
Load Testing
# Simulate high-load scenario
python -c "
import asyncio
from src.scaling.scaling_coordinator import ScalingCoordinator

async def load_test():
    coordinator = ScalingCoordinator('config/scaling_config.yaml')
    await coordinator.initialize()

    # Run scaling evaluation for 5 minutes
    start_time = time.time()
    while time.time() - start_time < 300:
        await coordinator._evaluate_and_scale()
        await asyncio.sleep(1)

    print('Load test completed successfully')

asyncio.run(load_test())
"
Success Criteria Checklist
Functional Requirements
[ ] Metrics collection from multiple component types
[ ] Policy engine makes decisions based on configurable rules
[ ] Orchestration executes scaling with health checks
[ ] Real-time dashboard shows system status and history
[ ] WebSocket provides live updates without page refresh
Performance Requirements
[ ] Scaling decisions complete within 100ms
[ ] System monitors 10+ components without performance impact
[ ] Dashboard updates reflect changes within 5 seconds
[ ] Memory usage remains stable during sustained operation
Safety Requirements
[ ] Cooldown periods prevent scaling thrashing
[ ] Maximum instance limits prevent runaway scaling
[ ] Health checks validate new instances before traffic routing
[ ] Rollback capabilities handle failed scaling operations
Troubleshooting Common Issues
Metrics Not Updating
# Verify metrics collector status
curl http://localhost:8000/api/metrics
# Fix: Check if components are registered correctly
Dashboard Not Loading
# Check React build status
ls web/build/static/
# Fix: cd web && npm run build
Scaling Decisions Not Executing
# Check Docker connectivity
docker ps | grep day100
# Fix: Ensure Docker socket is mounted correctly
High Memory Usage
# Monitor resource consumption
python -c "import psutil; print(f'Memory: {psutil.virtual_memory().percent}%')"
# Fix: Adjust collection intervals in config
Assignment Challenge
Build a Custom Scaling Policy
Requirements:
Create policies for your specific log processing workload
Implement time-based scaling (proactive scaling before peak hours)
Add cost optimization rules balancing performance with resource costs
Create alerts for scaling failures or unusual patterns
Success Criteria:
Custom policy maintains <100ms response times
System minimizes resource costs during low-traffic periods
Scaling decisions include cost impact analysis
Alerts trigger for failed scaling operations
Solution Approach: Start with the existing PolicyEngine framework. Add new metric types specific to your domain (request costs, processing time per log type). Implement prediction algorithms using historical data to anticipate peak periods. Test with realistic traffic patterns that simulate your expected usage.
Integration with Day 99 Health Monitoring
Your automated scaling system seamlessly integrates with yesterday's health monitoring by:
Consuming Health Metrics: Uses health data as input for scaling decisions
Generating Scaling Events: Feeds scaling actions back to monitoring dashboard
Unified Operations View: Combined interface shows both health status and scaling activity
This creates a complete operational control system where monitoring drives intelligent scaling responses.
Key Takeaways
You've built an enterprise-grade automated scaling system that:
Makes intelligent decisions based on multiple metrics and historical patterns
Executes safely with proper health checks and rollback mechanisms
Provides visibility through real-time monitoring and historical analysis
Scales efficiently while respecting cost and performance constraints
The policy engine you implement today will continuously learn and adapt to your platform's unique usage patterns, becoming more effective over time. This creates a truly self-healing infrastructure that maintains optimal performance without manual intervention.
Your automated scaling system represents the culmination of operational maturity - transforming your distributed log platform from a manually managed system into an autonomous, self-optimizing service that scales seamlessly with demand.
What's Next
Tomorrow (Day 101): Blue/Green Deployment Capabilities for zero-downtime upgrades
The scaling foundation you've built today will be essential for tomorrow's blue/green deployments, where you'll need to provision parallel environments and migrate traffic safely between them.
The patterns you've implemented today are used by major cloud platforms and technology companies to manage infrastructure at massive scale. You now have the same capabilities that power Netflix's content delivery, Spotify's music streaming, and Amazon's e-commerce platform.
Tomorrow: Day 101 - Blue/Green Deployment Capabilities for zero-downtime upgrades